Description
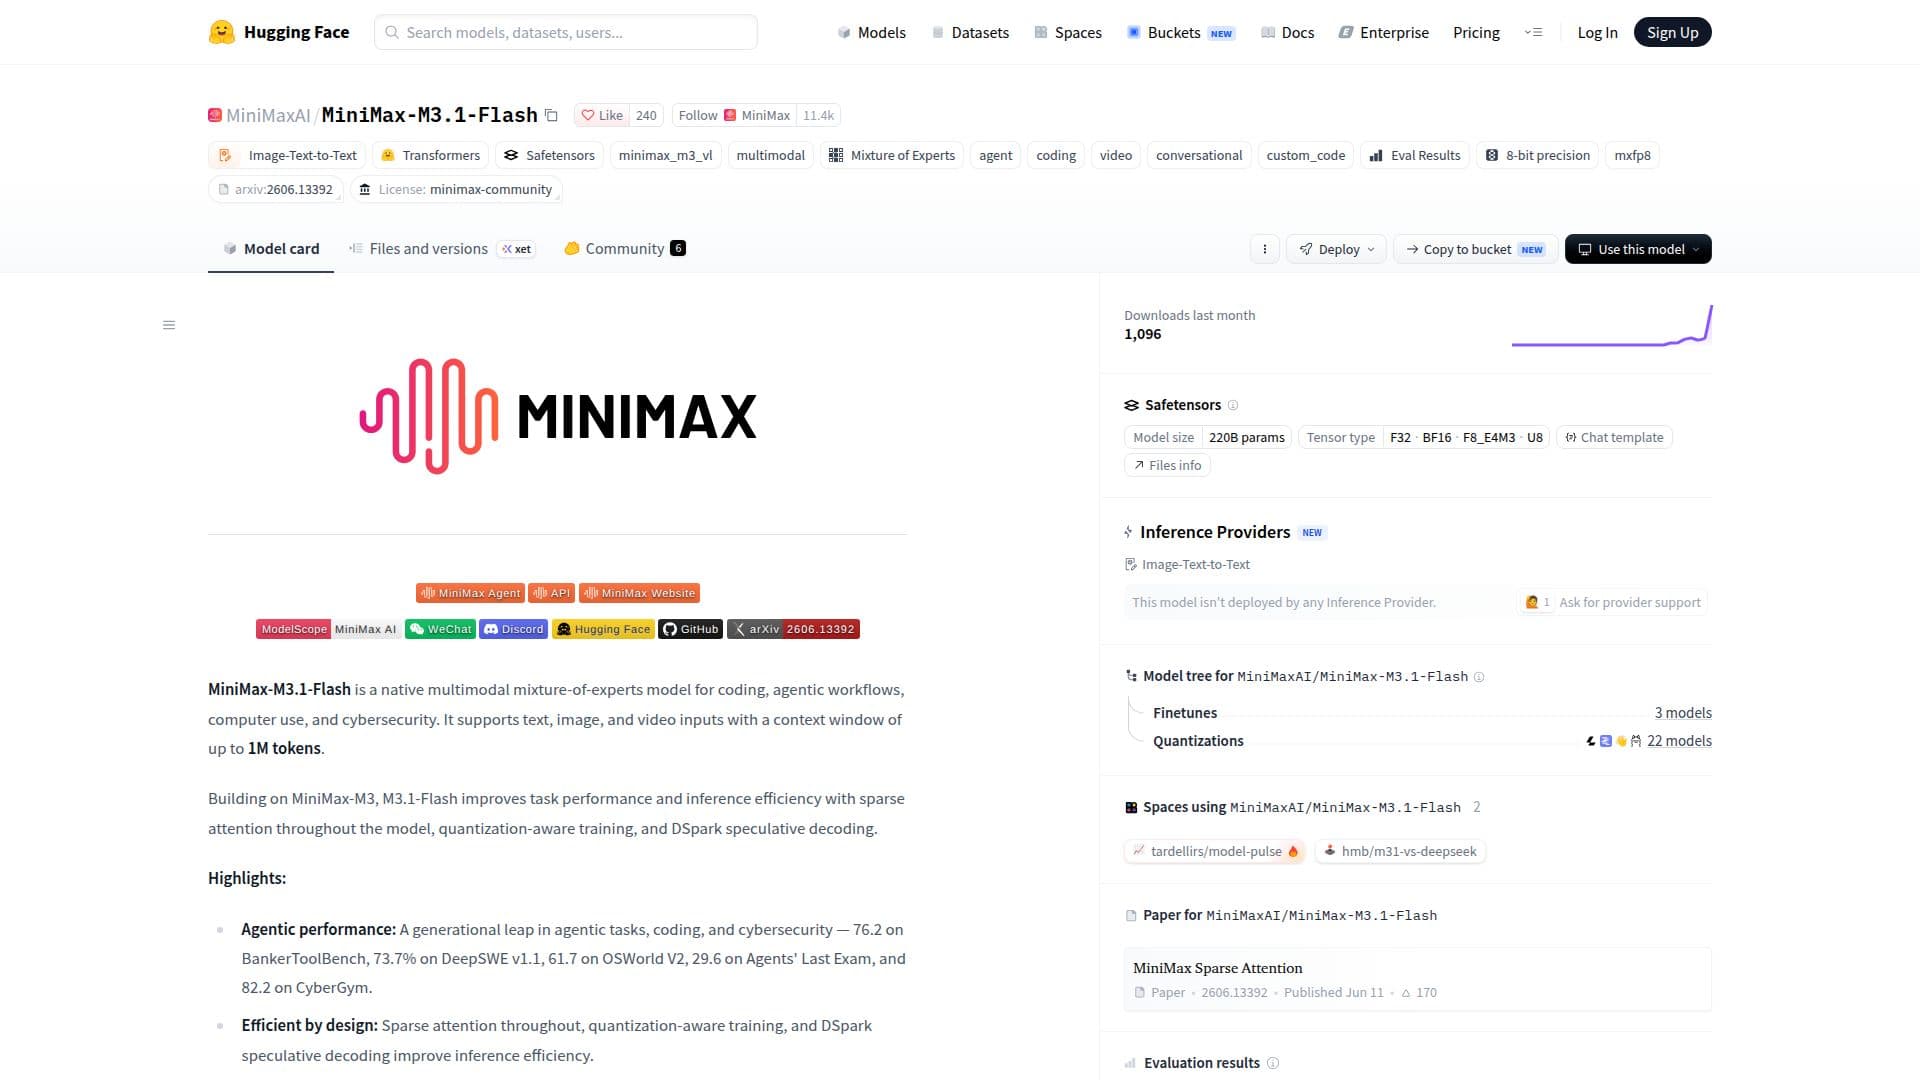
MiniMax-M3.1-Flash is an advanced multimodal mixture-of-experts model developed to enhance coding, agentic workflows, computer use, and cybersecurity. This model supports text, image, and video inputs, providing a context window of up to 1 million tokens. Building on the MiniMax-M3 architecture, M3.1-Flash introduces improvements in task performance and inference efficiency through the use of sparse attention throughout the model, quantization-aware training, and DSpark speculative decoding.
Read More
The model's architecture is designed to handle a wide range of inputs and outputs, with approximately 428 billion parameters, of which 23 billion are activated per token. This allows for efficient processing and high performance across various benchmarks, including a score of 76.2 on BankerToolBench and 82.2 on CyberGym.
M3.1-Flash is particularly noted for its agentic performance, offering a generational leap in tasks related to coding and cybersecurity. It achieves high scores on several benchmarks, such as 73.7% on DeepSWE v1.1 and 61.7 on OSWorld V2. The model's efficiency is further enhanced by features like sparse attention and quantization-aware training, which reduce memory footprint and improve serving efficiency.
For deployment, MiniMax-M3.1-Flash supports various inference frameworks, including SGLang, vLLM, and TokenSpeed, with additional integrations in progress. The model is designed for multi-chip deployment, offering flexibility in serving configurations. Users can adjust inference settings, such as temperature and top_p, to optimize performance for specific tasks.
Overall, MiniMax-M3.1-Flash is a powerful tool for developers and researchers looking to leverage advanced AI capabilities in multimodal contexts, providing robust support for complex workflows and cybersecurity applications.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsWeb
MiniMax-M3.1-Flash Highlights
Multimodal mixture-of-experts architecture
Supports text, image, and video inputs
Context window up to 1 million tokens
Sparse attention throughout the model
Quantization-aware training
DSpark speculative decoding
Approximately 428 billion parameters
High performance on multiple benchmarks
Getting Started with MiniMax-M3.1-Flash
Access model page: Visit the official Hugging Face page for MiniMax-M3.1-Flash
Authenticate: Ensure you have the necessary credentials to access the model
Configure: Set up the model with your preferred inference framework
Send prompts: Input text, image, or video data for processing
Fine-tune: Adjust settings like temperature and top_p for optimal results
MiniMax-M3.1-Flash's Use Cases
- Coding Assistance
- Cybersecurity
- Agentic Workflows
- Multimodal Processing
- Inference Efficiency