Description
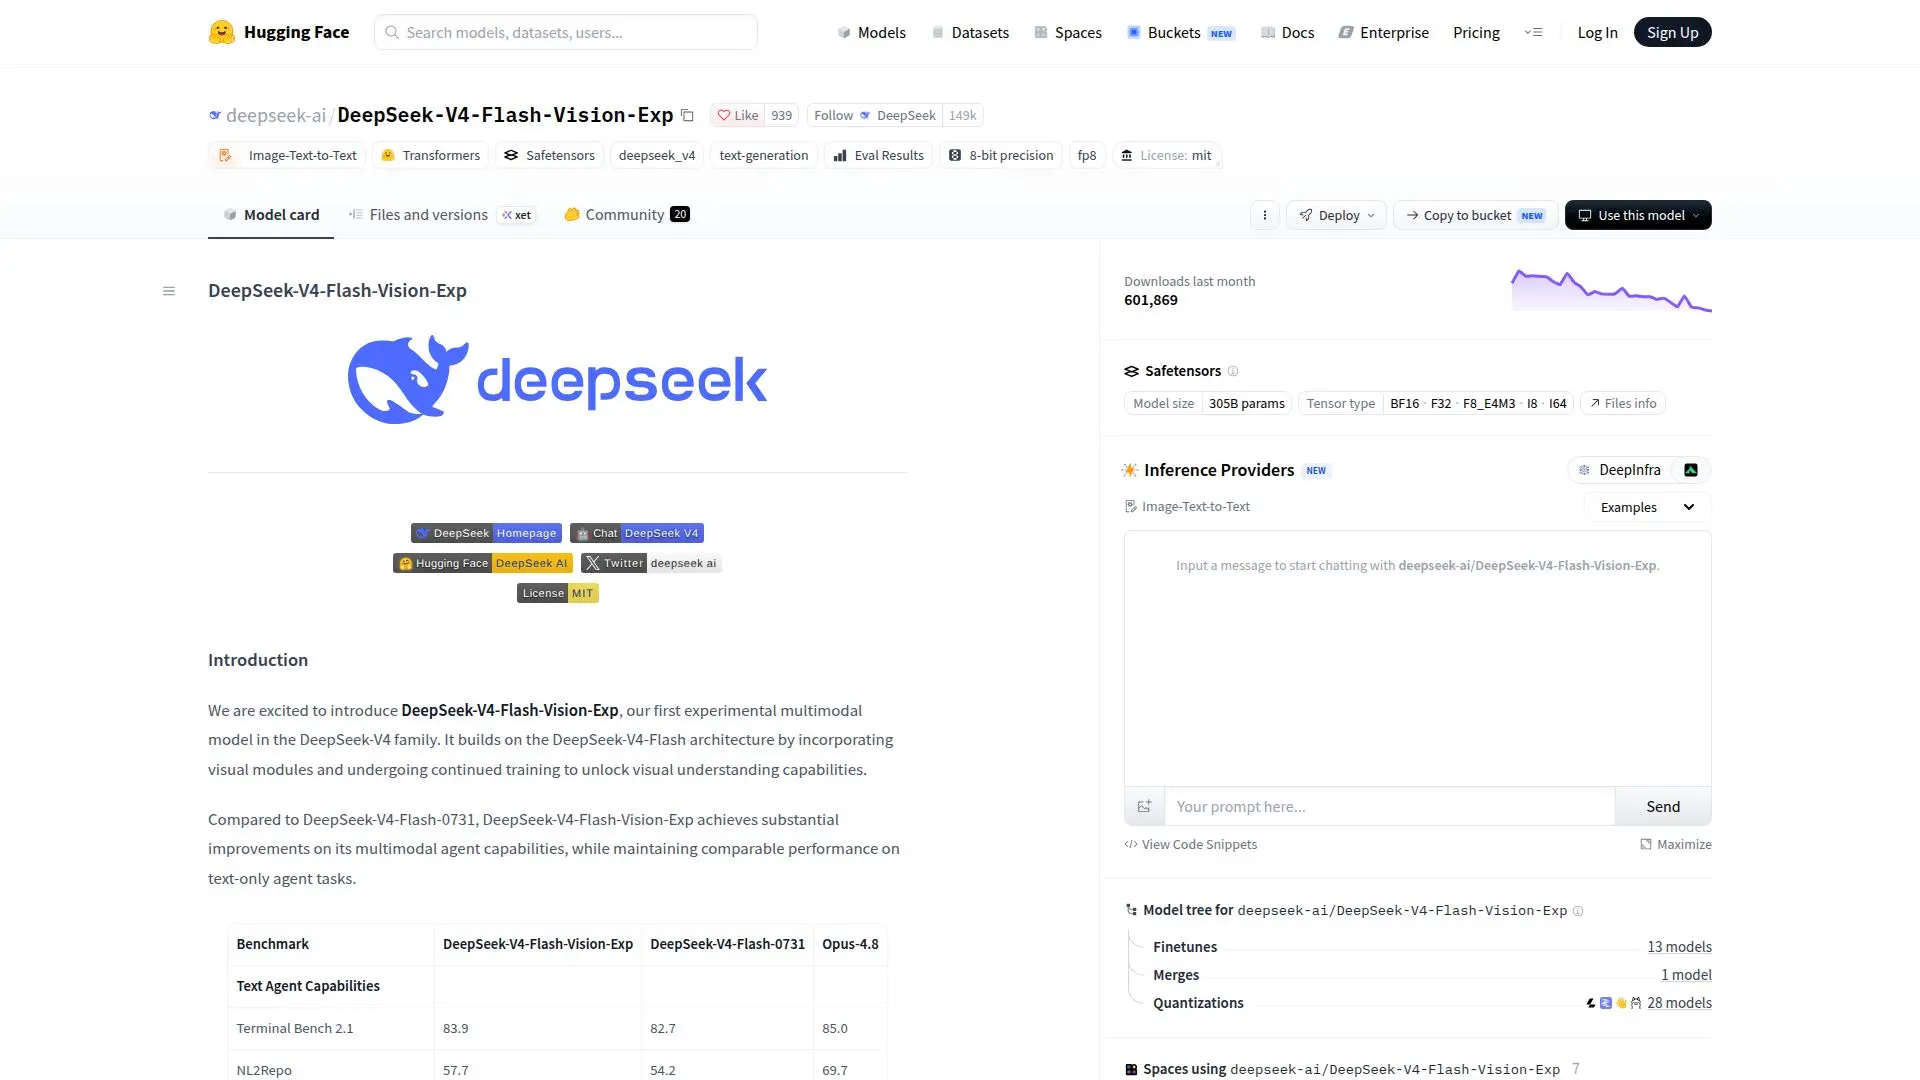
DeepSeek-V4-Flash-Vision-Exp is an innovative experimental multimodal model in the DeepSeek-V4 family. It enhances the existing DeepSeek-V4-Flash architecture by incorporating visual modules, which significantly improve its visual understanding capabilities. This model has undergone extensive training to ensure it delivers substantial improvements in multimodal agent capabilities, while maintaining comparable performance on text-only agent tasks.
Read More
The model has been benchmarked against several other models, showcasing its superior performance in various tasks. For instance, in the Terminal Bench 2.1, it scored 83.9, surpassing the DeepSeek-V4-Flash-0731. In the NL2Repo benchmark, it achieved a score of 57.7, again outperforming its predecessor. These benchmarks highlight the model's enhanced capabilities in handling complex multimodal tasks.
DeepSeek-V4-Flash-Vision-Exp is designed to be accessible and easy to use. The repository includes the tokenizer, prompt encoding reference, and a minimal PyTorch inference implementation. This setup allows users to efficiently utilize the model's vision encoder, aligner, DFlash attention, MoE, Hyper-Connections, and the DSpark forward path.
The model supports both OpenAI-style JSON content blocks and compact TXT notation for prompt encoding, ensuring flexibility in usage. Additionally, it can be run with vLLM and SGLang, providing users with various options for deployment based on their hardware configurations.
Licensed under the MIT License, DeepSeek-V4-Flash-Vision-Exp is part of an open-source initiative aimed at advancing and democratizing artificial intelligence through open science.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsWeb
DeepSeek-V4-Flash-Vision-Exp Highlights
Multimodal capabilities
Visual understanding
Enhanced text agent performance
Open source
PyTorch inference support
Benchmark performance
Prompt encoding flexibility
MIT License
Getting Started with DeepSeek-V4-Flash-Vision-Exp
Access model page: Visit the Hugging Face repository
Authenticate: Ensure you have access to the necessary resources
Configure: Set up the model using the provided instructions
Send prompts: Utilize the model's capabilities for your tasks
Fine-tune: Adjust the model parameters as needed
DeepSeek-V4-Flash-Vision-Exp's Use Cases
- Visual Understanding
- Multimodal Tasks
- AI Research
- Benchmark Testing
- Model Deployment