Description
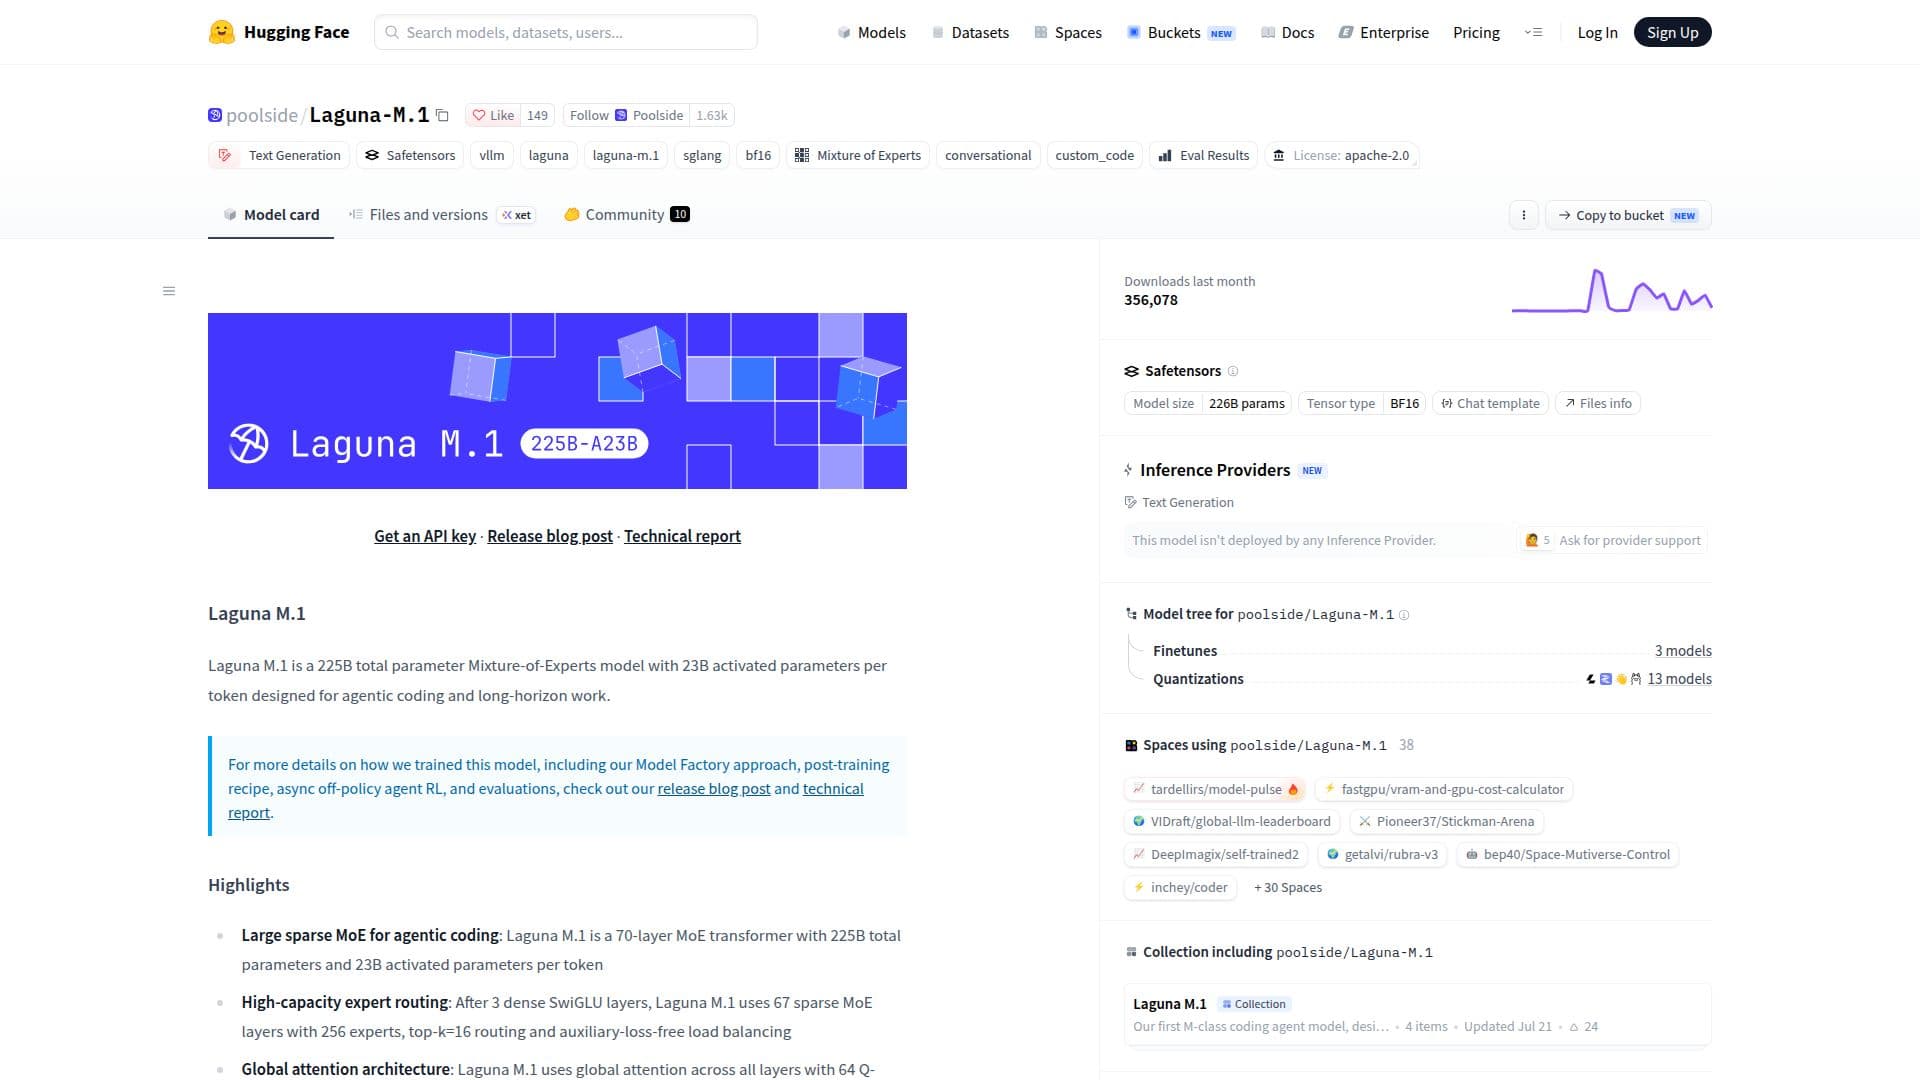
Laguna M.1 is a sophisticated Mixture-of-Experts (MoE) model developed for agentic coding and long-horizon tasks. With a total of 225 billion parameters and 23 billion activated parameters per token, it is engineered to handle complex computational tasks efficiently. The model consists of 70 layers, including 67 sparse MoE layers with 256 experts, and utilizes a high-capacity expert routing mechanism. This design allows for top-k=16 routing and auxiliary-loss-free load balancing, enhancing its computational efficiency.
Read More
The model employs a global attention architecture across all layers, featuring 64 Q-heads and 8 KV-heads, with softplus attention output gating. This setup supports native reasoning capabilities, enabling interleaved thinking between tool calls, which can be enabled or disabled per request. Laguna M.1 demonstrates strong performance on several benchmarks, including SWE-bench Verified, SWE-bench Multilingual, SWE-Bench Pro, and Terminal-Bench 2.0, making it competitive with state-of-the-art models.
Laguna M.1 is licensed under the Apache 2.0 License, allowing for free use and modification for both commercial and non-commercial purposes. It is supported by various platforms, including vLLM, SGLang, Transformers, and TRT-LLM, thanks to collaborations with NVIDIA. The model is designed for software engineering and agentic coding use cases, with a focus on preserving reasoning in message history to optimize performance.
Users can deploy Laguna M.1 locally using vLLM or SGLang, with support for tool calling, streaming responses, and reasoning parsing. The model is also available in quantized formats, such as FP8 and NVFP4, to accommodate different deployment needs. For those interested in exploring its capabilities, Laguna M.1 can be accessed through platforms like vLLM and SGLang, with detailed deployment guidance available in their respective documentation.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud, Self-hosted
- PlatformsWeb, macOS, Linux
Laguna M.1 Highlights
225B total parameters
23B activated parameters per token
70-layer MoE transformer
256 experts with top-k=16 routing
Global attention architecture
Native reasoning support
Apache 2.0 license
Strong benchmark performance
Getting Started with Laguna M.1
Access model page: Visit the Hugging Face page for Laguna M.1
Authenticate: Obtain an API key for access
Configure: Set up the model with desired parameters
Send prompts: Use the model for text-to-text tasks
Fine-tune: Adjust the model for specific use cases
Laguna M.1's Use Cases
- Agentic Coding
- Long-Horizon Tasks
- Benchmark Testing
- Tool Integration
- Research and Development