ToolPotion
AI Advisor
Submit a Tool (Free)

Mage-VL

LLMs#20AI Models & LLMsOpen source · Web

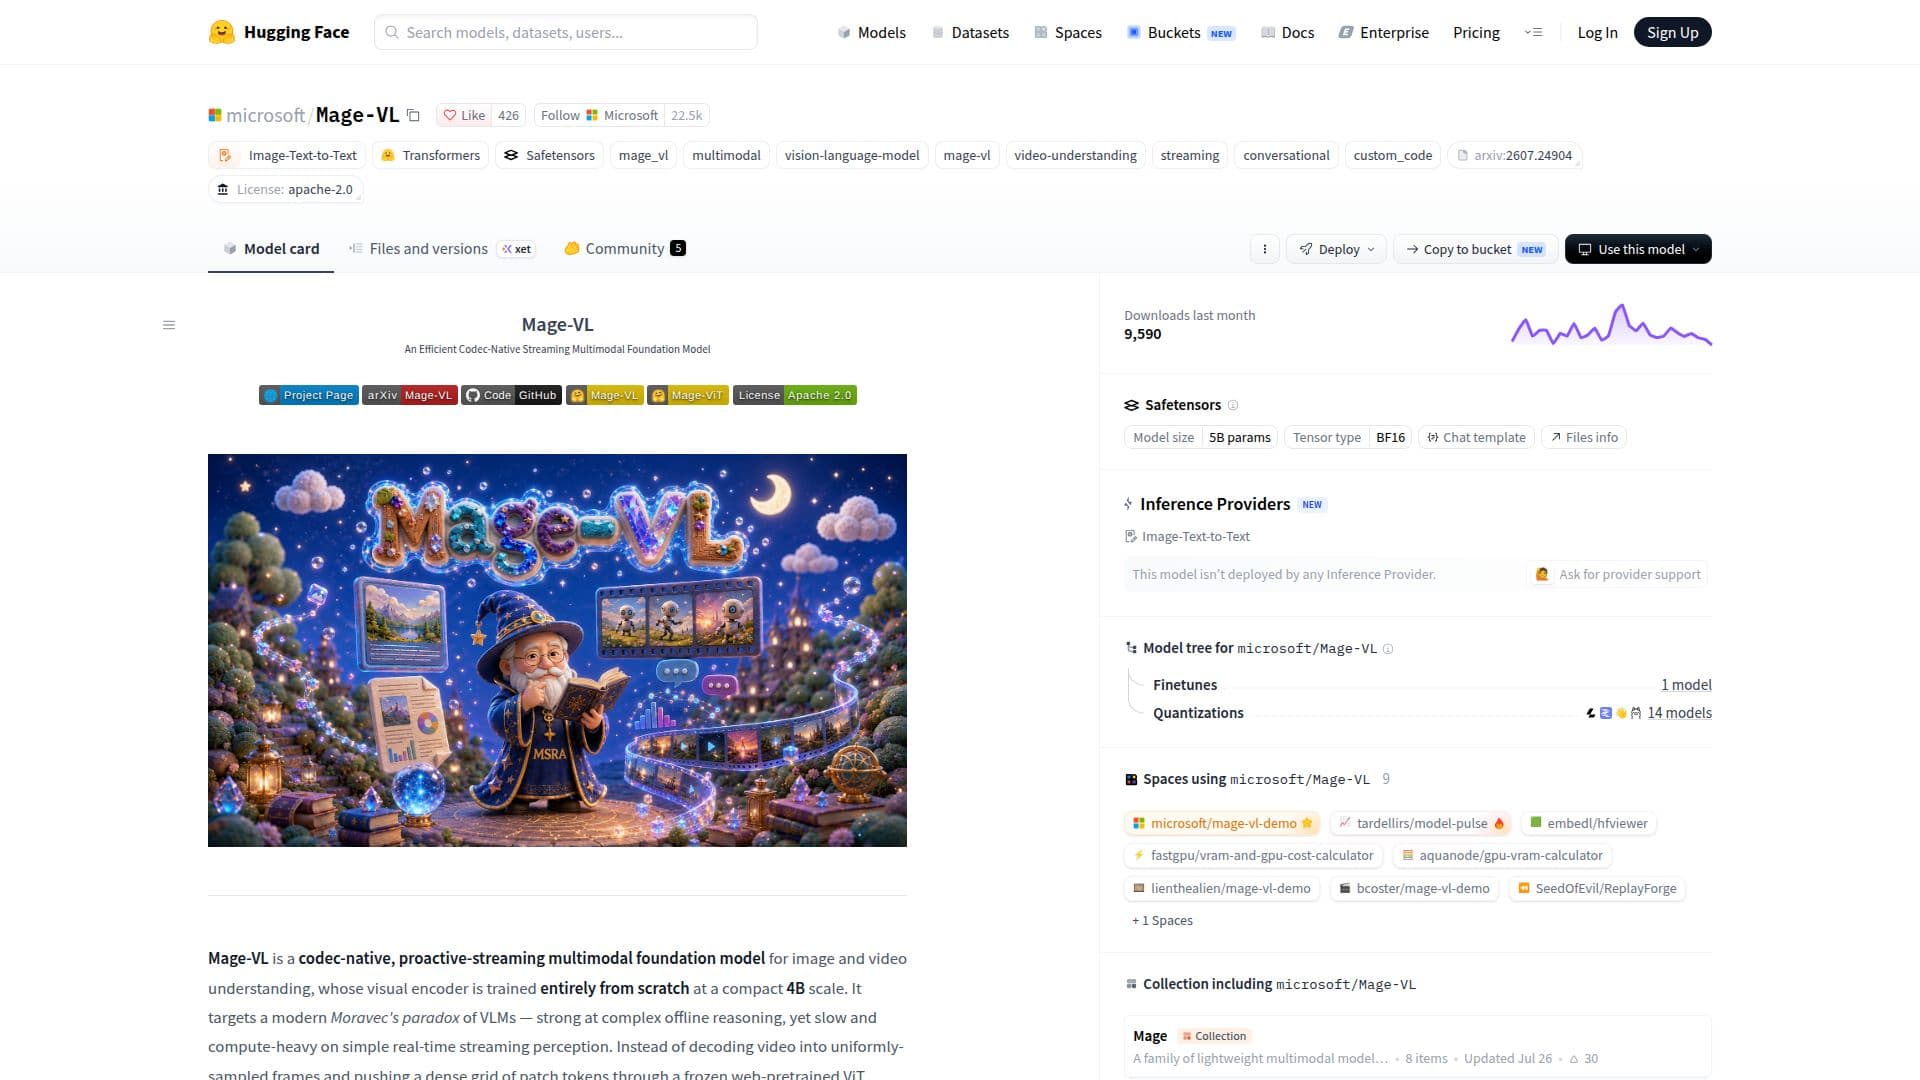
Mage-VL is a codec-native, proactive-streaming multimodal foundation model designed for efficient image and video understanding. It leverages a unique visual encoder and a causal decoder to enhance real-time streaming perception while reducing computational demands.

Visit Website
Share
Mage-VL screenshot
Mage-VL screenshot

Mage-VL is an innovative multimodal foundation model developed to address the challenges of image and video understanding. It is designed as a codec-native, proactive-streaming model that efficiently processes visual data. The model's visual encoder, Mage-ViT, is trained from scratch and operates on a compact 4B scale. This encoder is unique in its ability to allocate tokens based on codec-derived spatio-temporal importance, allowing it to process videos up to eight times longer under the same computational budget.

Read More

Mage-VL's architecture includes a Qwen3-4B causal decoder, which is the only pretrained component. This decoder works in tandem with Mage-ViT to handle variable-length token streams, supporting a unified interface for images and videos of varying lengths. The model's dual-process design incorporates a cognition gate that enables proactive streaming by monitoring content and activating the full visual language model only when necessary.

The model's codec-native approach significantly reduces visual token consumption by over 75%, resulting in a 3.5× speedup in wall-clock inference compared to traditional methods. This efficiency is achieved without compromising accuracy, making Mage-VL a powerful tool for real-time video analysis and understanding.

Mage-VL is particularly strong in video understanding and spatial intelligence, outperforming comparable models on several benchmarks. Its proactive streaming capabilities are demonstrated through its performance on SoccerNet streaming tasks, where it delivers low-latency, event-gated commentary.

Overall, Mage-VL represents a significant advancement in multimodal AI models, offering a data-efficient solution for complex visual tasks. Its open-source nature and comprehensive capabilities make it a valuable resource for developers and researchers in the field of artificial intelligence.

  • CategoryAI Models & LLMs
  • Pricing ModelOpen source
  • DeploymentCloud
  • PlatformsWeb

  • Codec-native visual encoder

  • Proactive streaming gate

  • Qwen3-4B causal decoder

  • 3.5× inference speedup

  • Data-efficient tokenizer

  • Variable-resolution pretraining

  • Unified model for images and videos

  • Event-gated commentary

  1. Access model page: Visit the Hugging Face repository

  2. Authenticate: Use your Hugging Face account credentials

  3. Configure: Set up the model parameters and environment

  4. Send prompts: Input your image or video data for processing

  5. Fine-tune: Adjust model settings for specific tasks

  • Real-time Video Analysis
  • Spatial Intelligence
  • Event-Gated Commentary
  • Image Understanding
  • Proactive Streaming

Popular AI Tools Like Mage-VL

Qwen3.5-4B is a causal language model with a vision encoder, designed for high-performance multimodal learning. It supports 201 languages and offers efficient hybrid architecture…

AI Models & LLMs
View Tool

Causal language model with a vision encoder, designed for high-performance multimodal learning. It supports 201 languages and offers efficient hybrid architecture…Qwen3.5-4B is a causal language model with a vision encoder, designed for high-performance multimodal learning. It supports 201 languages and offers efficient hybrid architecture…

AI Models & LLMs
See the Top 5 AI Models

DeepSeek-V4-Flash-Vision-Exp is an experimental multimodal model in the DeepSeek-V4 family, enhancing visual understanding capabilities. It builds on the DeepSeek-V4-Flash…

AI Models & LLMs
View Tool

Experimental multimodal model in the DeepSeek-V4 family, enhancing visual understanding capabilities. It builds on the DeepSeek-V4-Flash…DeepSeek-V4-Flash-Vision-Exp is an experimental multimodal model in the DeepSeek-V4 family, enhancing visual understanding capabilities. It builds on the DeepSeek-V4-Flash…

AI Models & LLMs
See the Top 50 LLMs

MiniMax M3 is an advanced AI model excelling in coding and agentic tasks. It features a 1M context window and native multimodal understanding, powered by the MSA architecture. The…

AI Models & LLMs

Ranked #48 in LLMs

View Tool

Advanced AI model excelling in coding and agentic tasks. It features a 1M context window and native multimodal understanding, powered by the MSA architecture. The…MiniMax M3 is an advanced AI model excelling in coding and agentic tasks. It features a 1M context window and native multimodal understanding, powered by the MSA architecture. The…

AI Models & LLMs
Ranked #48 in LLMs

Ideogram 4

AI Models

Ideogram 4 is a cutting-edge text-to-image model offering unparalleled control over image composition, style, and layout. It supports native 2k resolution and multilingual text…

AI Models & LLMs
View Tool

AI Models

Cutting-edge text-to-image model offering unparalleled control over image composition, style, and layout. It supports native 2k resolution and multilingual text…Ideogram 4 is a cutting-edge text-to-image model offering unparalleled control over image composition, style, and layout. It supports native 2k resolution and multilingual text…

AI Models & LLMs
See the Top 5 AI Models

SmolVLM2 is an advanced video understanding model designed to run efficiently on various devices. It offers enhanced video analysis and visual reasoning capabilities, making video…

AI Models & LLMs
View Tool

Advanced video understanding model designed to run efficiently on various devices. It offers enhanced video analysis and visual reasoning capabilities, making video…SmolVLM2 is an advanced video understanding model designed to run efficiently on various devices. It offers enhanced video analysis and visual reasoning capabilities, making video…

AI Models & LLMs
See the Top 5 AI Models

Pixtral-12B-2409 is a multimodal AI model with 12 billion parameters and a 400 million parameter vision encoder, designed for advanced image and text processing tasks.

AI Models & LLMs
View Tool

Multimodal AI model with 12 billion parameters and a 400 million parameter vision encoder, designed for advanced image and text processing tasks.Pixtral-12B-2409 is a multimodal AI model with 12 billion parameters and a 400 million parameter vision encoder, designed for advanced image and text processing tasks.

AI Models & LLMs
See the Top 5 AI Models

V-JEPA

AI GitHub Repos

V-JEPA is a PyTorch implementation for self-supervised learning from video. It utilizes a joint-embedding predictive architecture to learn visual representations without human…

AI Models & LLMs
View Tool

AI GitHub Repos

PyTorch implementation for self-supervised learning from video. It utilizes a joint-embedding predictive architecture to learn visual representations without human…V-JEPA is a PyTorch implementation for self-supervised learning from video. It utilizes a joint-embedding predictive architecture to learn visual representations without human…

AI Models & LLMs
See the Top 250 AI GitHub Repos

LTX-2

AI Models

LTX-2 is a DiT-based audio-video foundation model designed to generate synchronized video and audio. It combines modern video generation techniques with open weights, enabling…

AI Models & LLMs
View Tool

AI Models

DiT-based audio-video foundation model designed to generate synchronized video and audio. It combines modern video generation techniques with open weights, enabling…LTX-2 is a DiT-based audio-video foundation model designed to generate synchronized video and audio. It combines modern video generation techniques with open weights, enabling…

FeaturedAI Models & LLMs
See the Top 5 AI Models
1 of 8