ToolPotion
AI Advisor
Submit a Tool (Free)

ERNIE-5.5-Flash-Base

LLMsAI Models & LLMsOpen source · Web

ERNIE-5.5-Flash-Base is an efficient sparse Mixture-of-Experts (MoE) language model with 280B total parameters, designed for text generation. Pre-trained on 33.5T tokens, it supports fine-tuning and inference with a 1M-token context. This model serves as a robust starting point for domain adaptation, instruction tuning, and reinforcement learning research, offering strong performance across various benchmarks.

Visit Website
Share
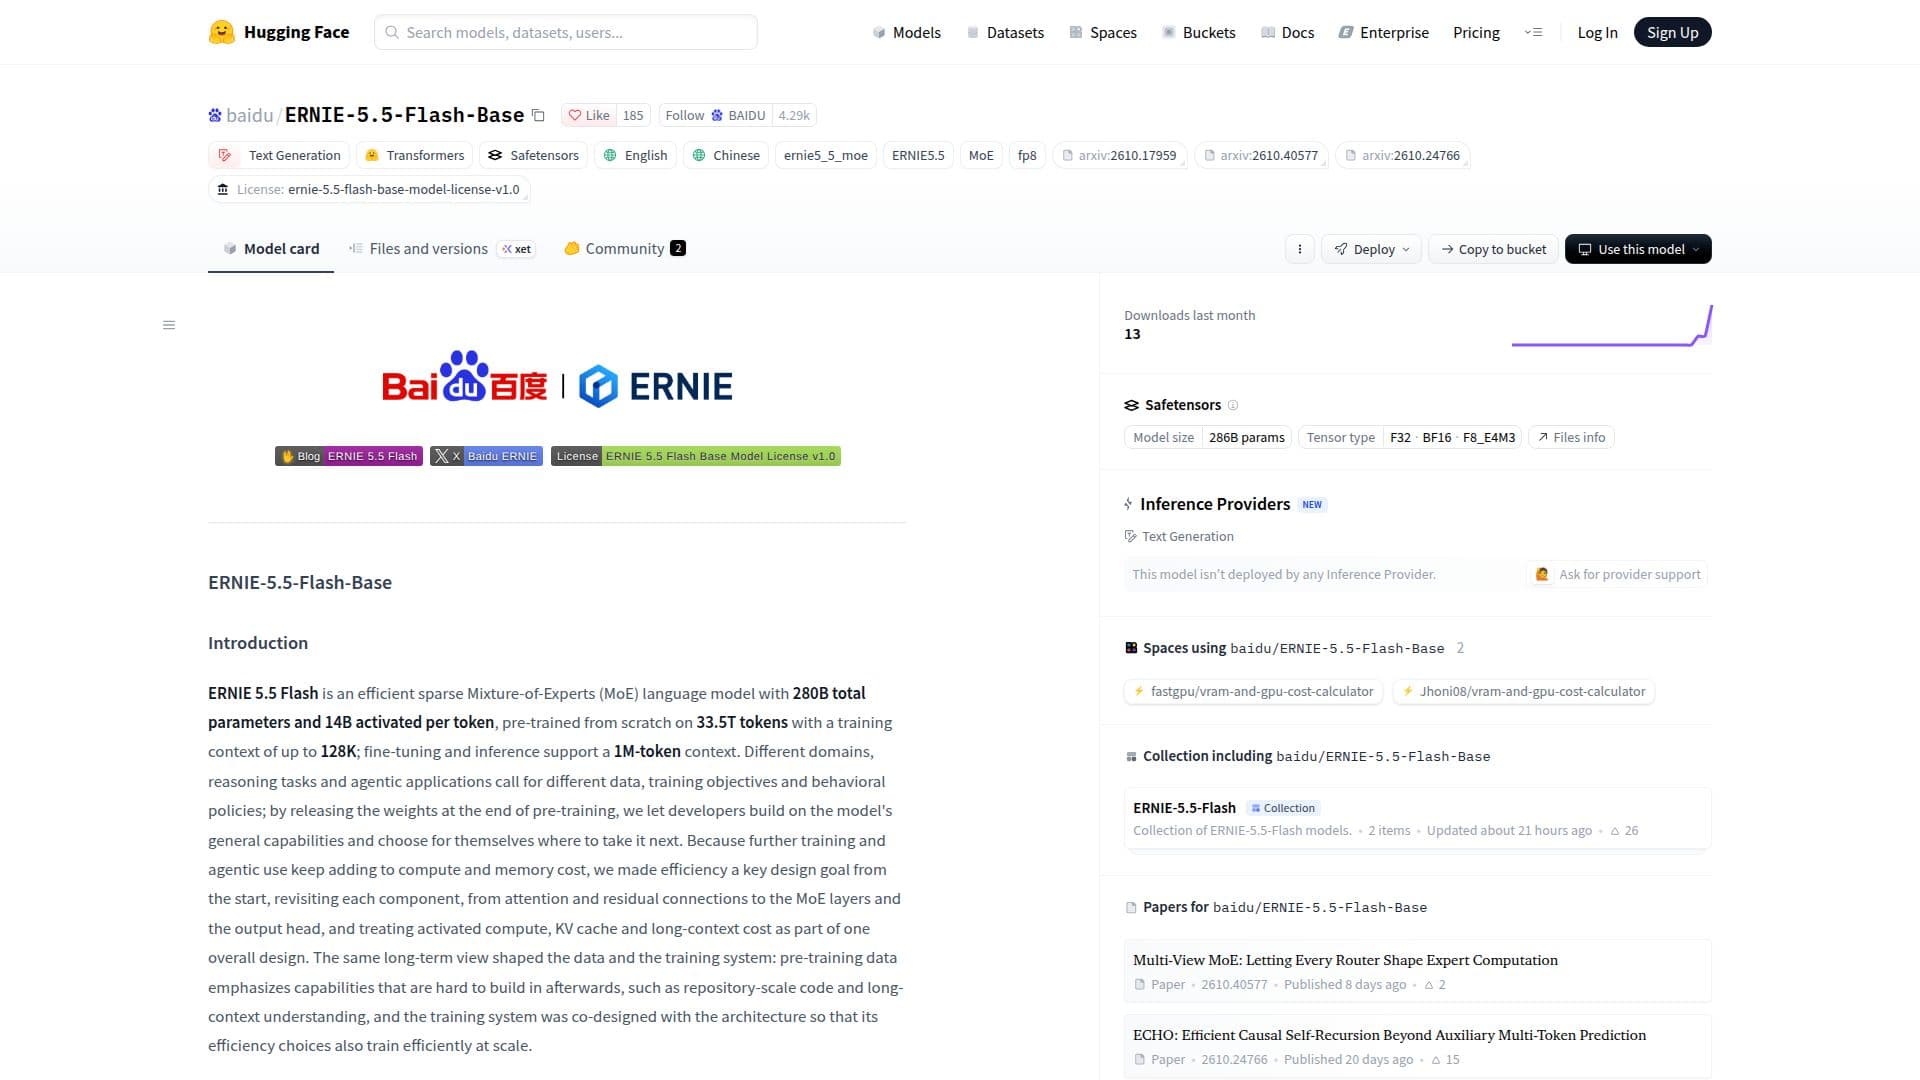
ERNIE-5.5-Flash-Base screenshot

ERNIE-5.5-Flash-Base is a sophisticated text generation model developed by Baidu, available on Hugging Face. It is an efficient sparse Mixture-of-Experts (MoE) language model, featuring 280 billion total parameters with 14 billion activated per token. The model was pre-trained from scratch on an extensive dataset of 33.5 trillion tokens, utilizing a training context of up to 128K. For fine-tuning and inference, it supports an impressive 1M-token context length.

Read More

Designed with efficiency as a core objective, ERNIE 5.5 Flash revisits every component, from attention mechanisms and residual connections to MoE layers and the output head. This holistic approach considers activated compute, KV cache, and long-context costs as part of an integrated design. The pre-training data emphasizes capabilities that are challenging to build post-training, such as repository-scale code understanding and long-context comprehension. The training system was co-designed with the architecture to ensure efficient scaling.

ERNIE-5.5-Flash-Base represents the checkpoint at the end of pre-training, making it an ideal foundation for developers. It allows for domain adaptation, instruction tuning, and reinforcement learning research. The model demonstrates strong results across a unified evaluation pipeline, covering knowledge, reasoning, mathematics, code, multilingual tasks, and long-context benchmarks. Its performance is benchmarked against other large models like DeepSeek-V4-Flash-Base, Hy3-preview-Base, and MiMo-V2.5-Base, all evaluated under consistent conditions.

The architecture incorporates a 280B-A14B hybrid-attention MoE with 43 layers, including 1 dense FFN and 42 Multi-Router Latent MoE layers. It features 37 Heavily Compressed Attention (HCA) layers and 6 Multi-head Latent Attention layers with sparse attention (MLA + DSA). The model utilizes 512 routed experts (top-10) plus 1 shared expert per MoE layer. Key innovations include Hybrid MLA + HCA attention with layer-specific head dimensions, Low-Rank Gated Attention, Virtual Head Attention (VHA), Multi-Router Latent MoE, ECHO for future token prediction, Manifold-constrained Hyper-Connections (mHC), and a MultiMax Output Head. The tokenizer uses a ≈200K-entry BPE tokenizer that tokenizes numbers right-to-left in groups of up to three digits.

Deployment of ERNIE-5.5-Flash-Base is supported with SGLang and vLLM, enabling production serving with context lengths up to 1,048,576 tokens for long-context inference. The model is provided under the ERNIE 5.5 Flash Base Model License Agreement v1.0, with copyright held by Baidu.

  • CategoryAI Models & LLMs
  • Pricing ModelOpen source
  • DeploymentCloud
  • PlatformsWeb

  • 280B total parameters with 14B activated per token

  • Pre-trained on 33.5T tokens

  • Supports 1M-token context for fine-tuning and inference

  • Efficient sparse Mixture-of-Experts (MoE) architecture

  • Hybrid MLA + HCA attention with layer-specific head dimensions

  • Low-Rank Gated Attention and Virtual Head Attention (VHA)

  • Multi-Router Latent MoE with 512 routed experts and 1 shared expert

  • ECHO for multi-horizon loss and speculative decoding

  • Manifold-constrained Hyper-Connections (mHC) for signal propagation

  • MultiMax Output Head for sharpened vocabulary distribution

  • ≈200K-entry BPE tokenizer with right-to-left number tokenization

  • Supports deployment with SGLang and vLLM

  • Strong performance across knowledge, reasoning, math, code, multilingual, and long-context benchmarks

  • FP8 and BF16 precision weights available

  1. Access Model: Navigate to the ERNIE-5.5-Flash-Base page on Hugging Face.

  2. Download Model: Choose between FP8 (safetensors) or BF16 (safetensors) precision for download.

  3. Install Deployment Tools: Install vLLM and the ERNIE 5.5 plugin, or use the official SGLang prebuilt Docker image.

  4. Launch Server: Start the vLLM or SGLang server to host the model.

  5. Send Requests: Use curl or other API clients to send requests to the completions endpoint for text generation.

  6. Fine-tune Model: Utilize the pre-trained checkpoint for domain adaptation, instruction tuning, or reinforcement learning research.

  • Text Generation
  • Domain Adaptation
  • Instruction Tuning
  • Reinforcement Learning Research
  • Code Generation and Understanding
  • Long-Context Understanding
  • Multilingual Applications
  • Reasoning Tasks

From Baidu

A model in Baidu Wenxin Assistant.

ERNIE-5.5-Flash-Base Reviews

Loading...

Popular AI Tools Like ERNIE-5.5-Flash-Base

DeepSeek-V4-Pro is an advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…

AI Models & LLMs
View Tool

Advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…DeepSeek-V4-Pro is an advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…

FeaturedAI Models & LLMs
See the Top 50 LLMs

DeepSeek-V3 is a Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…

AI Models & LLMs

Ranked #37 in LLMs

View Tool

Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…DeepSeek-V3 is a Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…

FeaturedAI Models & LLMs
Ranked #37 in LLMs

AliceAI-Foundation-80B-A3B-Base is a foundational language model with a hybrid architecture and MoE layers, featuring 80 billion parameters. It excels in factual knowledge tasks,…

AI Models & LLMs

Ranked #28 in LLMs

View Tool

Foundational language model with a hybrid architecture and MoE layers, featuring 80 billion parameters. It excels in factual knowledge tasks,…AliceAI-Foundation-80B-A3B-Base is a foundational language model with a hybrid architecture and MoE layers, featuring 80 billion parameters. It excels in factual knowledge tasks,…

AI Models & LLMs
Ranked #28 in LLMs

Ling-3.0-flash is a next-generation hybrid reasoning model designed for efficiency and performance. With 124 billion parameters, it excels in reasoning, instruction following, and…

AI Models & LLMs
View Tool

Next-generation hybrid reasoning model designed for efficiency and performance. With 124 billion parameters, it excels in reasoning, instruction following, and…Ling-3.0-flash is a next-generation hybrid reasoning model designed for efficiency and performance. With 124 billion parameters, it excels in reasoning, instruction following, and…

AI Models & LLMs
See the Top 50 LLMs

Kimi-K2-Instruct is a state-of-the-art mixture-of-experts language model designed for advanced AI tasks. It excels in reasoning, coding, and tool use, offering robust performance…

AI Models & LLMs

Ranked #46 in LLMs

View Tool

State-of-the-art mixture-of-experts language model designed for advanced AI tasks. It excels in reasoning, coding, and tool use, offering robust performance…Kimi-K2-Instruct is a state-of-the-art mixture-of-experts language model designed for advanced AI tasks. It excels in reasoning, coding, and tool use, offering robust performance…

AI Models & LLMs
Ranked #46 in LLMs

MiniMax-M3.1-Flash is a multimodal mixture-of-experts model designed for coding, agentic workflows, and cybersecurity. It supports text, image, and video inputs, offering improved…

AI Models & LLMs
View Tool

Multimodal mixture-of-experts model designed for coding, agentic workflows, and cybersecurity. It supports text, image, and video inputs, offering improved…MiniMax-M3.1-Flash is a multimodal mixture-of-experts model designed for coding, agentic workflows, and cybersecurity. It supports text, image, and video inputs, offering improved…

AI Models & LLMs
See the Top 50 LLMs

DeepSeek-V4-Pro-DSpark is an advanced language model featuring a hybrid attention architecture and manifold-constrained hyper-connections. It supports a context length of one…

AI Models & LLMs
View Tool

Advanced language model featuring a hybrid attention architecture and manifold-constrained hyper-connections. It supports a context length of one…DeepSeek-V4-Pro-DSpark is an advanced language model featuring a hybrid attention architecture and manifold-constrained hyper-connections. It supports a context length of one…

AI Models & LLMs
See the Top 50 LLMs

Solar Open 2 is a large language model by Upstage, designed for agentic use cases like office productivity and coding. It features a Hybrid-Attention Mixture-of-Experts…

AI Models & LLMs

Ranked #19 in LLMs

View Tool

Large language model by Upstage, designed for agentic use cases like office productivity and coding. It features a Hybrid-Attention Mixture-of-Experts…Solar Open 2 is a large language model by Upstage, designed for agentic use cases like office productivity and coding. It features a Hybrid-Attention Mixture-of-Experts…

AI Models & LLMs
Ranked #19 in LLMs
1 of 8