

Description
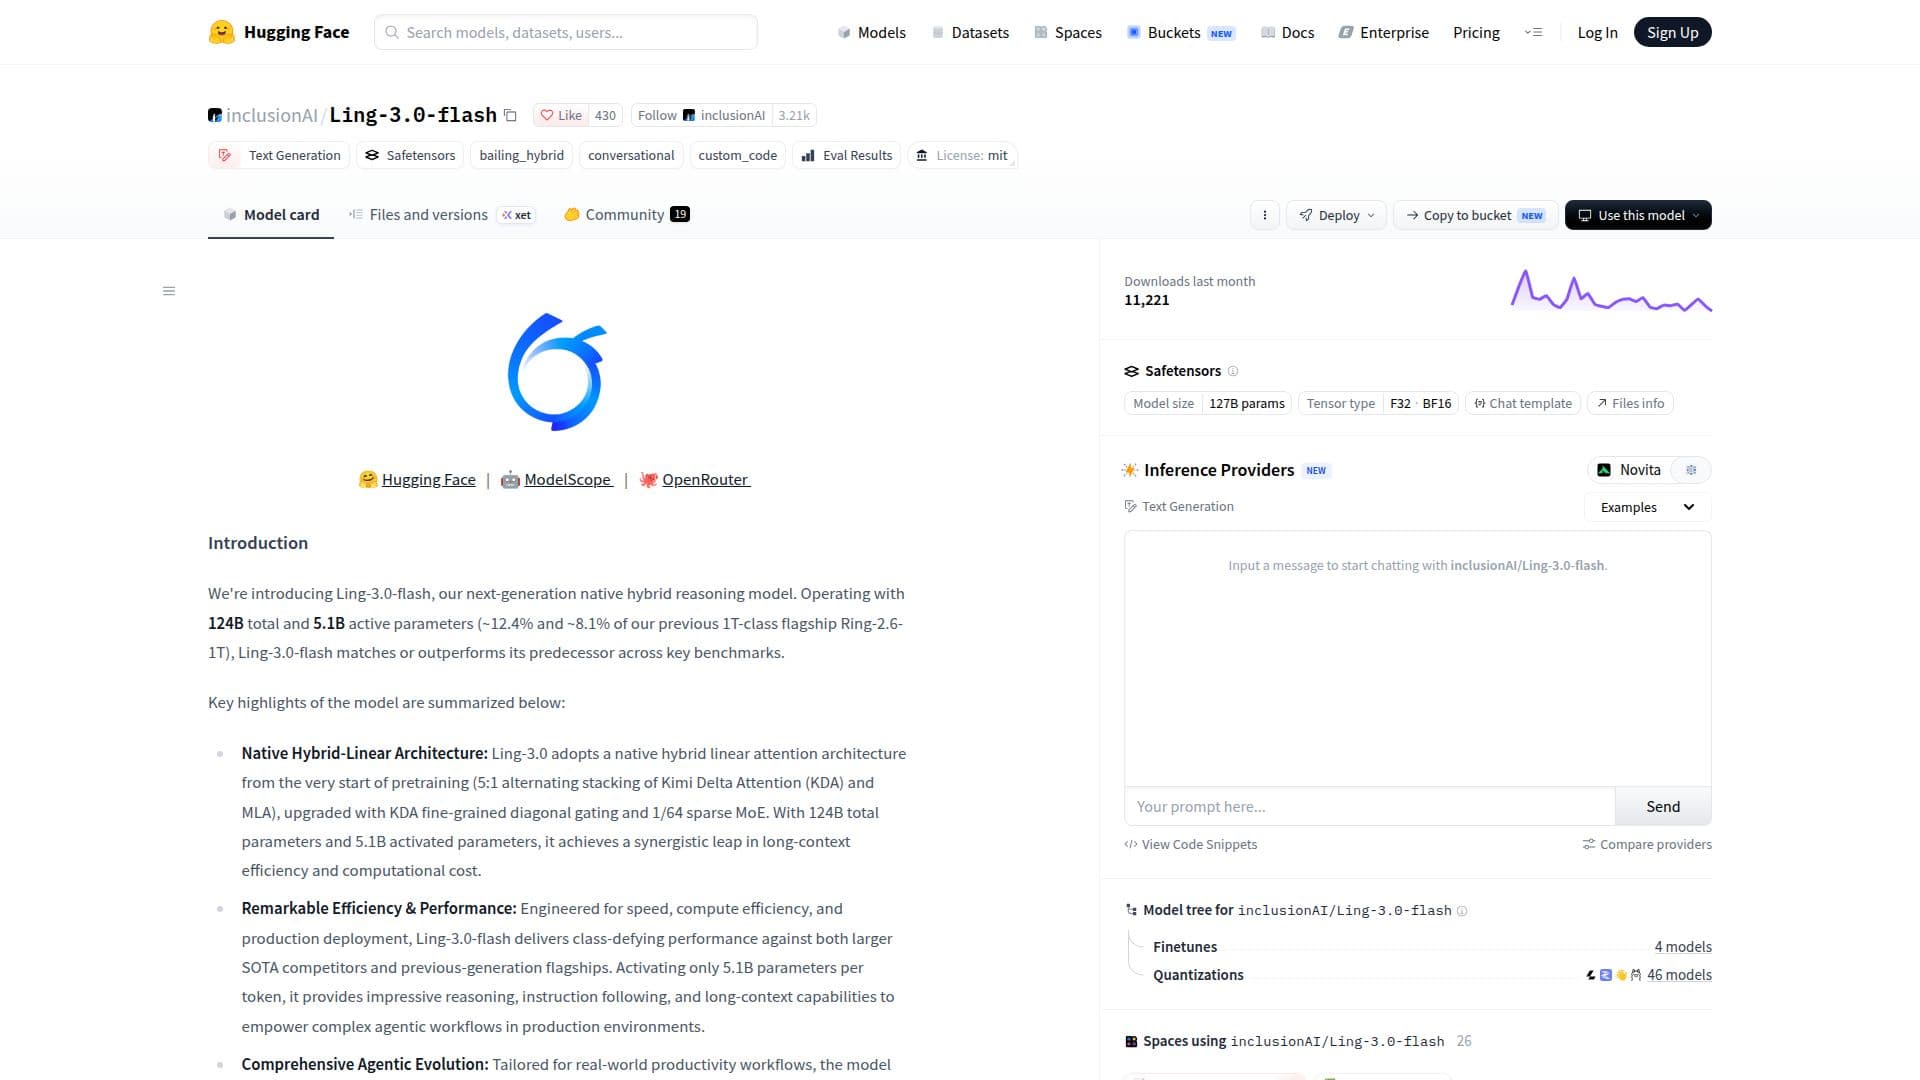
Ling-3.0-flash is a cutting-edge hybrid reasoning model developed by inclusionAI and hosted on Hugging Face. It operates with a total of 124 billion parameters, with 5.1 billion activated per token, providing remarkable efficiency and performance. The model adopts a native hybrid linear attention architecture, featuring Kimi Delta Attention (KDA) and MLA, upgraded with fine-grained diagonal gating and sparse MoE. This architecture allows Ling-3.0-flash to achieve a synergistic leap in long-context efficiency and computational cost.
Read More
Engineered for speed and compute efficiency, Ling-3.0-flash delivers class-defying performance against larger state-of-the-art competitors and previous-generation flagships. It empowers complex agentic workflows in production environments, activating only 5.1 billion parameters per token. The model incorporates 10,000+ interactive training environments to achieve end-to-end closed-loop execution across coding, general, and deep research agent tasks.
Ling-3.0-flash integrates the SGLang HiCache + Mooncake hierarchical caching architecture, featuring physical dual-pools and a cluster-shared L3 cache. This setup eliminates redundant recomputation during long-horizon interactions, reducing Time to First Token (TTFT) by 60% to over 80% in long-input scenarios. The model performs strongly across multiple authoritative benchmarks, including SWE-Bench Pro, SWE-Bench Multilingual, Tau3-banking-AA, MCP-Atlas, and SkillsBench.
The model is tailored for real-world productivity workflows, delivering strong performance in general knowledge, mathematical reasoning, instruction following, and long-context understanding. Ling-3.0-flash is designed for production deployment, offering impressive reasoning capabilities and long-context efficiency, making it suitable for complex agentic workflows.
- CategoryAI Models & LLMs
- Pricing ModelFreemium
- DeploymentCloud
- PlatformsWeb
Ling-3.0-flash Highlights
Native Hybrid-Linear Architecture
Remarkable Efficiency & Performance
Comprehensive Agentic Evolution
SGLang HiCache + Mooncake Caching
End-to-End Closed-Loop Execution
Long-Context Efficiency
Instruction Following
Mathematical Reasoning
Getting Started with Ling-3.0-flash
Access model page: Visit Hugging Face
Authenticate: Log in to your account
Configure: Set parameters and preferences
Send prompts: Input your queries
Fine-tune: Adjust model settings
Ling-3.0-flash's Use Cases
- Coding Tasks
- Research Agents
- Instruction Following
- Long-Context Understanding
- Mathematical Reasoning







