ToolPotion
AI Advisor
Submit a Tool (Free)

DeepSeek-V4-Pro-DSpark

DeepSeek-V4-Pro-DSpark is an advanced language model featuring a hybrid attention architecture and manifold-constrained hyper-connections. It supports a context length of one million tokens and is optimized for efficient long-context processing.

Visit Website
Share
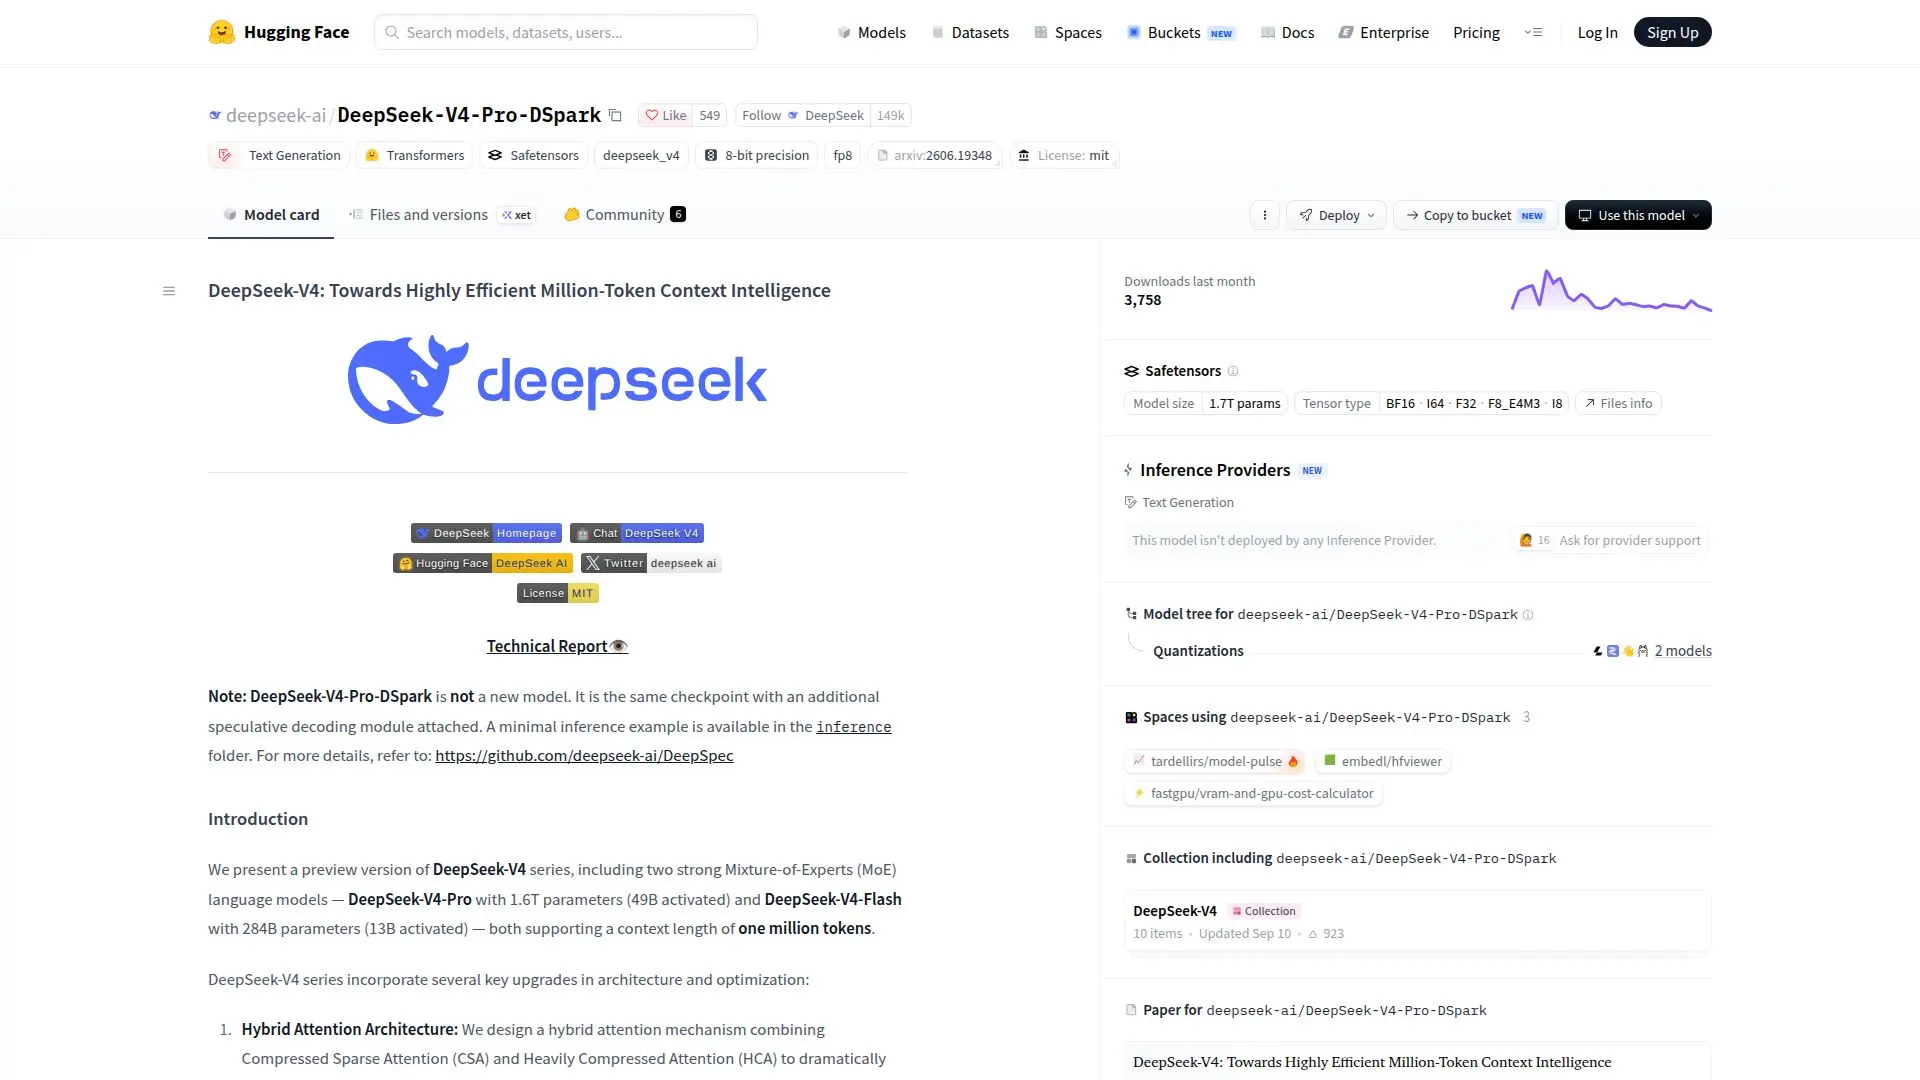
DeepSeek-V4-Pro-DSpark screenshot

DeepSeek-V4-Pro-DSpark is part of the DeepSeek-V4 series, which includes highly efficient Mixture-of-Experts (MoE) language models. This model is designed to handle extensive context lengths of up to one million tokens, making it suitable for complex language tasks. The hybrid attention architecture combines Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA) to enhance long-context efficiency. Additionally, the model incorporates manifold-constrained hyper-connections (mHC) to improve signal propagation stability across layers.

Read More

The DeepSeek-V4-Pro-DSpark model is pre-trained on over 32 trillion diverse and high-quality tokens, followed by a comprehensive post-training pipeline. This pipeline includes independent cultivation of domain-specific experts through supervised fine-tuning (SFT) and reinforcement learning with guided policy optimization (GRPO), followed by unified model consolidation via on-policy distillation.

DeepSeek-V4-Pro-DSpark excels in various benchmarks, achieving top-tier performance in coding and reasoning tasks. It significantly bridges the gap with leading closed-source models on reasoning and agentic tasks. The model supports three reasoning effort modes: Non-think, Think High, and Think Max, catering to different use cases from routine tasks to complex problem-solving.

The model is available for download on platforms like Hugging Face and ModelScope, and it is licensed under the MIT License. Users can run the model locally with detailed instructions provided in the inference folder, which includes model weight conversion and interactive chat demos.

  • CategoryAI Models & LLMs
  • Pricing ModelFree
  • DeploymentCloud, Self-hosted
  • PlatformsWeb

  • Hybrid Attention Architecture

  • Manifold-Constrained Hyper-Connections

  • Muon Optimizer

  • Million-Token Context Length

  • Mixture-of-Experts Model

  • Open Source

  • Three Reasoning Effort Modes

  • Comprehensive Post-Training Pipeline

  1. Access model page: Visit the Hugging Face model page

  2. Authenticate: Log in to your Hugging Face account

  3. Configure: Set up the model with desired parameters

  4. Send prompts: Input your text prompts for processing

  5. Fine-tune: Adjust model settings for specific tasks

  • Long-Context Processing
  • Complex Problem Solving
  • Routine Tasks
  • Coding Benchmarks
  • Reasoning Tasks

DeepSeek-V4-Pro-DSpark Reviews

Loading...

Popular AI Tools Like DeepSeek-V4-Pro-DSpark

DeepSeek-V4-Pro is an advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…

AI Models & LLMs
View Tool

Advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…DeepSeek-V4-Pro is an advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…

FeaturedAI Models & LLMs
See the Top 50 LLMs

DeepSeek-V3 is a Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…

AI Models & LLMs

Ranked #30 in LLMs

View Tool

Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…DeepSeek-V3 is a Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…

FeaturedAI Models & LLMs
Ranked #30 in LLMs

MiMo-V2.5-Pro

AI Models

MiMo-V2.5-Pro is an advanced open-source Mixture-of-Experts language model designed for complex tasks. It features a hybrid attention architecture and supports up to 1M tokens…

AI Models & LLMs
View Tool

AI Models

Advanced open-source Mixture-of-Experts language model designed for complex tasks. It features a hybrid attention architecture and supports up to 1M tokens…MiMo-V2.5-Pro is an advanced open-source Mixture-of-Experts language model designed for complex tasks. It features a hybrid attention architecture and supports up to 1M tokens…

AI Models & LLMs
See the Top 5 AI Models

Hy4 Preview is a new-generation Mixture-of-Experts model developed by the Tencent Hy Team. It features 770 billion parameters and is designed for productivity across various…

AI Models & LLMs

Ranked #34 in LLMs

View Tool

New-generation Mixture-of-Experts model developed by the Tencent Hy Team. It features 770 billion parameters and is designed for productivity across various…Hy4 Preview is a new-generation Mixture-of-Experts model developed by the Tencent Hy Team. It features 770 billion parameters and is designed for productivity across various…

AI Models & LLMs
Ranked #34 in LLMs

Solar Open 2 is a large language model by Upstage, designed for agentic use cases like office productivity and coding. It features a Hybrid-Attention Mixture-of-Experts…

AI Models & LLMs

Ranked #18 in LLMs

View Tool

Large language model by Upstage, designed for agentic use cases like office productivity and coding. It features a Hybrid-Attention Mixture-of-Experts…Solar Open 2 is a large language model by Upstage, designed for agentic use cases like office productivity and coding. It features a Hybrid-Attention Mixture-of-Experts…

AI Models & LLMs
Ranked #18 in LLMs

Laguna M.1 is a 225B parameter Mixture-of-Experts model designed for agentic coding and long-horizon tasks. It features high-capacity expert routing and global attention…

AI Models & LLMs

Ranked #35 in LLMs

View Tool

225B parameter Mixture-of-Experts model designed for agentic coding and long-horizon tasks. It features high-capacity expert routing and global attention…Laguna M.1 is a 225B parameter Mixture-of-Experts model designed for agentic coding and long-horizon tasks. It features high-capacity expert routing and global attention…

AI Models & LLMs
Ranked #35 in LLMs

MiniMax M3 is an advanced AI model excelling in coding and agentic tasks. It features a 1M context window and native multimodal understanding, powered by the MSA architecture. The…

AI Models & LLMs

Ranked #48 in LLMs

View Tool

Advanced AI model excelling in coding and agentic tasks. It features a 1M context window and native multimodal understanding, powered by the MSA architecture. The…MiniMax M3 is an advanced AI model excelling in coding and agentic tasks. It features a 1M context window and native multimodal understanding, powered by the MSA architecture. The…

AI Models & LLMs
Ranked #48 in LLMs

Ling-3.0-tiny is a lightweight hybrid reasoning model with 7.9B parameters, designed for efficient local deployment. It supports fast responses and multi-step reasoning, making it…

AI Models & LLMs
View Tool

Lightweight hybrid reasoning model with 7.9B parameters, designed for efficient local deployment. It supports fast responses and multi-step reasoning, making it…Ling-3.0-tiny is a lightweight hybrid reasoning model with 7.9B parameters, designed for efficient local deployment. It supports fast responses and multi-step reasoning, making it…

AI Models & LLMs
See the Top 50 LLMs
1 of 8