Description
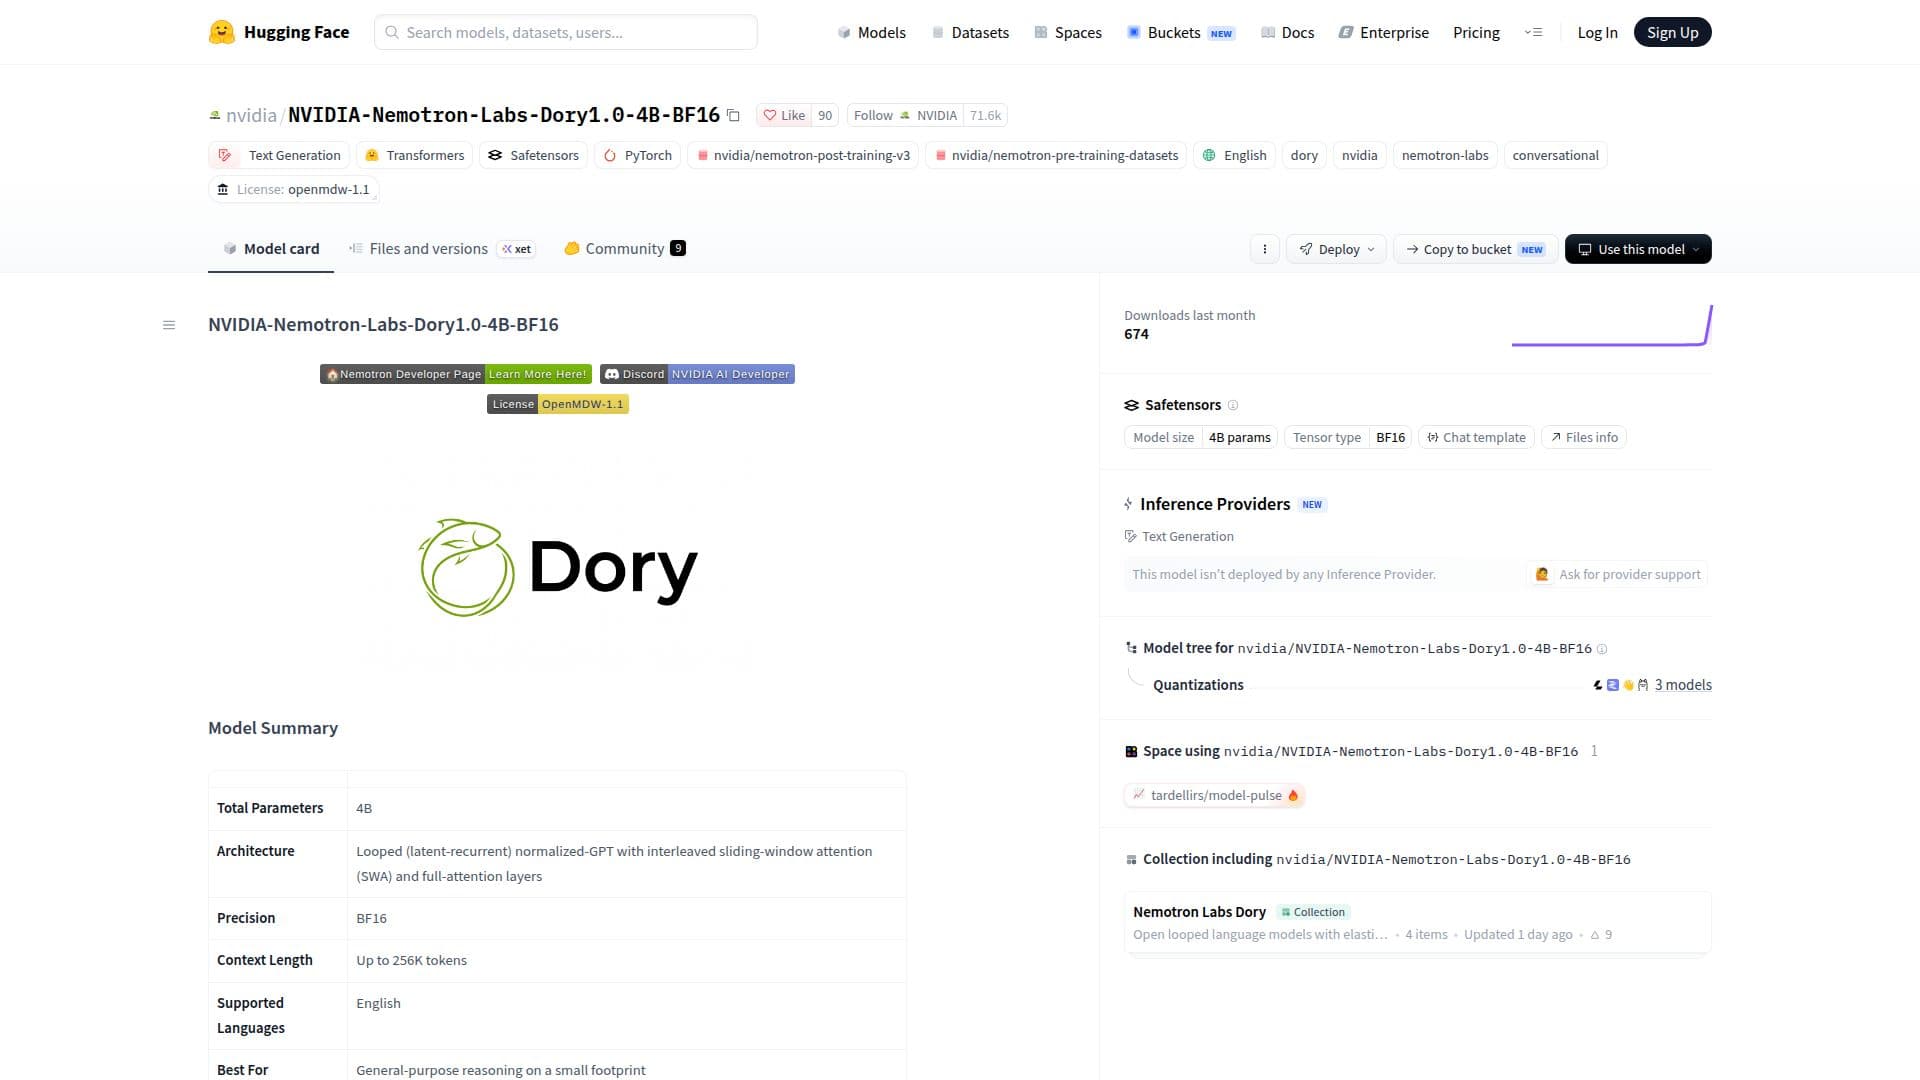
NVIDIA-Nemotron-Labs-Dory1.0-4B-BF16 is a large language model developed by NVIDIA, utilizing a looped (latent-recurrent) normalized-GPT architecture. This model is designed to handle general-purpose reasoning tasks while maintaining a small computational footprint. It features interleaved sliding-window attention (SWA) and full-attention layers, allowing it to efficiently process up to 256K tokens in context length.
Read More
The model is built with 4 billion parameters and employs BF16 precision, making it suitable for both commercial and non-commercial applications. It supports English language processing and is best suited for tasks requiring general reasoning capabilities. The model's architecture allows for elastic inference compute, enabling users to adjust the number of loops to balance between computational efficiency and accuracy without the need for retraining.
Dory1.0-4B-BF16 is pre-trained using NVIDIA's NVFP4 format before continuing in BF16, ensuring high performance on NVIDIA GPU-accelerated systems. It is available in multiple formats, including BF16, MXFP8, NVFP4, and Q5_K_M, providing flexibility in deployment across different hardware configurations.
The model's training involved 6 trillion tokens, with a focus on diverse domains such as math, science, and general knowledge. It underwent supervised fine-tuning and reinforcement learning to enhance its performance in multi-step tool use, instruction following, and structured output environments. The model's benchmarks demonstrate competitive performance across various tasks, including coding, reasoning, and instruction following.
NVIDIA-Nemotron-Labs-Dory1.0-4B-BF16 is governed by the OpenMDW License Agreement, version 1.1, and was released on October 16, 2026. It is designed to run optimally on NVIDIA's Hopper and Blackwell architectures, with support for Linux operating systems.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsLinux
NVIDIA-Nemotron-Labs-Dory1.0-4B-BF16 Highlights
Looped latent-recurrent architecture
Interleaved sliding-window attention
256K token context length
BF16 precision
Elastic inference compute
Native NVFP4 pre-training
Memory-efficient looping
OpenMDW License Agreement
Getting Started with NVIDIA-Nemotron-Labs-Dory1.0-4B-BF16
Access model page: Visit the Hugging Face model page for NVIDIA-Nemotron-Labs-Dory1.0-4B-BF16.
Authenticate: Ensure you have the necessary credentials to access the model.
Configure: Set up the model parameters, including loop count and KV cache settings.
Send prompts: Input text sequences to the model for processing.
Fine-tune: Adjust model settings for specific tasks if needed.
NVIDIA-Nemotron-Labs-Dory1.0-4B-BF16's Use Cases
- General Reasoning
- Coding Tasks
- Instruction Following
- Long Context Processing
- Scientific Research