Description
NVIDIA Nemotron 3.5 Bolt 74B is a sophisticated large language model that integrates a Mamba-2–Transformer hybrid architecture with a C-RADIO v4-H vision encoder. It boasts a total of 74 billion parameters, with 9 billion active, and operates with BF16 precision for full-precision weights. The model can handle context lengths of up to 256K tokens, supporting text, image, and video inputs, and producing text outputs. It is deployed on NVIDIA's Ampere, Hopper, or Blackwell hardware, utilizing vLLM for efficient operations.
Read More
The model is optimized for speculative decoding through the LiLiCorr drafter via DFlash, generating seven speculative tokens in the provided vLLM recipes. It features a reasoning mode with chat-template controls, inherited from the Super 3.5 VL client, and is best suited for customization, post-training, and creating quantized variants for local agentic tasks. The recommended sampling settings for text are a temperature of 1.0 and a top_p of 0.95.
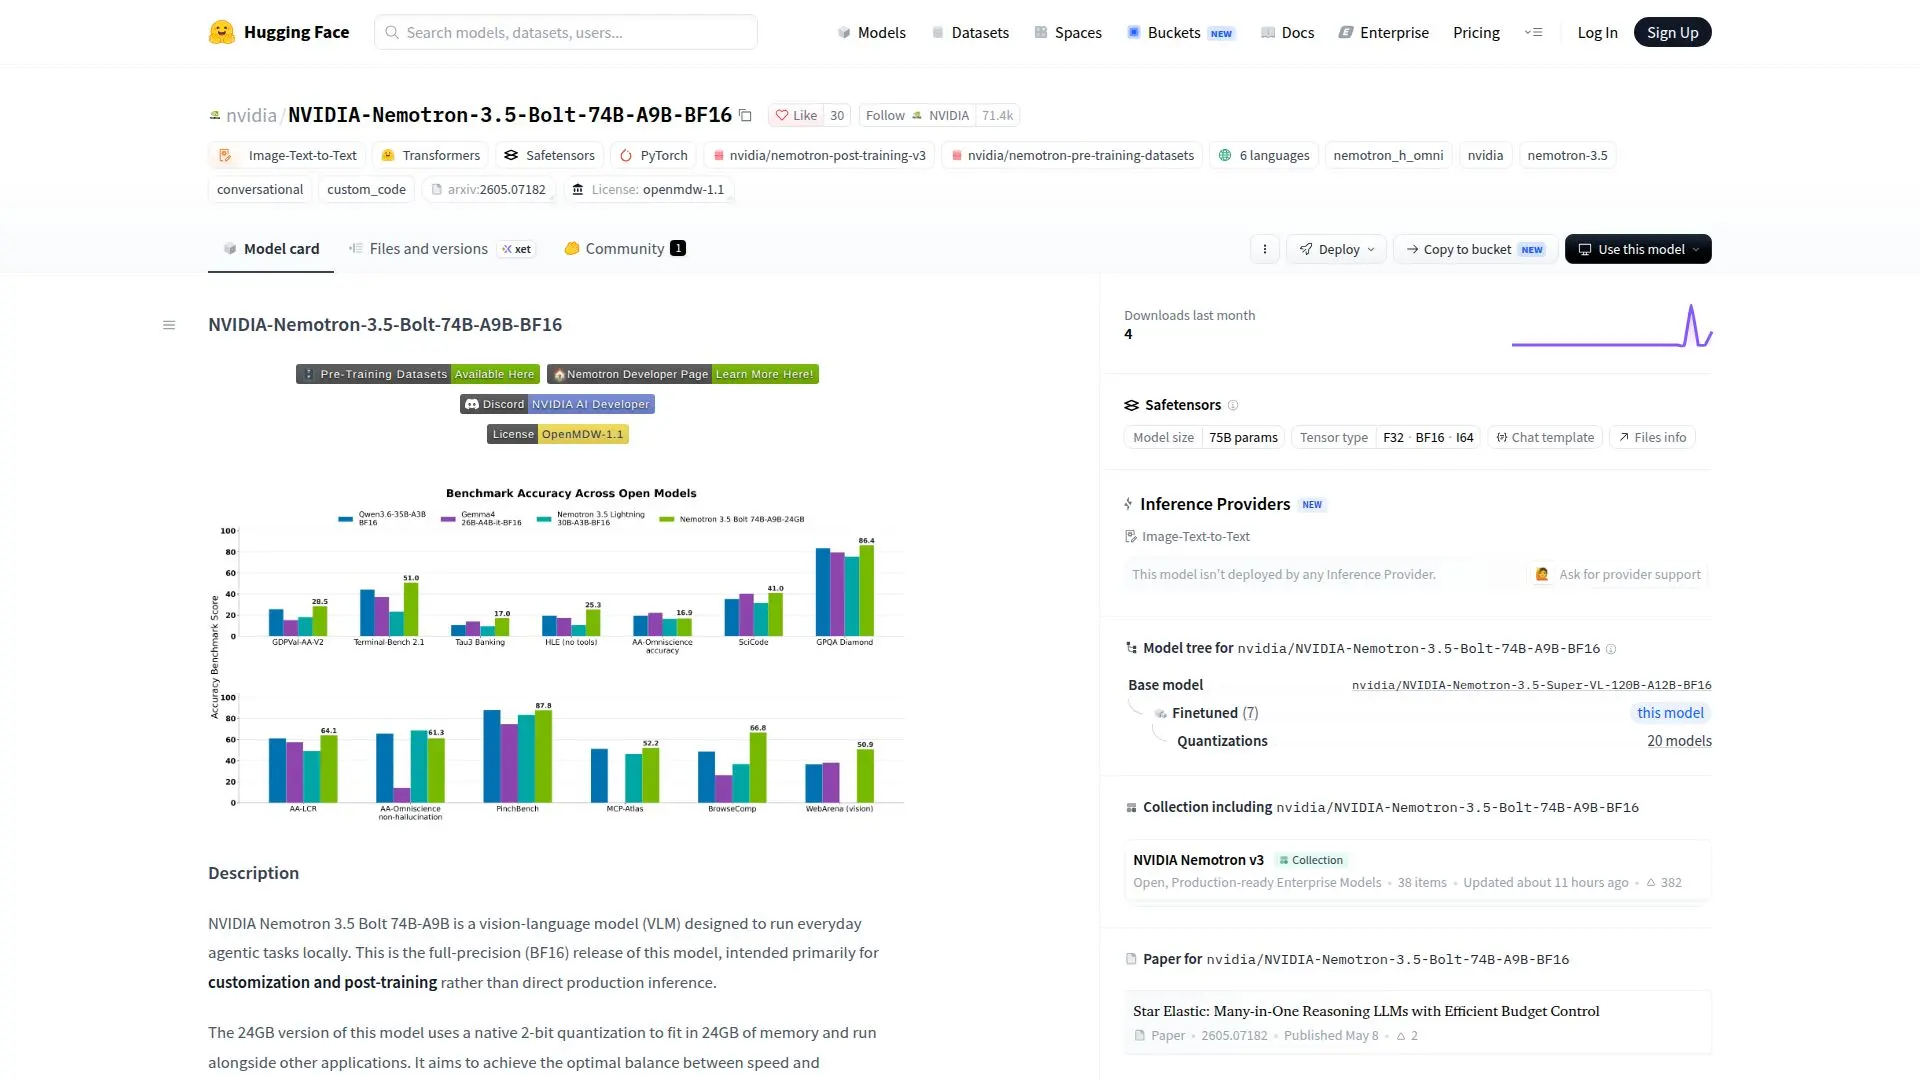
NVIDIA Nemotron 3.5 Bolt 74B is licensed under OpenMDW-1.1, ensuring open access for further development and integration. The model has been benchmarked across various tests, including GDPVal-AA-V2, Terminal-Bench 2.1, and others, demonstrating competitive performance metrics. It is particularly effective in tasks requiring multi-turn tool interactions and has shown improvements in MCP use capabilities.
The training methodology involves multiple agentic environments with full E2E GRPO targeting MCP and SWE tasks. The model's foundation is built on the Nemotron 3 corpus, which includes datasets like Nemotron-CC-v2 and Nemotron-Pretraining-Code-v1, among others. NVIDIA has ensured that no user-sourced data was used in training, maintaining privacy and data integrity.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentNVIDIA Ampere, Hopper, Blackwell
- PlatformsWeb
NVIDIA Nemotron 3.5 Bolt 74B Highlights
Mamba-2–Transformer hybrid architecture
C-RADIO v4-H vision encoder
74 billion parameters
BF16 precision
Context length up to 256K tokens
Speculative decoding with LiLiCorr drafter
Reasoning mode with chat-template controls
OpenMDW-1.1 license
Getting Started with NVIDIA Nemotron 3.5 Bolt 74B
Access model page: Visit the Hugging Face model page for NVIDIA Nemotron 3.5 Bolt 74B.
Authenticate: Ensure you have the necessary credentials to access the model.
Configure: Set up the model parameters and environment according to your needs.
Send prompts: Input text, image, or video data to the model for processing.
Fine-tune: Customize the model for specific tasks or applications.
NVIDIA Nemotron 3.5 Bolt 74B's Use Cases
- Customization
- Post-training
- Quantized Variants
- Multi-turn Interactions
- Text Processing