Description
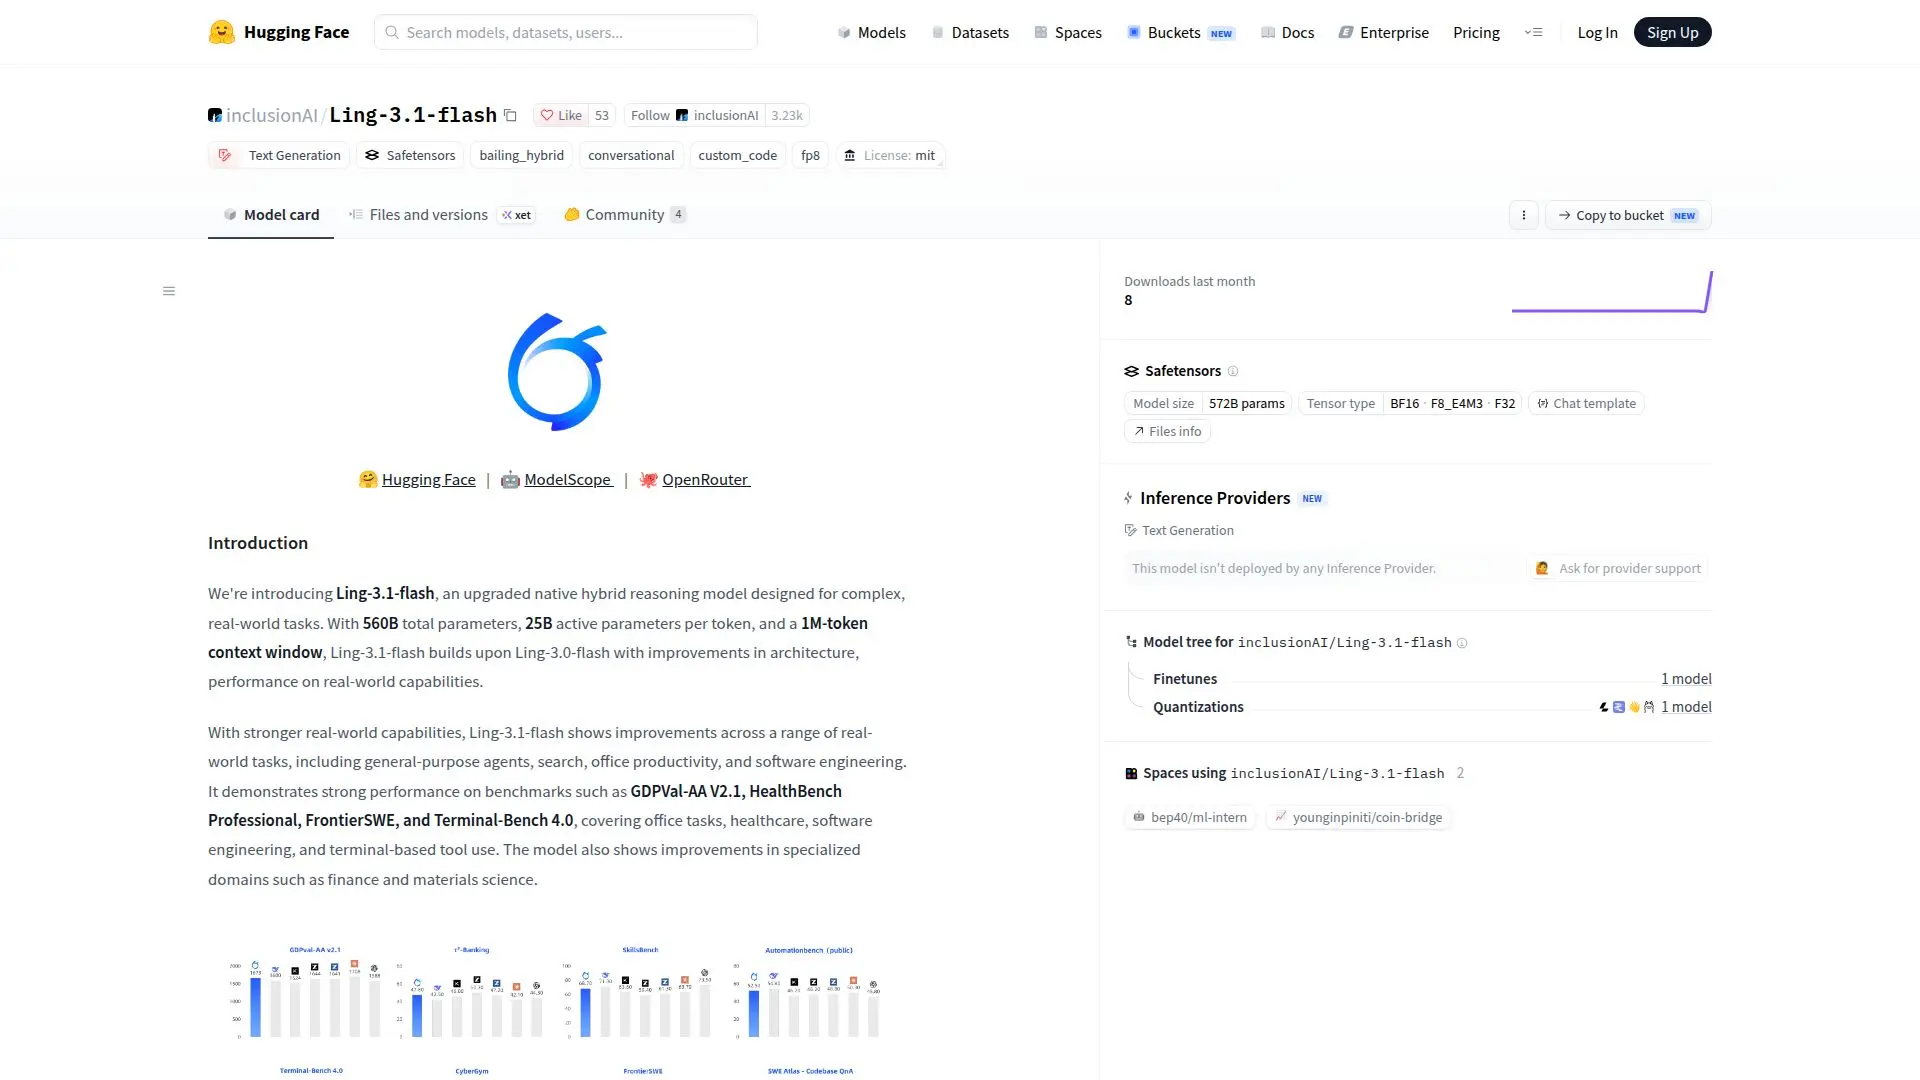
Ling-3.1-flash is an upgraded native hybrid reasoning model introduced by inclusionAI on the Hugging Face platform. Designed to tackle complex, real-world tasks, this model boasts a total of 560 billion parameters, with 25 billion active parameters per token and a 1 million-token context window. These enhancements build upon its predecessor, Ling-3.0-flash, offering improved architecture and performance.
Read More
The model excels in a variety of real-world applications, such as general-purpose agents, search, office productivity, and software engineering. It has demonstrated strong performance on benchmarks like GDPVal-AA V2.1, HealthBench Professional, FrontierSWE, and Terminal-Bench 4.0. These benchmarks cover a wide range of tasks, including office tasks, healthcare, software engineering, and terminal-based tool use. Additionally, Ling-3.1-flash shows notable improvements in specialized domains such as finance and materials science.
The architecture of Ling-3.1-flash is based on a hybrid-linear mixture of experts (MoE) model, featuring 63 KDA and 9 Gated MLA transformer layers, 4 dense layers, and 512 routed experts. The model also includes 64 attention heads and a hidden size of 4096, with a vocabulary size of 157,184.
Ling-3.1-flash has been evaluated across multiple authoritative benchmarks, showcasing its strong performance in coding and agentic tasks. It supports frameworks like Claude Code, Kilo Code, Qwen Code, Hermes Agent, and OpenClaw. The model also introduces LingCode, a harness built on the open-source coding agent Pi, which enhances performance on complex, long-horizon coding tasks.
For users looking to get started, the recommended SGLang image includes Ling-3.1-flash support, MTP speculative decoding, and Hopper decode optimizations. The model is available for inference on various server configurations, and verified recipes are provided for different hardware setups.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsWeb
Ling-3.1-flash Highlights
560B total parameters
1M-token context window
Hybrid-linear MoE architecture
63 KDA + 9 Gated MLA layers
512 routed experts
64 attention heads
Supports multiple frameworks
Strong benchmark performance
Getting Started with Ling-3.1-flash
Access model page: Visit Hugging Face
Authenticate: Log in to your account
Configure: Set up server or client environment
Send prompts: Use verified recipes for inference
Ling-3.1-flash's Use Cases
- General-purpose agents
- Office productivity
- Software engineering
- Healthcare applications
- Financial analysis