ToolPotion
AI Advisor
Submit a Tool (Free)

ERNIE-5.5-Flash-Base-BF16

ERNIE-5.5-Flash-Base-BF16 is an efficient sparse Mixture-of-Experts (MoE) language model with 280 billion total parameters. Pre-trained on 33.5 trillion tokens, it supports fine-tuning and inference with a 1 million-token context. This model is designed for various applications, including domain adaptation, instruction tuning, and reinforcement learning research, offering strong performance across multiple benchmarks.

Visit Website
Share
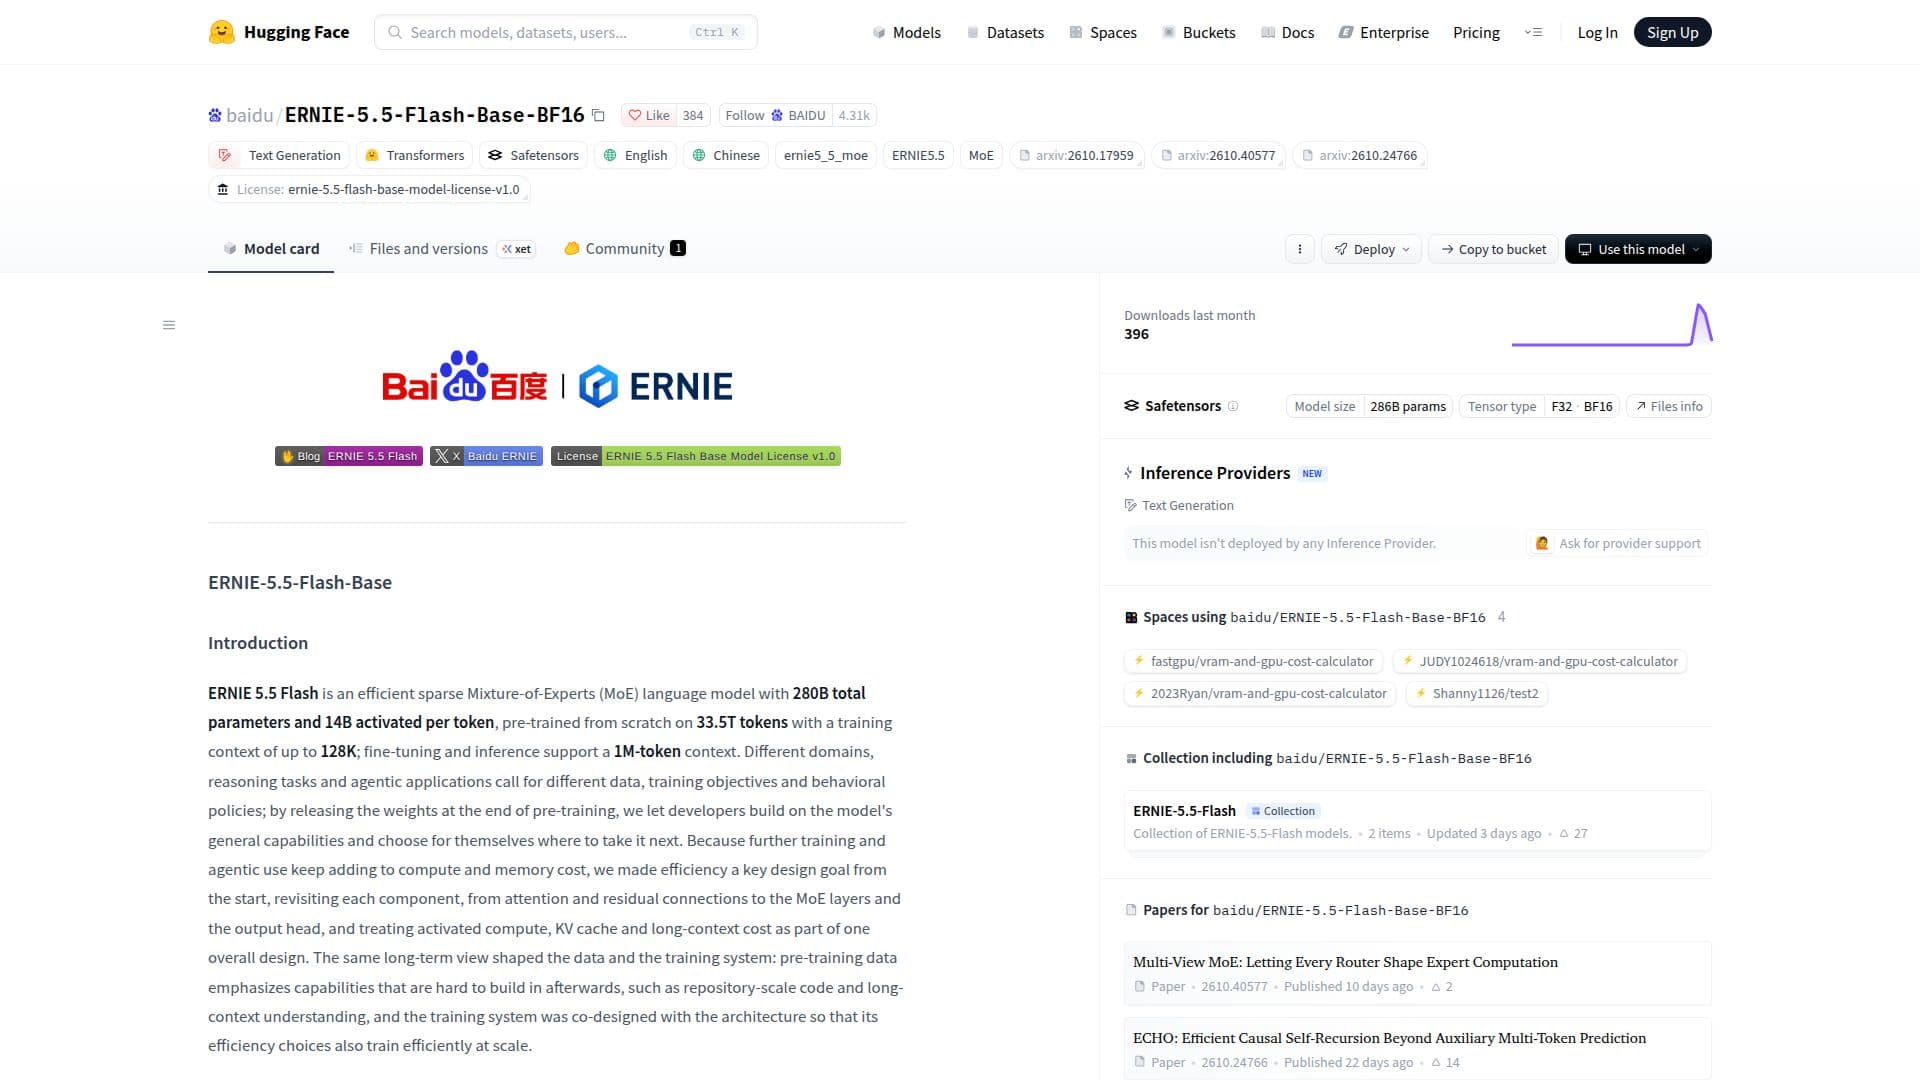
ERNIE-5.5-Flash-Base-BF16 screenshot

ERNIE-5.5-Flash-Base-BF16 is a sophisticated sparse Mixture-of-Experts (MoE) language model developed by Baidu. It features a substantial 280 billion total parameters, with 14 billion activated per token, making it highly efficient for complex language tasks. The model was pre-trained from scratch on an extensive dataset of 33.5 trillion tokens, utilizing a training context of up to 128,000 tokens. For fine-tuning and inference, it supports an impressive 1 million-token context length, enabling deep understanding and generation of long-form content.

Read More

Designed with efficiency as a core principle, ERNIE 5.5 Flash revisits every component, from attention mechanisms and residual connections to MoE layers and the output head. This holistic approach ensures optimal performance while managing compute, KV cache, and long-context costs. The pre-training data emphasizes capabilities crucial for advanced applications, such as repository-scale code understanding and long-context comprehension, allowing developers to build upon its general capabilities for diverse use cases.

ERNIE-5.5-Flash-Base-BF16 represents the checkpoint at the end of pre-training, serving as a foundational model before any mid- or post-training stages. This makes it an ideal starting point for researchers and developers engaged in domain adaptation, instruction tuning, and reinforcement learning. The model has demonstrated strong results across a unified evaluation pipeline, excelling in benchmarks related to knowledge, reasoning, mathematics, code, multilingual tasks, and long-context understanding.

The architecture incorporates a 280B-A14B hybrid-attention MoE with 43 layers, including 1 dense FFN and 42 Multi-Router Latent MoE layers. It features 37 Heavily Compressed Attention (HCA) layers and 6 Multi-head Latent Attention (MLA + DSA) layers with sparse attention. The model utilizes 512 routed experts (top-10) plus 1 shared expert per MoE layer. Innovations like Low-Rank Gated Attention, Virtual Head Attention (VHA), Multi-Router Latent MoE, ECHO, Manifold-constrained Hyper-Connections (mHC), and MultiMax Output Head contribute to its advanced capabilities and efficiency. The tokenizer supports approximately 200,000 entries and tokenizes numbers right-to-left in groups of up to three digits.

Deployment is supported with SGLang and vLLM, allowing for production serving with context lengths up to 1,048,576 tokens. The model is available under the ERNIE 5.5 Flash Base Model License Agreement v1.0.

  • CategoryAI Models & LLMs
  • DeploymentCloud
  • PlatformsWeb

  • 280 billion total parameters

  • 14 billion activated parameters per token

  • Pre-trained on 33.5 trillion tokens

  • Training context up to 128,000 tokens

  • Fine-tuning and inference support 1 million-token context

  • Efficient sparse Mixture-of-Experts (MoE) architecture

  • Hybrid-attention MoE with 43 layers

  • 37 Heavily Compressed Attention (HCA) layers

  • 6 Multi-head Latent Attention (MLA + DSA) layers

  • 512 routed experts (top-10) plus 1 shared expert per MoE layer

  • Low-Rank Gated Attention and Virtual Head Attention (VHA)

  • Multi-Router Latent MoE for accurate expert selection

  • ECHO for multi-horizon loss and speculative decoding

  • Manifold-constrained Hyper-Connections (mHC) for signal propagation

  • MultiMax Output Head for sharpened vocabulary distribution

  • Approximately 200,000-entry BPE tokenizer

  • Support for SGLang and vLLM for production serving

  1. Access Model Page: Navigate to the ERNIE-5.5-Flash-Base-BF16 page on Hugging Face.

  2. Explore Files: Review the model files and documentation available on the page.

  3. Download Model: Download the ERNIE-5.5-Flash-Base-BF16 model checkpoint.

  4. Install vLLM and Plugin: Install vLLM and the ERNIE 5.5 plugin for deployment.

  5. Launch Server: Use SGLang or vLLM to launch the model server.

  6. Send Requests: Send requests to the completions endpoint using tools like curl for inference.

  • Text Generation
  • Domain Adaptation
  • Instruction Tuning
  • Reinforcement Learning Research
  • Code Understanding
  • Long-Context Comprehension
  • Multilingual Applications
  • Reasoning Tasks
  • Agentic Applications

From Baidu

A model in Baidu Wenxin Assistant.

ERNIE-5.5-Flash-Base-BF16 Reviews

Loading...

Popular AI Tools Like ERNIE-5.5-Flash-Base-BF16

ERNIE-5.5-Flash-Base is an efficient sparse Mixture-of-Experts (MoE) language model with 280B total parameters, designed for text generation. Pre-trained on 33.5T tokens, it…

AI Models & LLMs
View Tool

Efficient sparse Mixture-of-Experts (MoE) language model with 280B total parameters, designed for text generation. Pre-trained on 33.5T tokens, it…ERNIE-5.5-Flash-Base is an efficient sparse Mixture-of-Experts (MoE) language model with 280B total parameters, designed for text generation. Pre-trained on 33.5T tokens, it…

AI Models & LLMs
See the Top 100 LLMs

DeepSeek-V4-Pro is an advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…

AI Models & LLMs
View Tool

Advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…DeepSeek-V4-Pro is an advanced AI model designed for efficient million-token context intelligence. It features a hybrid attention architecture and is pre-trained on over 32…

FeaturedAI Models & LLMs
See the Top 100 LLMs

DeepSeek-V3 is a Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…

AI Models & LLMs

Ranked #42 in LLMs

View Tool

Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…DeepSeek-V3 is a Mixture-of-Experts language model with 671 billion parameters, designed for efficient inference and cost-effective training. It excels in various benchmarks,…

FeaturedAI Models & LLMs
Ranked #42 in LLMs

DeepSeek-V4-Pro-DSpark is an advanced language model featuring a hybrid attention architecture and manifold-constrained hyper-connections. It supports a context length of one…

AI Models & LLMs

Ranked #71 in LLMs

View Tool

Advanced language model featuring a hybrid attention architecture and manifold-constrained hyper-connections. It supports a context length of one…DeepSeek-V4-Pro-DSpark is an advanced language model featuring a hybrid attention architecture and manifold-constrained hyper-connections. It supports a context length of one…

AI Models & LLMs
Ranked #71 in LLMs

AliceAI-Foundation-80B-A3B-Base is a foundational language model with a hybrid architecture and MoE layers, featuring 80 billion parameters. It excels in factual knowledge tasks,…

AI Models & LLMs

Ranked #31 in LLMs

View Tool

Foundational language model with a hybrid architecture and MoE layers, featuring 80 billion parameters. It excels in factual knowledge tasks,…AliceAI-Foundation-80B-A3B-Base is a foundational language model with a hybrid architecture and MoE layers, featuring 80 billion parameters. It excels in factual knowledge tasks,…

AI Models & LLMs
Ranked #31 in LLMs

Ling-3.0-flash is a next-generation hybrid reasoning model designed for efficiency and performance. With 124 billion parameters, it excels in reasoning, instruction following, and…

AI Models & LLMs

Ranked #64 in LLMs

View Tool

Next-generation hybrid reasoning model designed for efficiency and performance. With 124 billion parameters, it excels in reasoning, instruction following, and…Ling-3.0-flash is a next-generation hybrid reasoning model designed for efficiency and performance. With 124 billion parameters, it excels in reasoning, instruction following, and…

AI Models & LLMs
Ranked #64 in LLMs

DeepSeek-V3

AI GitHub Repos

DeepSeek-V3 is an open-weight Mixture-of-Experts language model from DeepSeek, with 671 billion total parameters and 37 billion activated per token. Pre-trained on 14.8 trillion…

AI Models & LLMs
View Tool

AI GitHub Repos

Open-weight Mixture-of-Experts language model from DeepSeek, with 671 billion total parameters and 37 billion activated per token. Pre-trained on 14.8 trillion…DeepSeek-V3 is an open-weight Mixture-of-Experts language model from DeepSeek, with 671 billion total parameters and 37 billion activated per token. Pre-trained on 14.8 trillion…

AI Models & LLMs
See the Top 250 AI GitHub Repos

Kimi-K2-Instruct is a state-of-the-art mixture-of-experts language model designed for advanced AI tasks. It excels in reasoning, coding, and tool use, offering robust performance…

AI Models & LLMs

Ranked #51 in LLMs

View Tool

State-of-the-art mixture-of-experts language model designed for advanced AI tasks. It excels in reasoning, coding, and tool use, offering robust performance…Kimi-K2-Instruct is a state-of-the-art mixture-of-experts language model designed for advanced AI tasks. It excels in reasoning, coding, and tool use, offering robust performance…

AI Models & LLMs
Ranked #51 in LLMs
1 of 8