Description
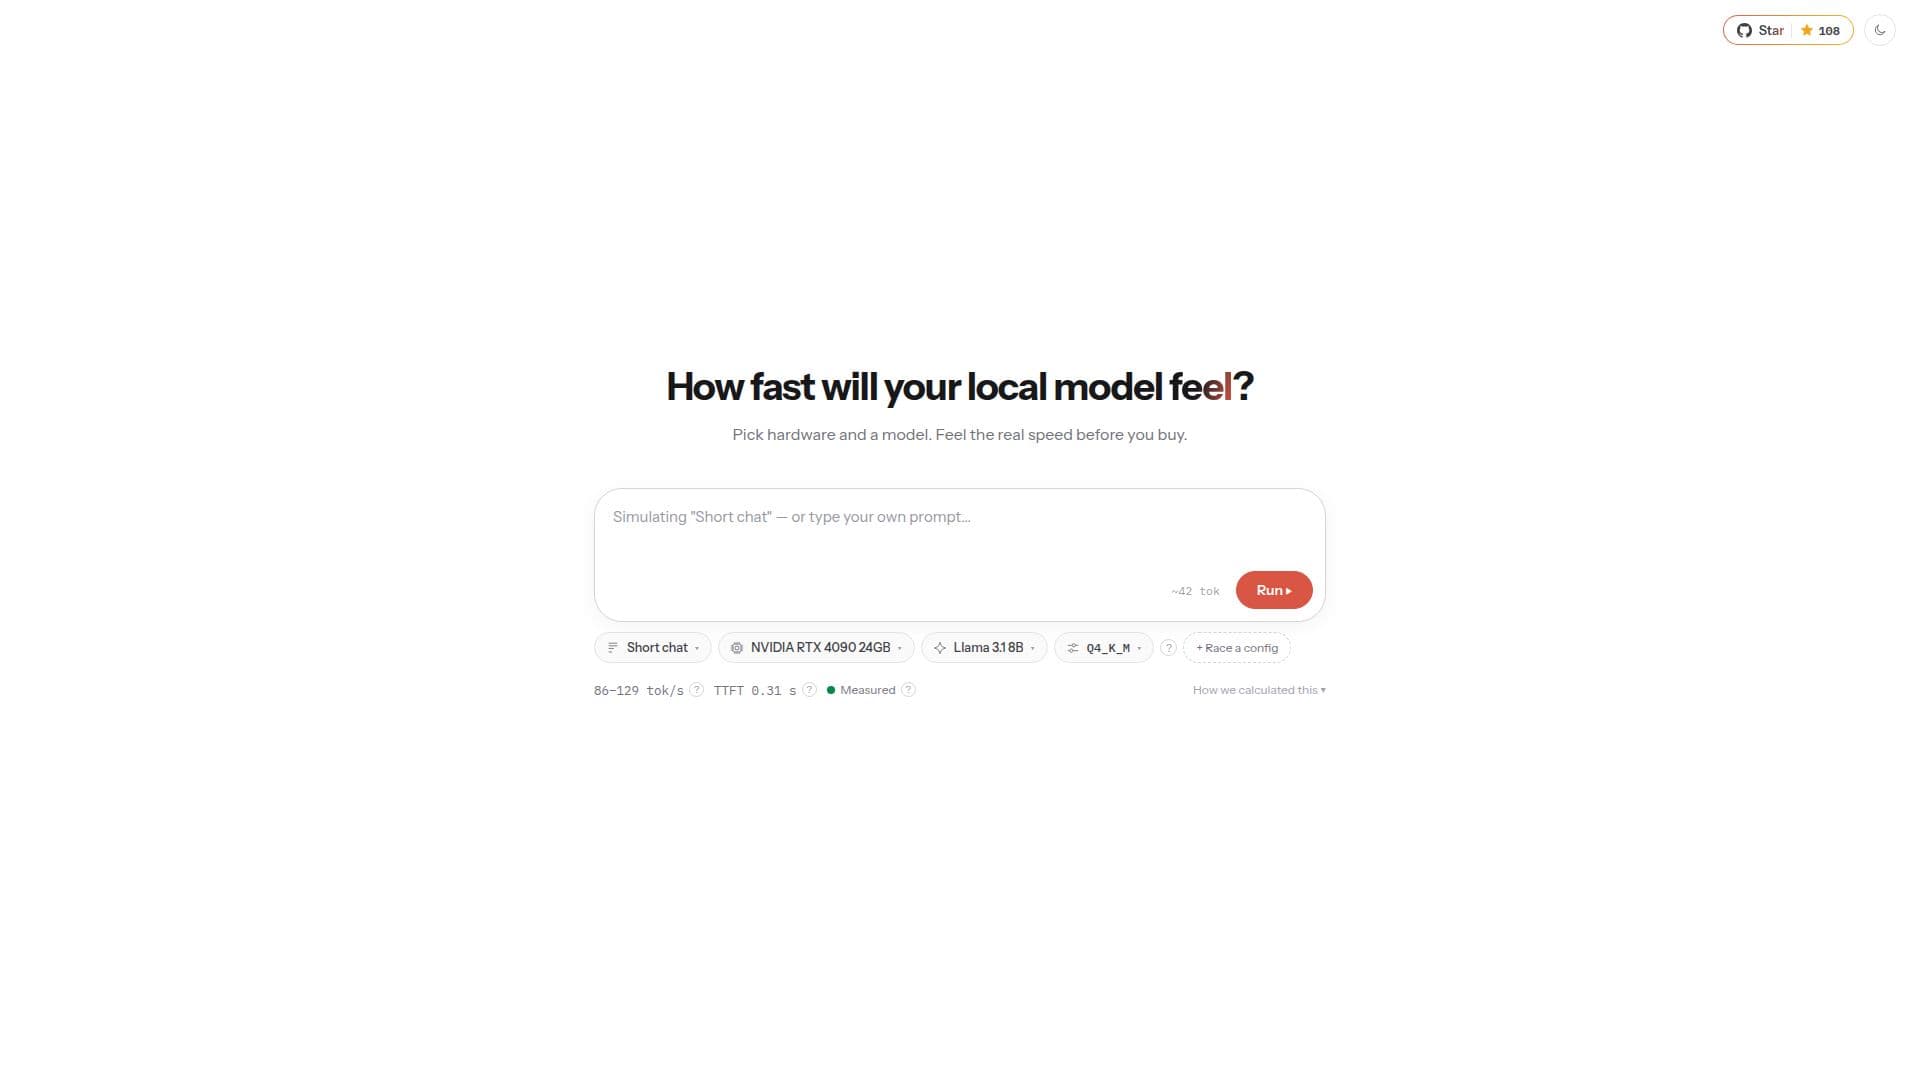
llmspeed is a unique tool designed to help users evaluate the performance of local Large Language Models (LLMs) before making a purchase. By allowing users to select specific hardware and models, llmspeed provides a simulation of real-time performance metrics, such as tokens per second and time-to-first-token. This simulation is grounded in verified benchmarks from various sources, ensuring accuracy and reliability.
Read More
The platform supports a wide range of hardware options, including NVIDIA GPUs, AMD processors, and Apple Macs, among others. Users can choose from models like Qwen, GLM, Gemma, and GPT-OSS, providing a comprehensive evaluation experience. llmspeed's open-source nature, available on GitHub, allows for community contributions and transparency.
With a pricing model set at USD 0, llmspeed is accessible to all users interested in understanding the potential speed of their local LLMs. This tool is particularly beneficial for developers, researchers, and AI enthusiasts who require precise performance insights before investing in specific hardware or models.
Overall, llmspeed offers a valuable service by bridging the gap between hardware capabilities and model performance, enabling informed purchasing decisions and optimizing AI workflows.
- CategoryMLOps & Model Deployment
- Pricing ModelFree
- DeploymentCloud
- PlatformsWeb
llmspeed's Core Features
Simulates tokens per second
Calculates time-to-first-token
Supports multiple hardware options
Includes various LLM models
Based on verified benchmarks
Open-source on GitHub
Free to use
Community-driven insights
How to use llmspeed?
Select hardware: Choose from a variety of supported devices
Select model: Pick an LLM model to test
Simulate: Run the simulation to see performance metrics
Evaluate: Analyze the results to make informed decisions
llmspeed's Use Cases
- Hardware Evaluation
- Model Comparison
- Performance Benchmarking
- Research and Development
- AI Workflow Optimization