ToolPotion
AI Advisor
Submit a Tool (Free)

ComputeArena

ComputeArena provides a platform for community-submitted benchmarks of local AI models. It allows users to compare performance across different models, quantisations, and chips, using signed reports from community hardware.

Visit Website
Share
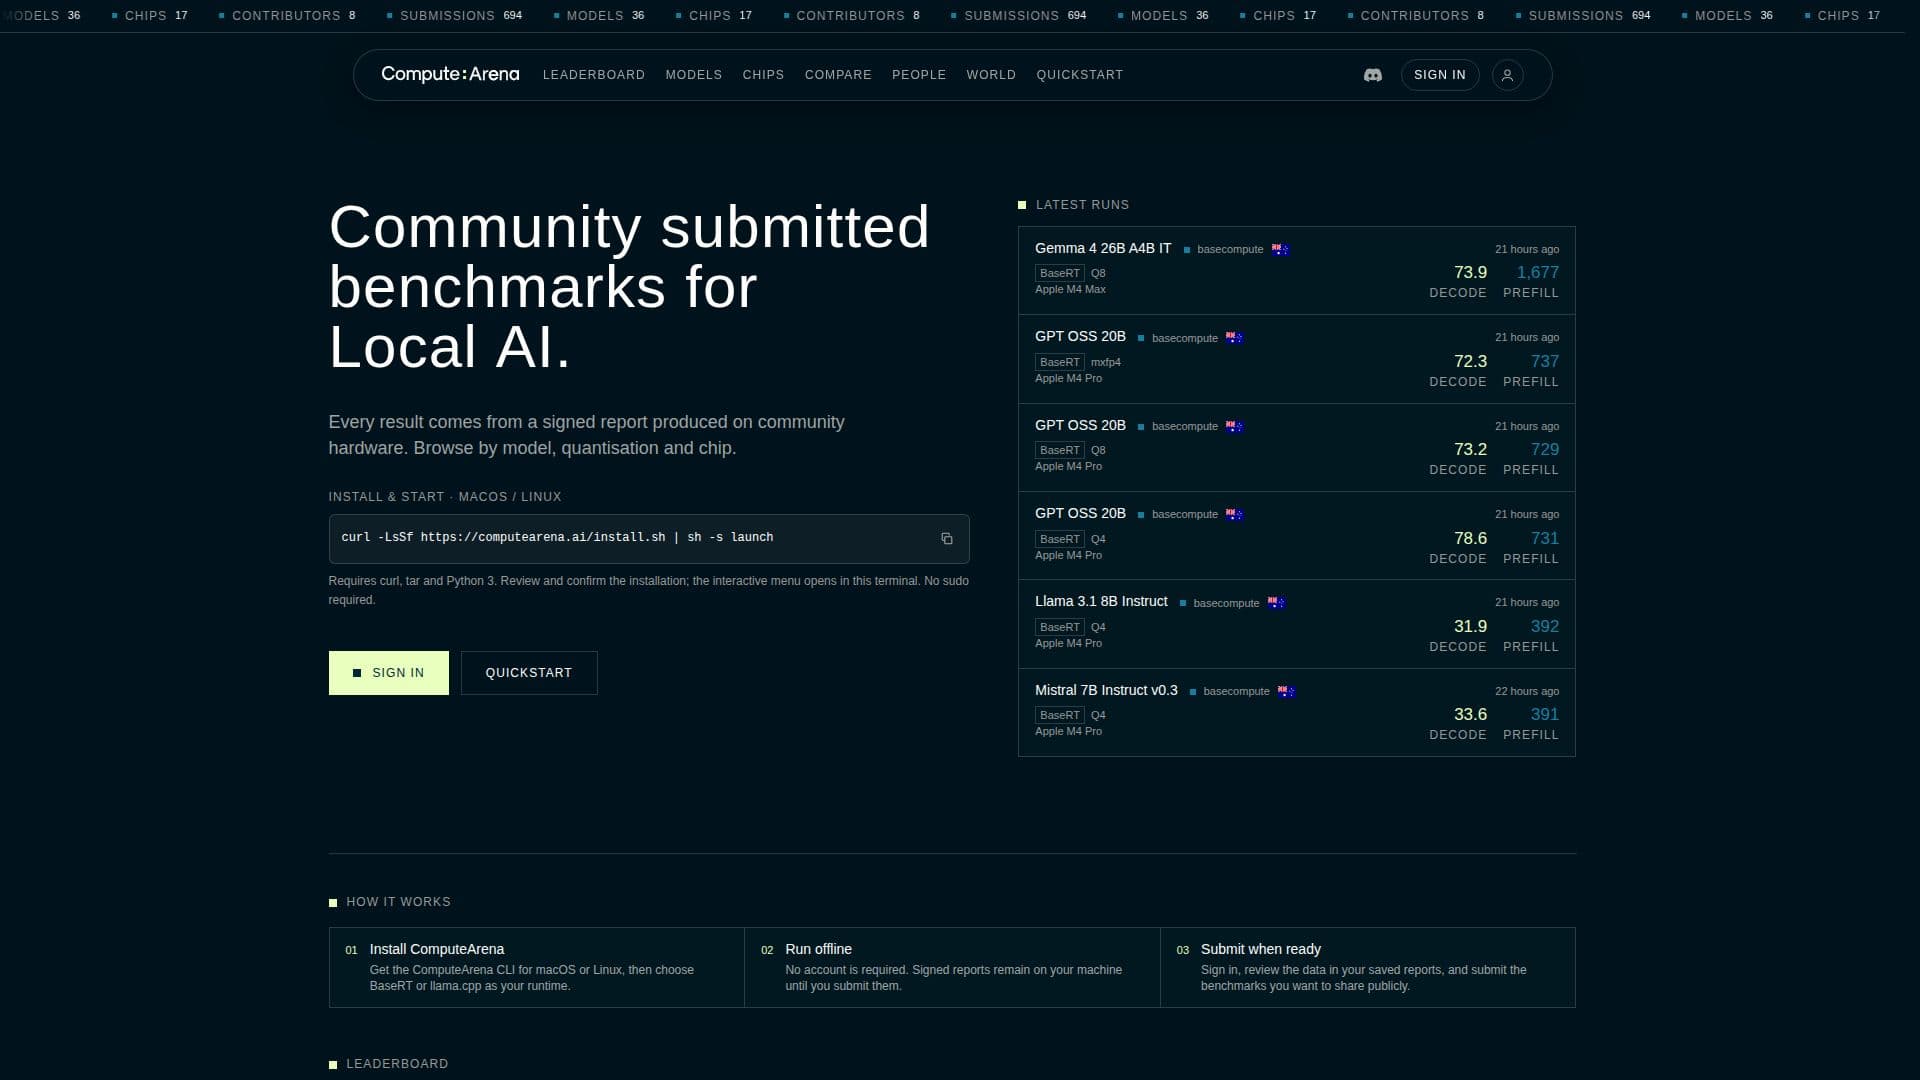
ComputeArena screenshot

ComputeArena is a platform dedicated to providing local AI benchmarks through community contributions. It hosts 694 benchmarks across 36 models and 17 chips, contributed by 8 community members. The platform allows users to decode and prefill tokens per second by model, quantisation, and chip, measured with BaseRT or llama.cpp.

Read More

The benchmarks are submitted by the community and are based on signed reports produced on community hardware. Users can browse results by model, quantisation, and chip, making it easier to compare performance across different configurations. The platform supports macOS and Linux, requiring curl, tar, and Python 3 for installation. Users can install the ComputeArena CLI and choose between BaseRT or llama.cpp as their runtime.

ComputeArena operates offline, meaning no account is required to run benchmarks. Signed reports remain on the user's machine until they decide to submit them. When ready, users can sign in, review their saved reports, and submit the benchmarks they wish to share publicly.

The platform provides headline rankings that compare compatible PP512 prefill and TG128 decode workloads, with the measured workload displayed alongside each result. This feature allows users to gain insights into the performance of different AI models and configurations, aiding in the selection of the best setup for their needs.

  • CategoryMachine Learning & Data Science
  • Pricing ModelFree
  • DeploymentSelf-hosted
  • PlatformsmacOS, Linux

  • Community-submitted benchmarks

  • Supports macOS and Linux

  • No account required for offline use

  • Signed reports for authenticity

  • Comparison by model, quantisation, and chip

  • Uses BaseRT or llama.cpp runtimes

  • Interactive installation menu

  • Headline rankings for performance comparison

  1. Install: Get the ComputeArena CLI for macOS or Linux

  2. Choose Runtime: Select BaseRT or llama.cpp

  3. Run Offline: Execute benchmarks without an account

  4. Submit: Sign in and submit benchmarks when ready

  • Model Performance Comparison
  • Community Benchmarking
  • Offline Benchmarking
  • Quantisation Analysis
  • Chip Performance Evaluation

ComputeArena Reviews

Loading...

Popular AI Tools Like ComputeArena

CanIRun.ai

AI Apps

A free tool that detects your GPU or Mac and shows which open AI models, including LLMs, coding, image, and video models, you can run locally, with VRAM requirements and speed…

Machine Learning & Data Science

Ranked #47 in Machine Learning & Data Science

View Tool

AI Apps

A free tool that detects your GPU or Mac and shows which open AI models, including LLMs, coding, image, and video models, you can run locally, with VRAM requirements and speed…

Machine Learning & Data Science
Ranked #47 in Machine Learning & Data Science

The Local AI Playground is a free, open-source native app for running AI models offline and in private. It simplifies AI inferencing with a Rust backend, requiring no GPU. Manage…

Machine Learning Platforms
View Tool

The Local AI Playground is a free, open-source native app for running AI models offline and in private. It simplifies AI inferencing with a Rust backend, requiring no GPU. Manage…

Machine Learning Platforms
See the Top 250 AI Apps

ZETIC Melange automates on-device AI deployment for any model on any device. Built by ex-Qualcomm engineers, it optimizes NPU acceleration, benchmarks on over 200 devices, and…

MLOps & Model Deployment

Ranked #137 in MLOps & Model Deployment

View Tool

Automates on-device AI deployment for any model on any device. Built by ex-Qualcomm engineers, it optimizes NPU acceleration, benchmarks on over 200 devices, and…ZETIC Melange automates on-device AI deployment for any model on any device. Built by ex-Qualcomm engineers, it optimizes NPU acceleration, benchmarks on over 200 devices, and…

MLOps & Model Deployment
Ranked #137 in MLOps & Model Deployment

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
View Tool

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
See the Top 250 AI Apps

OpenAI Evals Framework

AI GitHub Repos

OpenAI Evals is a framework designed for evaluating large language models (LLMs) and LLM systems. It serves as an open-source registry of benchmarks, facilitating the assessment…

Machine Learning & Data Science
View Tool

AI GitHub Repos

Framework designed for evaluating large language models (LLMs) and LLM systems. It serves as an open-source registry of benchmarks, facilitating the assessment…OpenAI Evals is a framework designed for evaluating large language models (LLMs) and LLM systems. It serves as an open-source registry of benchmarks, facilitating the assessment…

Machine Learning & Data Science
See the Top 250 AI GitHub Repos

TokenSpeed

AI GitHub Repos

TokenSpeed is a high-performance LLM inference engine designed to deliver rapid processing speeds. It is optimized for large language models, providing efficient and scalable…

Machine Learning & Data Science

Ranked #189 in AI GitHub Repos

View Tool

AI GitHub Repos

High-performance LLM inference engine designed to deliver rapid processing speeds. It is optimized for large language models, providing efficient and scalable…TokenSpeed is a high-performance LLM inference engine designed to deliver rapid processing speeds. It is optimized for large language models, providing efficient and scalable…

Machine Learning & Data Science
Ranked #189 in AI GitHub Repos

Project Maya

AI GitHub Repos

Project Maya allows users to run the GLM-5.3-Flash model privately on their own GPUs, supporting both NVIDIA and AMD hardware. It offers an engine, server, dashboard, and APIs…

Machine Learning & Data Science

Ranked #24 in AI Models & LLMs

View Tool

AI GitHub Repos

Allows users to run the GLM-5.3-Flash model privately on their own GPUs, supporting both NVIDIA and AMD hardware. It offers an engine, server, dashboard, and APIs…Project Maya allows users to run the GLM-5.3-Flash model privately on their own GPUs, supporting both NVIDIA and AMD hardware. It offers an engine, server, dashboard, and APIs…

Machine Learning & Data Science
Ranked #24 in AI Models & LLMs

Models.dev

AI Apps

Models.dev is an open-source database offering comprehensive details on AI model specifications, pricing, and features. It provides insights into various models from leading labs,…

Machine Learning Platforms
View Tool

AI Apps

Open-source database offering comprehensive details on AI model specifications, pricing, and features. It provides insights into various models from leading labs,…Models.dev is an open-source database offering comprehensive details on AI model specifications, pricing, and features. It provides insights into various models from leading labs,…

Machine Learning Platforms
See the Top 250 AI Apps
1 of 8