Description
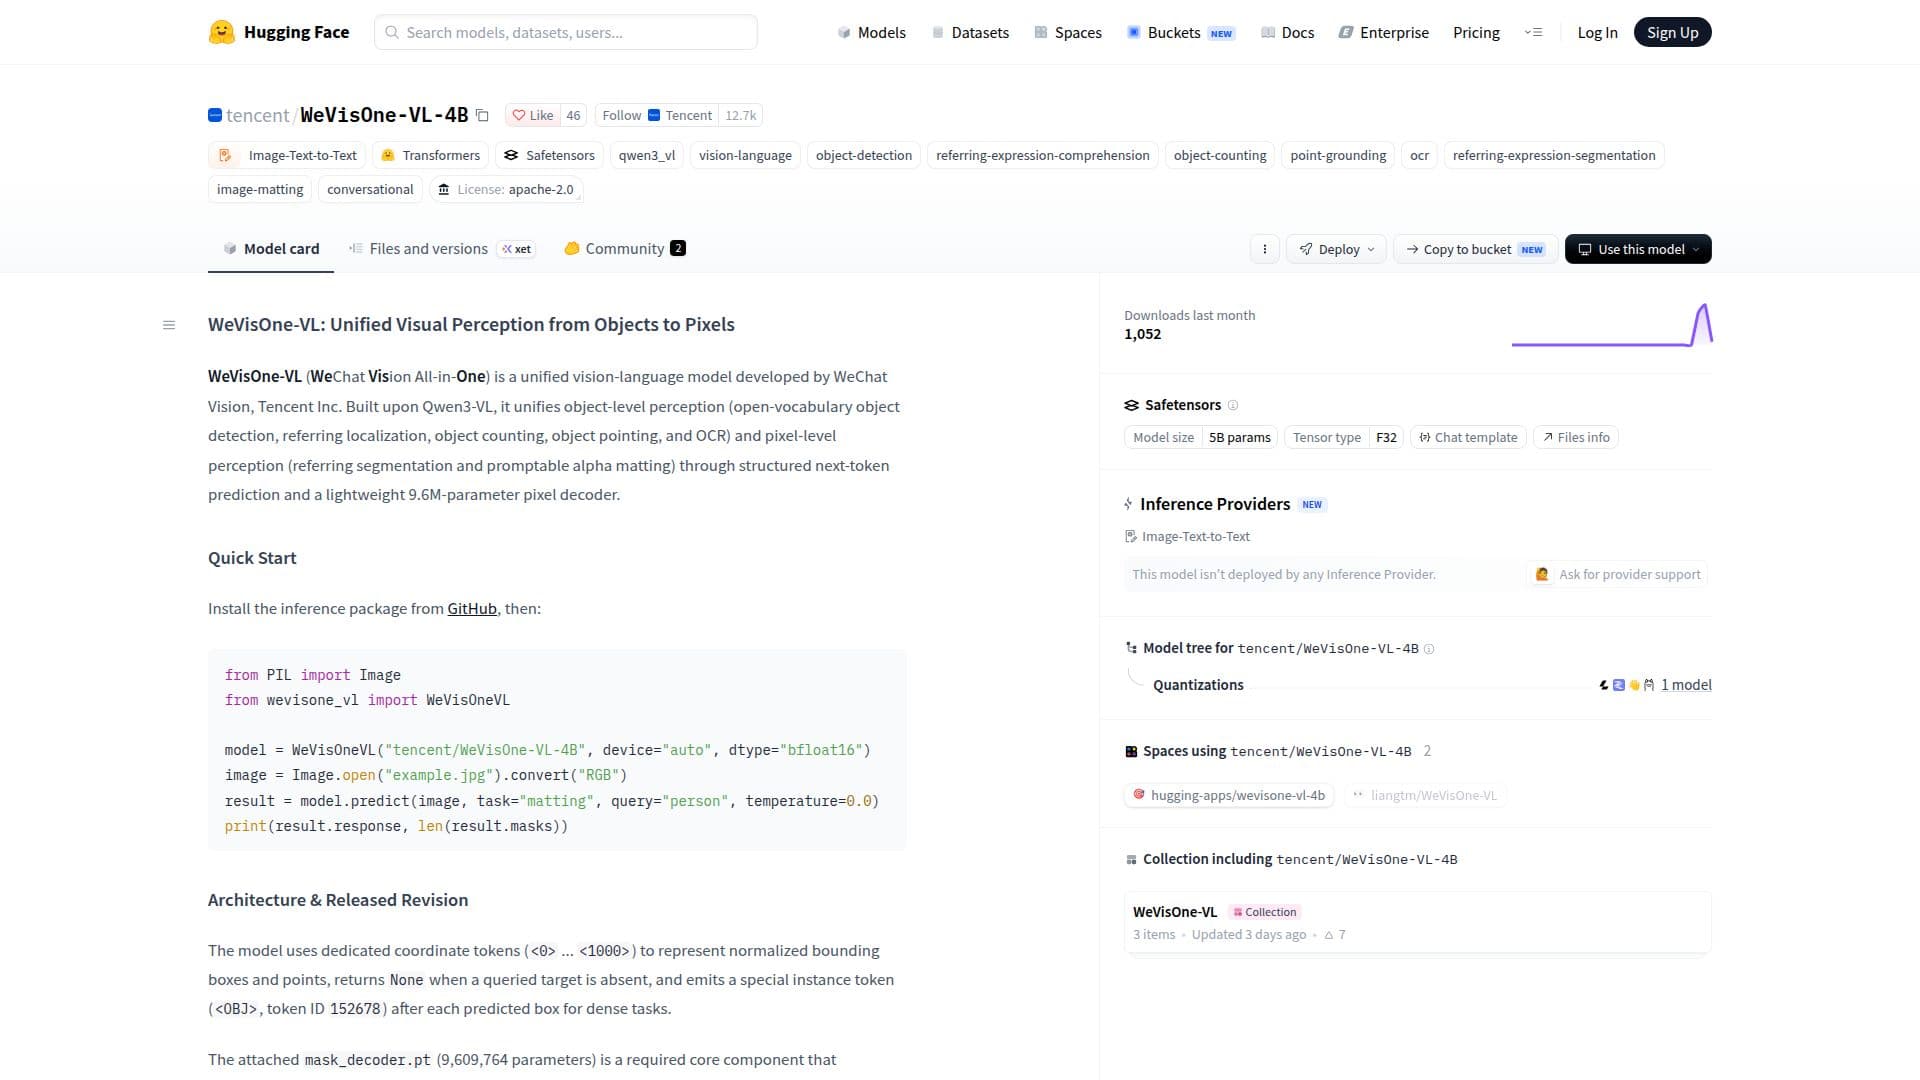
WeVisOne-VL is a vision-language model developed by WeChat Vision, a part of Tencent Inc. It is designed to unify object-level and pixel-level perception tasks. Built upon the Qwen3-VL framework, WeVisOne-VL supports a range of visual tasks including open-vocabulary object detection, referring localization, object counting, object pointing, and optical character recognition (OCR). Additionally, it handles pixel-level tasks such as referring segmentation and promptable alpha matting. The model employs structured next-token prediction and features a lightweight 9.6M-parameter pixel decoder.
Read More
The architecture of WeVisOne-VL includes dedicated coordinate tokens for representing normalized bounding boxes and points. It uses a special instance token for dense tasks and integrates a mask decoder as a core component. This decoder combines a Visual Feature Adapter, a Box-Guided Query Decoder, and an Instance-Conditioned Dense Prediction Head to refine predictions and output full-resolution alpha mattes.
WeVisOne-VL is intended for research purposes in visual grounding, referring localization, pointing, counting, OCR localization, referring segmentation, and image matting. It is not designed for autonomous high-impact decision-making or individual identification. The model is efficient in generating structured outputs but does not support explicit chain-of-thought reasoning and is currently limited to single-turn image perception.
The model is released under the Apache License 2.0, with third-party components retaining their original licenses. It has been downloaded over 1,000 times in the last month, indicating its growing popularity in the research community.
- CategoryAI Models & LLMs
- Pricing ModelFree
- DeploymentCloud
- PlatformsWeb
WeVisOne-VL Highlights
Unified vision-language model
Object-level perception
Pixel-level perception
9.6M-parameter pixel decoder
Structured next-token prediction
Dedicated coordinate tokens
Special instance token for dense tasks
Apache License 2.0
Getting Started with WeVisOne-VL
Access model page: Visit the Hugging Face page for WeVisOne-VL
Authenticate: Ensure you have the necessary permissions to access the model
Configure: Set up the model parameters as per your research needs
Send prompts: Input your visual tasks for processing
Fine-tune: Adjust the model for specific tasks if required
WeVisOne-VL's Use Cases
- Object Detection
- Referring Localization
- Object Counting
- OCR Localization
- Image Matting