ToolPotion
AI Advisor
Submit a Tool (Free)

WeVisOne-VL

LLMsComputer Vision ToolsOpen source · Web

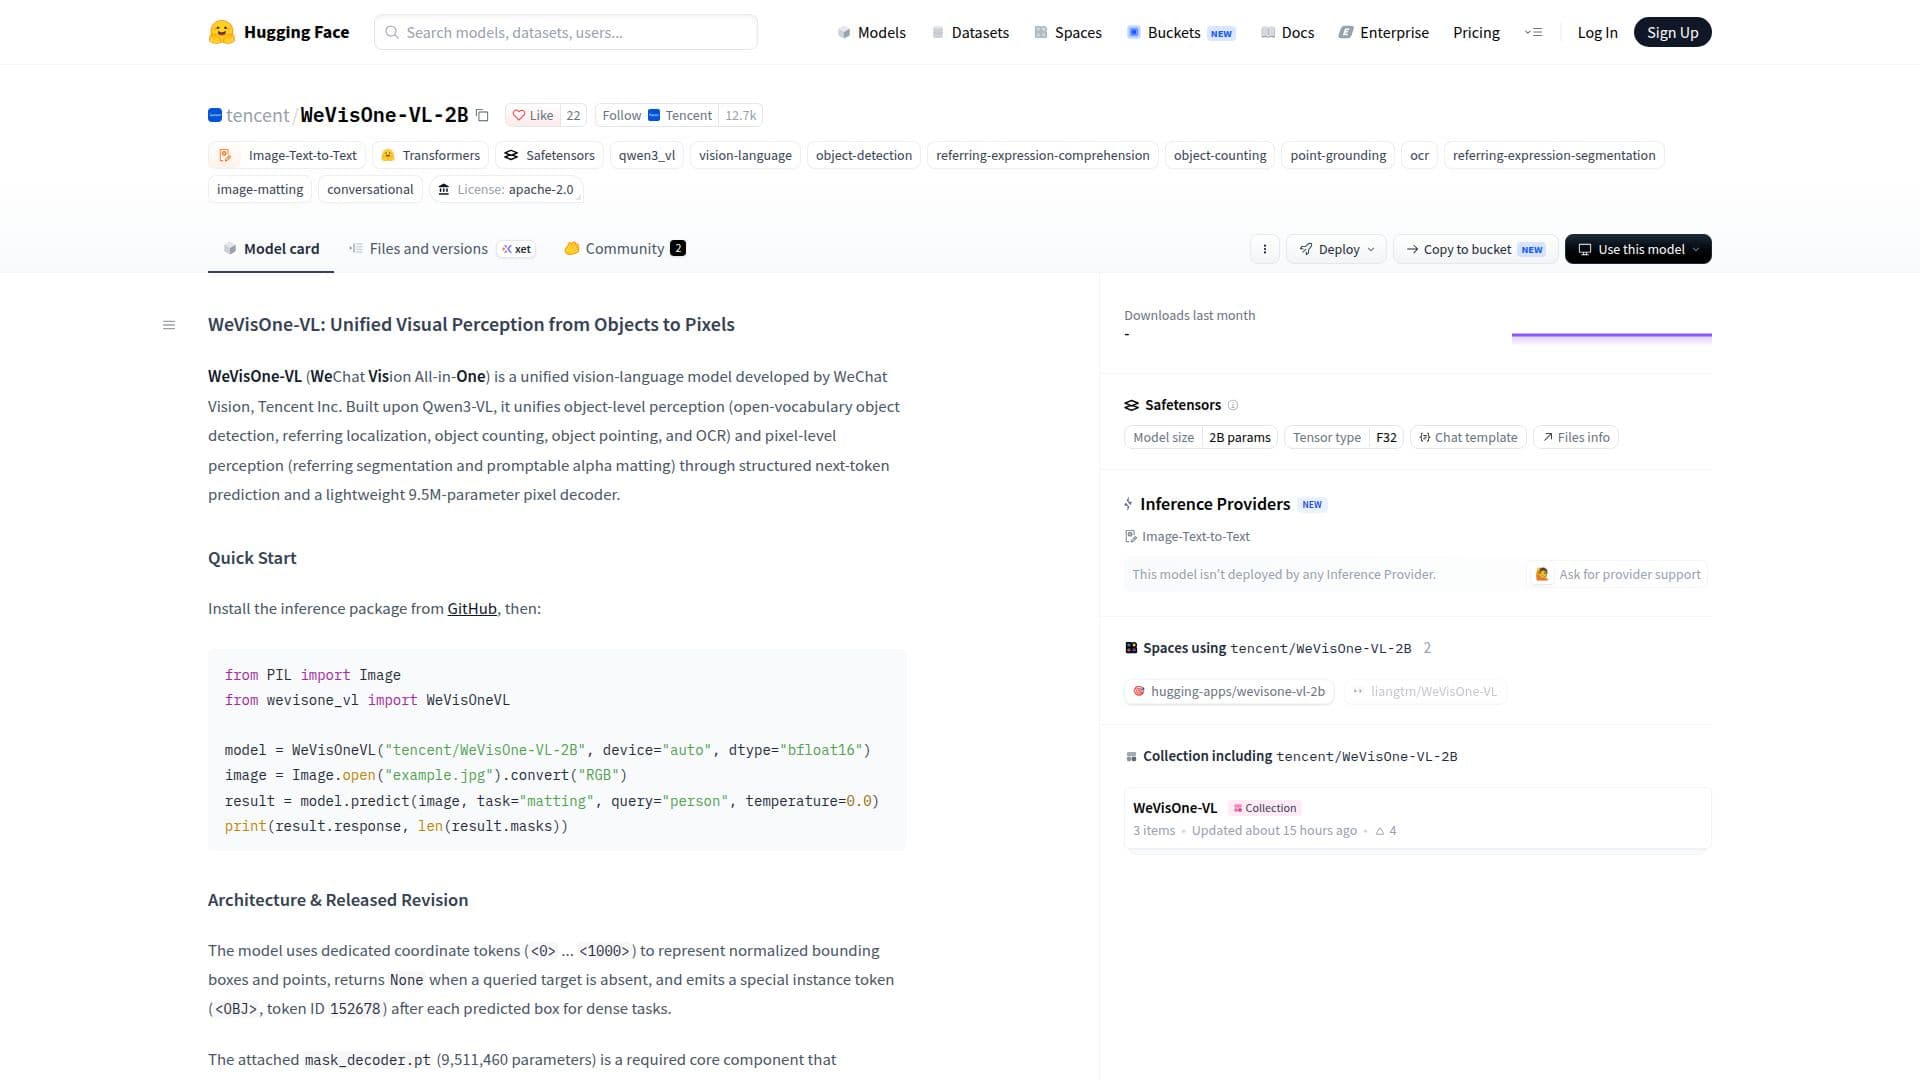
WeVisOne-VL is a unified vision-language model developed by WeChat Vision, Tencent Inc. It integrates object-level and pixel-level perception for tasks like object detection and image matting, designed for research purposes.

Visit Website
Share
WeVisOne-VL screenshot

WeVisOne-VL is a sophisticated vision-language model developed by WeChat Vision, a division of Tencent Inc. This model is built upon the Qwen3-VL framework and is designed to unify object-level and pixel-level perception tasks. It is capable of handling open-vocabulary object detection, referring localization, object counting, object pointing, and optical character recognition (OCR). Additionally, it supports pixel-level tasks such as referring segmentation and promptable alpha matting.

Read More

The model employs structured next-token prediction and features a lightweight pixel decoder with 9.5 million parameters. A key component of WeVisOne-VL is the mask_decoder.pt, which integrates a Visual Feature Adapter, a Box-Guided Query Decoder, and an Instance-Conditioned Dense Prediction Head. These components work together to refine predictions and output high-resolution alpha mattes.

WeVisOne-VL is intended for research applications in visual grounding, localization, pointing, counting, OCR, segmentation, and image matting. It is not designed for autonomous decision-making or individual identification. The model is optimized for single-turn image perception and does not support video grids.

The model is released under the Apache License 2.0, with third-party components retaining their original licenses. Users are encouraged to review the source files for specific licensing details.

  • CategoryComputer Vision Tools
  • Pricing ModelOpen source
  • DeploymentCloud
  • PlatformsWeb

  • Unified vision-language model

  • Object-level perception

  • Pixel-level perception

  • Open-vocabulary object detection

  • Referring segmentation

  • Promptable alpha matting

  • Structured next-token prediction

  • Lightweight pixel decoder

  1. Access model page: Visit the Hugging Face model page

  2. Authenticate: Log in to your Hugging Face account

  3. Configure: Set up the model with necessary parameters

  4. Send prompts: Input your visual data for processing

  5. Fine-tune: Adjust model settings for specific tasks

  • Visual Grounding
  • Object Detection
  • Image Matting
  • OCR Localization
  • Referring Segmentation

Popular AI Tools Like WeVisOne-VL

Qwen2-VL-7B-Instruct is an advanced AI model designed for visual understanding and multilingual support. It excels in processing images and videos, offering state-of-the-art…

Computer Vision Tools
View Tool

Advanced AI model designed for visual understanding and multilingual support. It excels in processing images and videos, offering state-of-the-art…Qwen2-VL-7B-Instruct is an advanced AI model designed for visual understanding and multilingual support. It excels in processing images and videos, offering state-of-the-art…

Computer Vision Tools
See the Top 5 AI Models

CLIP ViT-B/32

AI Models

The clip-vit-base-patch32 model by OpenAI is designed for zero-shot image classification tasks. It utilizes a Vision Transformer architecture to enhance robustness and…

Computer Vision Tools
View Tool

AI Models

The clip-vit-base-patch32 model by OpenAI is designed for zero-shot image classification tasks. It utilizes a Vision Transformer architecture to enhance robustness and…

FeaturedComputer Vision Tools
See the Top 5 AI Models

Florence-2 is an advanced vision foundation model by Microsoft, designed to handle a variety of vision and vision-language tasks. It uses a prompt-based approach for tasks like…

AI Models & LLMs
View Tool

Advanced vision foundation model by Microsoft, designed to handle a variety of vision and vision-language tasks. It uses a prompt-based approach for tasks like…Florence-2 is an advanced vision foundation model by Microsoft, designed to handle a variety of vision and vision-language tasks. It uses a prompt-based approach for tasks like…

AI Models & LLMs
See the Top 5 AI Models

Qwen-VL

AI GitHub Repos

Qwen-VL is a large vision language model developed by Alibaba Cloud. It offers advanced capabilities for chat and vision tasks, providing a robust platform for AI applications in…

AI Models & LLMs
View Tool

AI GitHub Repos

Large vision language model developed by Alibaba Cloud. It offers advanced capabilities for chat and vision tasks, providing a robust platform for AI applications in…Qwen-VL is a large vision language model developed by Alibaba Cloud. It offers advanced capabilities for chat and vision tasks, providing a robust platform for AI applications in…

AI Models & LLMs
See the Top 250 AI GitHub Repos

Computer Vision Toolbox provides algorithms and apps for designing and testing computer vision systems, including visual inspection, object detection, and feature matching. It…

Computer Vision Tools
View Tool

Provides algorithms and apps for designing and testing computer vision systems, including visual inspection, object detection, and feature matching. It…Computer Vision Toolbox provides algorithms and apps for designing and testing computer vision systems, including visual inspection, object detection, and feature matching. It…

Computer Vision Tools
See the Top 250 AI Apps

Ultralytics YOLO

AI GitHub Repos

Ultralytics YOLO includes YOLO26, YOLO11, and YOLOv8, providing capabilities for object detection, instance segmentation, semantic segmentation, image classification, pose…

Computer Vision Tools

Ranked #18 in AI GitHub Repos

View Tool

AI GitHub Repos

Includes YOLO26, YOLO11, and YOLOv8, providing capabilities for object detection, instance segmentation, semantic segmentation, image classification, pose…Ultralytics YOLO includes YOLO26, YOLO11, and YOLOv8, providing capabilities for object detection, instance segmentation, semantic segmentation, image classification, pose…

FeaturedComputer Vision Tools
Ranked #18 in AI GitHub Repos

Qwen2-VL-72B-Instruct is an advanced AI model designed for state-of-the-art visual understanding and multilingual support. It excels in processing images, videos, and complex…

AI Models & LLMs
View Tool

Advanced AI model designed for state-of-the-art visual understanding and multilingual support. It excels in processing images, videos, and complex…Qwen2-VL-72B-Instruct is an advanced AI model designed for state-of-the-art visual understanding and multilingual support. It excels in processing images, videos, and complex…

AI Models & LLMs
See the Top 5 AI Models

An end-to-end computer vision platform to annotate data, train YOLO models, and deploy them globally, built around the widely adopted Ultralytics YOLO open-source framework.

Computer Vision ToolsManufacturing & Industrial

Ranked #6 in Manufacturing & Industrial

View Tool

An end-to-end computer vision platform to annotate data, train YOLO models, and deploy them globally, built around the widely adopted Ultralytics YOLO open-source framework.

FeaturedComputer Vision ToolsManufacturing & Industrial
Ranked #6 in Manufacturing & Industrial
1 of 8