Description
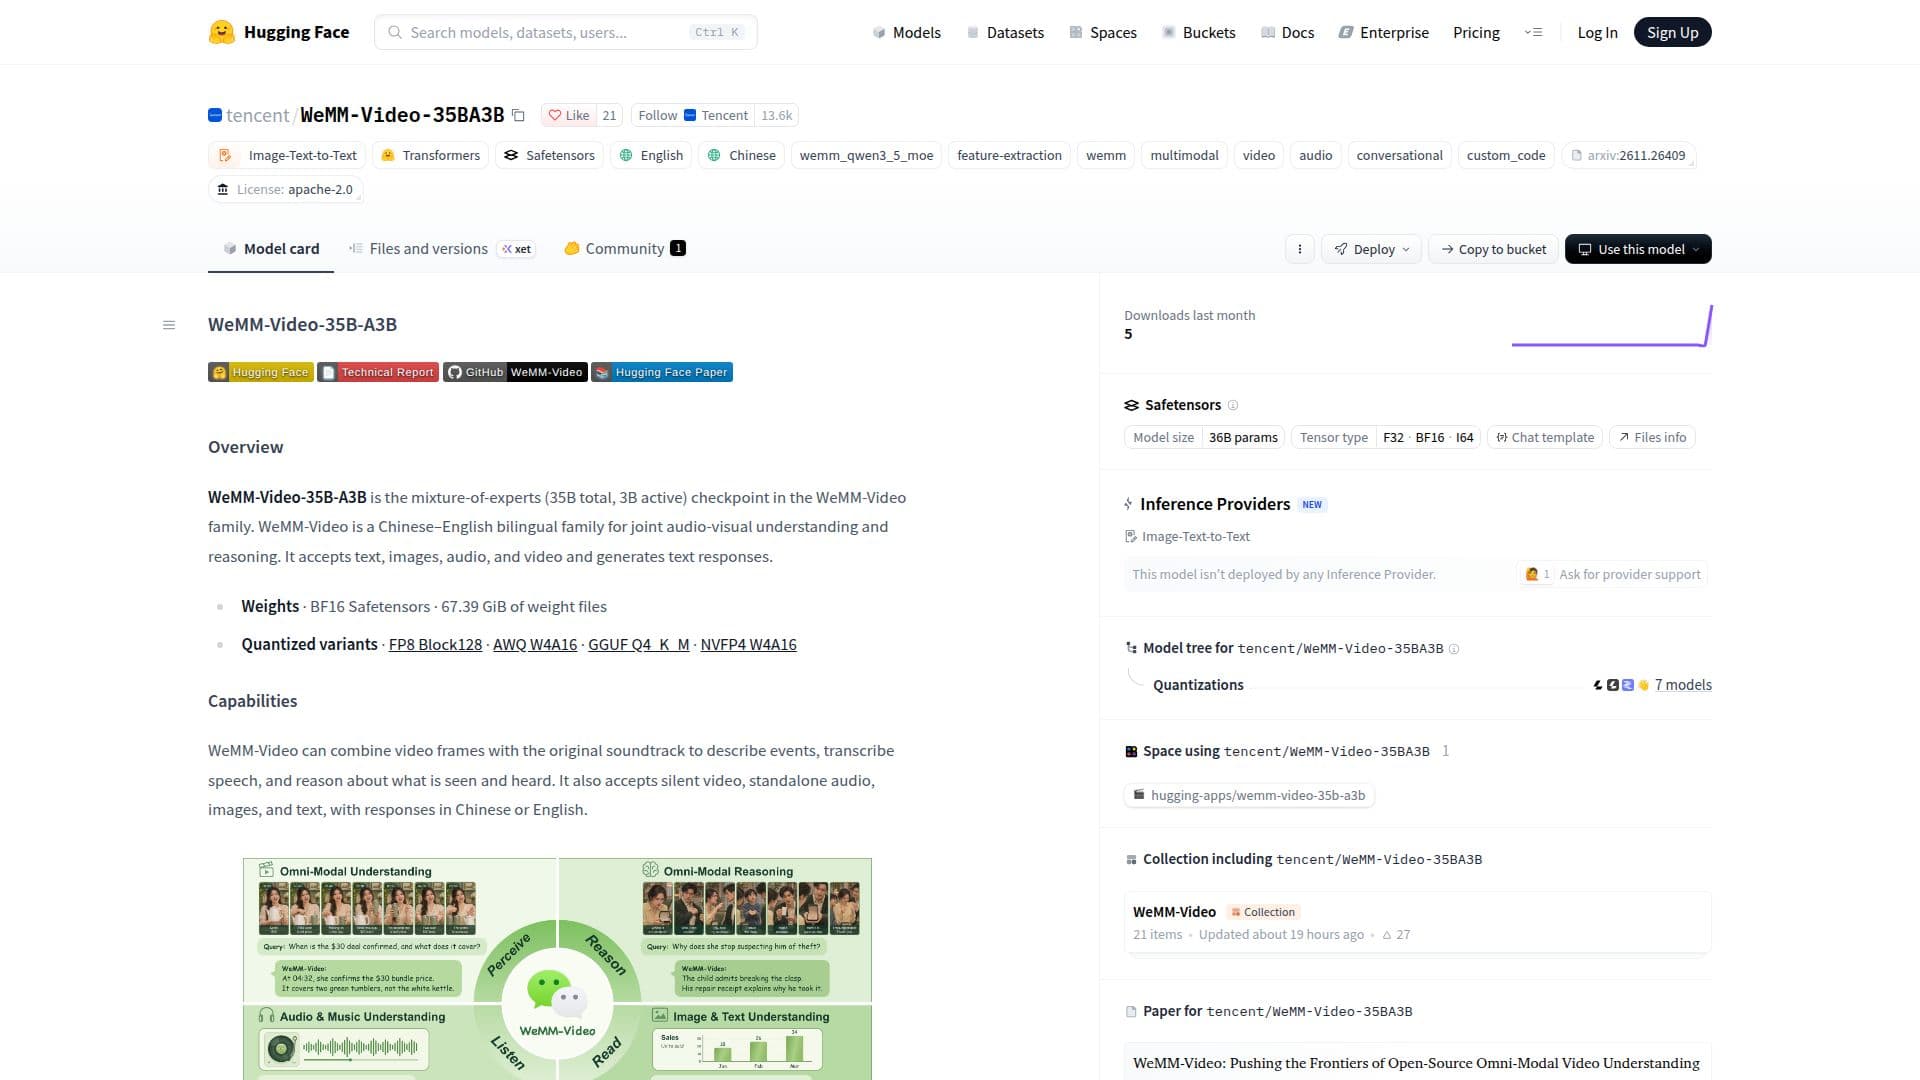
WeMM-Video-35B-A3B is a sophisticated mixture-of-experts model, part of the broader WeMM-Video family, developed for comprehensive audio-visual understanding and reasoning. With 35 billion total parameters and 3 billion active parameters, this model is specifically engineered to process and interpret multimodal inputs, including text, images, audio, and video, generating coherent text responses in either Chinese or English.
Read More
The model's core capabilities include the ability to combine video frames with their original soundtracks to describe events, accurately transcribe speech, and perform reasoning tasks based on both visual and auditory information. It is also versatile enough to handle silent video, standalone audio, images, and text inputs independently. This makes it suitable for a wide range of applications requiring deep contextual understanding across different media types.
Architecturally, WeMM-Video-35B-A3B employs vision and audio encoders to convert media inputs into tokens, which are then processed by a language model alongside text. Video frames are enriched with timestamps to maintain temporal context. The model family underwent extensive pretraining on approximately 1.2 trillion multimodal tokens, followed by advanced post-training techniques such such as multi-teacher OPD, anti-repetition MrDPO, and specialist reinforcement learning to enhance its performance and robustness.
Deployment and integration are facilitated through various serving options. Users can set up the Transformers environment and run examples directly from the WeMM-Video repository. The model supports quantized variants like FP8 Block128, AWQ W4A16, GGUF Q4_K_M, and NVFP4 W4A16. For serving, it is compatible with patched versions of vLLM (0.18.0 and 0.31.0) and SGLang (0.5.16 or 0.5.19), allowing for efficient inference, including tensor parallelism across multiple GPUs. The model also offers different chat modes, including a default instruct mode and a 'Thinking mode' for reasoning responses.
WeMM-Video-35B-A3B has demonstrated strong performance, establishing a new open-source state-of-the-art. It has been shown to outperform proprietary models like Qwen3.5-Omni-Flash and Seed2.0-Mini-0428, significantly narrowing the performance gap with advanced models such as Gemini-3.0-Flash. The model is released under the Apache License 2.0, promoting open access and collaboration within the AI community.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsWeb
WeMM-Video-35B-A3B Highlights
Chinese-English bilingual processing
Joint audio-visual understanding and reasoning
Accepts text, images, audio, and video inputs
Generates text responses
Describes events from video frames and soundtracks
Transcribes speech from audio
Reasons about visual and auditory information
Supports silent video and standalone audio processing
Mixture-of-experts architecture (35B total, 3B active parameters)
Pretrained on 1.2 trillion multimodal tokens
Post-trained with multi-teacher OPD and MrDPO
Specialist reinforcement learning for enhanced performance
Supports various quantized variants (FP8, AWQ, GGUF, NVFP4)
Compatible with patched vLLM and SGLang for serving
Offers Instruct and Thinking chat modes
Getting Started with WeMM-Video-35B-A3B
Set up Environment: Install the Transformers environment and necessary dependencies.
Load Model: Load the WeMM-Video-35B-A3B model and processor from Hugging Face Hub.
Prepare Inputs: Provide media inputs such as MP4 video files, standalone audio, images, or text.
Process Media: Use the script to process video frames alone or with the original audio track.
Generate Responses: Send requests to the model, specifying chat mode (Instruct or Thinking) for text generation.
Serve Model (Optional): Install the WeMM runtime patch and use patched vLLM or SGLang for API serving.
Send API Requests: Use the bundled request client to send media inline to the OpenAI-compatible chat endpoint.
WeMM-Video-35B-A3B's Use Cases
- Video Content Analysis
- Speech Transcription
- Multimodal Reasoning
- Bilingual Content Processing
- Audio-Visual Event Description
- AI Model Development
- Research and Experimentation