ToolPotion
AI Advisor
Submit a Tool (Free)

TML-d24-varloop-research

LLMs#96AI Models & LLMsOpen source · Web

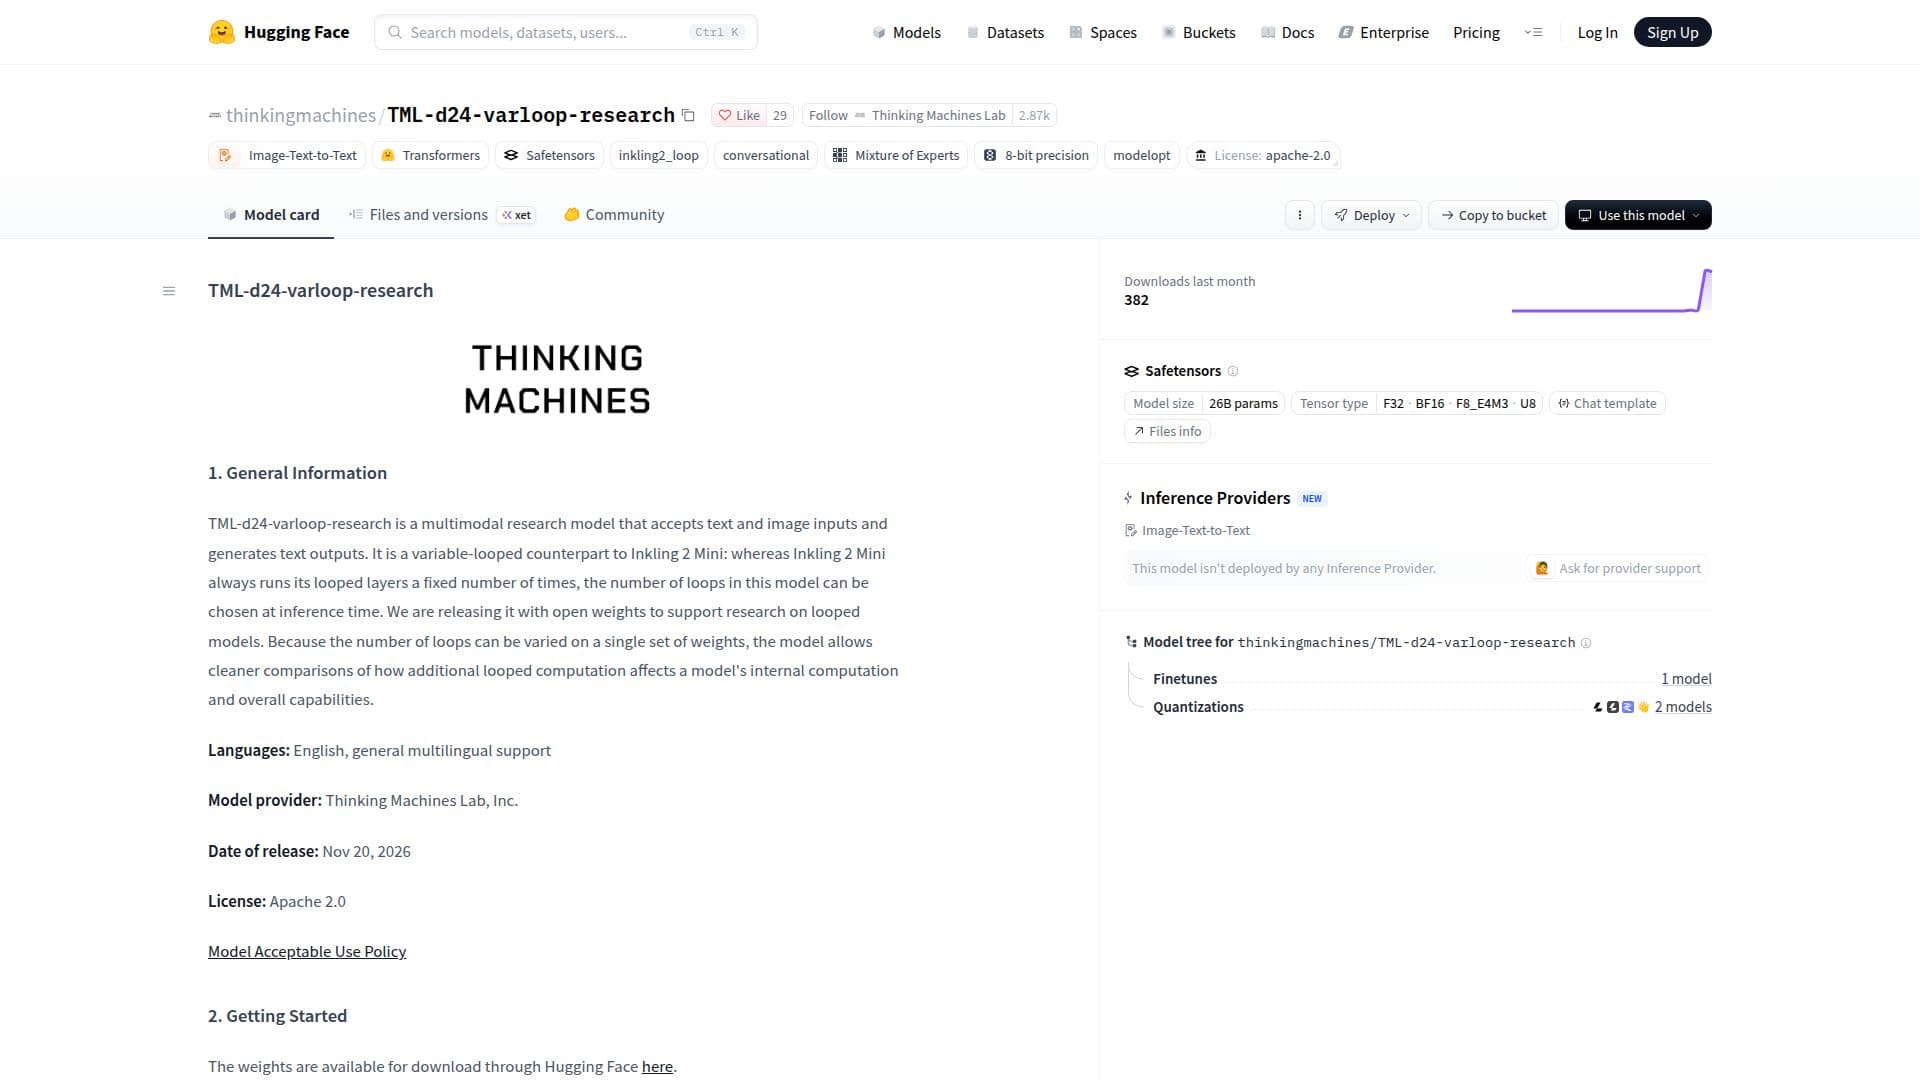
TML-d24-varloop-research is a multimodal research model developed by Thinking Machines Lab, Inc. It accepts both text and image inputs to generate text outputs. This model is a variable-looped counterpart to Inkling 2 Mini, allowing the number of looped layers to be chosen at inference time. It is released with open weights to support research into looped models.

Visit Website
Share
TML-d24-varloop-research screenshot

TML-d24-varloop-research is a multimodal research model developed by Thinking Machines Lab, Inc., designed to process both text and image inputs and produce text outputs. Released on November 20, 2026, under an Apache 2.0 license, this model is a significant contribution to the field of looped models, offering a variable-looped architecture unlike its fixed-loop counterpart, Inkling 2 Mini. Researchers can dynamically adjust the number of loops during inference, enabling cleaner comparisons of how additional computation impacts a model's internal processes and overall capabilities.

Read More

The model is distributed as open weights through Hugging Face, with a single checkpoint size of approximately 20GB. It requires a machine with at least 32GB of GPU or unified memory, compatible with configurations such as NVIDIA DGX Spark, NVIDIA GPUs (e.g., GeForce RTX 5090 or RTX PRO 6000 Blackwell), or Apple silicon Macs. TML-d24-varloop-research supports local inference using various frameworks, including Hugging Face, SGLang, vLLM, TokenSpeed, NVIDIA Dynamo, Unsloth, llama.cpp, Llama App, Ollama, and Exo Labs. It also supports post-training with Miles and SkyRL.

Architecturally, TML-d24-varloop-research is a 24-layer decoder-only transformer with sparse Mixture-of-Experts (MoE) feed-forward layers. The middle 12 layers can run a variable number of times, sharing weights, and were trained with 1 to 5 passes. Each layer routes tokens to 8 of 128 experts, and attention is a hybrid of local and global layers. The model is natively multimodal, encoding images via a vision transformer and processing them jointly with text in a shared hidden space. It features 26.4 billion parameters (3.4 billion active at 1 pass) and supports NVFP4 and MXFP8 numerics. It handles UTF-8 encoded text and pixel-based image inputs (40px to 4096px per dimension) with a context window of up to 1 million tokens.

Training data for TML-d24-varloop-research includes a broad variety of content types from publicly available sources, third-party acquisitions, and internally/synthetically generated data. Data curation involved cleaning, deduplication, and filtering to ensure quality and safety. The model shares its pretraining and first stage of midtraining with Inkling 2 Mini but diverges in later stages, particularly in its variable looping training, where 1 to 5 passes were sampled. While evaluations show varying performance compared to Inkling 2 Mini across benchmarks like Agentic Coding, Vision Interpretation, and Reasoning, it is primarily intended as a research artifact and not recommended for production use due to potential unpredictable behavior at different pass counts and general limitations common to foundation models, such as hallucination and biases from training data.

  • CategoryAI Models & LLMs
  • Pricing ModelOpen source
  • DeploymentRuns locally
  • PlatformsWeb

  • Multimodal Input: Accepts both text and image inputs

  • Text Output: Generates text based on inputs

  • Variable Looping: Number of looped layers can be chosen at inference time

  • Open Weights: Available for download to support research

  • 26.4 Billion Parameters: Large-scale model with 3.4B active parameters at 1 pass

  • Multilingual Support: General support for multiple languages

  • Apache 2.0 License: Open-source licensing for use and modification

  • Local Inference Support: Compatible with Hugging Face, SGLang, vLLM, TokenSpeed, NVIDIA Dynamo, Unsloth, llama.cpp, Llama App, Ollama, Exo Labs

  • Post-training Support: Can be post-trained with Miles and SkyRL

  • Sparse Mixture-of-Experts (MoE): Utilizes MoE feed-forward layers

  • Hybrid Attention: Combines local and global attention layers

  • Native Multimodality: Images encoded via vision transformer and processed jointly with text

  • High Context Window: Supports up to 1 million tokens

  • Mixed Precision Numerics: Supports NVFP4 and MXFP8

  1. Download Weights: Access the model weights through Hugging Face.

  2. Prepare Hardware: Ensure a single machine with at least 32GB of GPU or unified memory is available.

  3. Install Software: Set up required inference frameworks like Hugging Face, SGLang, or vLLM along with their dependencies.

  4. Configure Model: Load the 20GB checkpoint into your chosen framework.

  5. Set Loop Passes: Choose the desired number of looped layers for inference.

  6. Provide Inputs: Feed UTF-8 encoded text and pixel-based images (40px-4096px dimensions) to the model.

  7. Generate Output: Receive text outputs from the model based on the provided inputs.

  • Multimodal Research
  • Looped Model Studies
  • Text Generation from Images
  • Multilingual Text Processing
  • Open-Weight Model Development
  • Local Inference Deployment
  • Model Fine-tuning

TML-d24-varloop-research Reviews

Loading...

Popular AI Tools Like TML-d24-varloop-research

Inkling 2 Mini is a general-purpose multimodal model developed by Thinking Machines Lab, Inc. It accepts both text and image inputs to generate text outputs, supporting English…

AI Models & LLMs

Ranked #39 in LLMs

View Tool

General-purpose multimodal model developed by Thinking Machines Lab, Inc. It accepts both text and image inputs to generate text outputs, supporting English…Inkling 2 Mini is a general-purpose multimodal model developed by Thinking Machines Lab, Inc. It accepts both text and image inputs to generate text outputs, supporting English…

AI Models & LLMs
Ranked #39 in LLMs

Intern Large Models, developed by Shanghai AI Laboratory, offers open-source LLMs and MLLMs. Their suite includes models like InternVL and InternLM-XComposer, alongside a…

AI Models & LLMs

Ranked #49 in LLMs

View Tool

Intern Large Models, developed by Shanghai AI Laboratory, offers open-source LLMs and MLLMs. Their suite includes models like InternVL and InternLM-XComposer, alongside a…

AI Models & LLMs
Ranked #49 in LLMs

Inkling 2 Small is a general-purpose multimodal model designed to accept both text and image inputs, generating text outputs. It supports English and other languages, as well as…

AI Models & LLMs

Ranked #34 in LLMs

View Tool

General-purpose multimodal model designed to accept both text and image inputs, generating text outputs. It supports English and other languages, as well as…Inkling 2 Small is a general-purpose multimodal model designed to accept both text and image inputs, generating text outputs. It supports English and other languages, as well as…

AI Models & LLMs
Ranked #34 in LLMs

975B-parameter multimodal AI model designed for developers. It accepts text, image, and audio inputs, generating text outputs for various applications, including…Inkling is a 975B-parameter multimodal AI model designed for developers. It accepts text, image, and audio inputs, generating text outputs for various applications, including…

FeaturedAI Models & LLMs
See the Top 5 AI Models

SenseNova-Loop-9B-Preview is a multimodal language model designed for long-context and agentic workflows. It processes both text and images to generate text outputs, supporting…

AI Models & LLMs

Ranked #85 in LLMs

View Tool

Multimodal language model designed for long-context and agentic workflows. It processes both text and images to generate text outputs, supporting…SenseNova-Loop-9B-Preview is a multimodal language model designed for long-context and agentic workflows. It processes both text and images to generate text outputs, supporting…

AI Models & LLMs
Ranked #85 in LLMs

Inkling-Small is a versatile multimodal model that processes text, image, and audio inputs to generate text outputs. It supports developers in creating AI applications like…

AI Models & LLMs

Ranked #27 in LLMs

View Tool

Versatile multimodal model that processes text, image, and audio inputs to generate text outputs. It supports developers in creating AI applications like…Inkling-Small is a versatile multimodal model that processes text, image, and audio inputs to generate text outputs. It supports developers in creating AI applications like…

AI Models & LLMs
Ranked #27 in LLMs

Llama-4-Scout-17B-16E-Instruct is a multimodal AI model designed by Meta. It leverages a mixture-of-experts architecture to provide advanced text and image understanding…

AI Models & LLMs
View Tool

Multimodal AI model designed by Meta. It leverages a mixture-of-experts architecture to provide advanced text and image understanding…Llama-4-Scout-17B-16E-Instruct is a multimodal AI model designed by Meta. It leverages a mixture-of-experts architecture to provide advanced text and image understanding…

AI Models & LLMs
See the Top 5 AI Models

BigModel Platform offers a comprehensive suite of AI models, including LLMs and multimodal visual models, designed to integrate AI technology with industry applications. It…

AI Models & LLMs

Ranked #25 in AI Models & LLMs

View Tool

Offers a comprehensive suite of AI models, including LLMs and multimodal visual models, designed to integrate AI technology with industry applications. It…BigModel Platform offers a comprehensive suite of AI models, including LLMs and multimodal visual models, designed to integrate AI technology with industry applications. It…

AI Models & LLMs
Ranked #25 in AI Models & LLMs
1 of 8