Description
SenseNova-Loop-9B-Preview is an advanced multimodal language model engineered to handle complex, long-context scenarios and agentic workflows. Developed by SenseNova, this model is capable of accepting both text and image inputs, subsequently generating text outputs. Its primary applications span areas such as comprehensive document understanding, sophisticated coding tasks, and seamless interaction with various external tools.
Read More
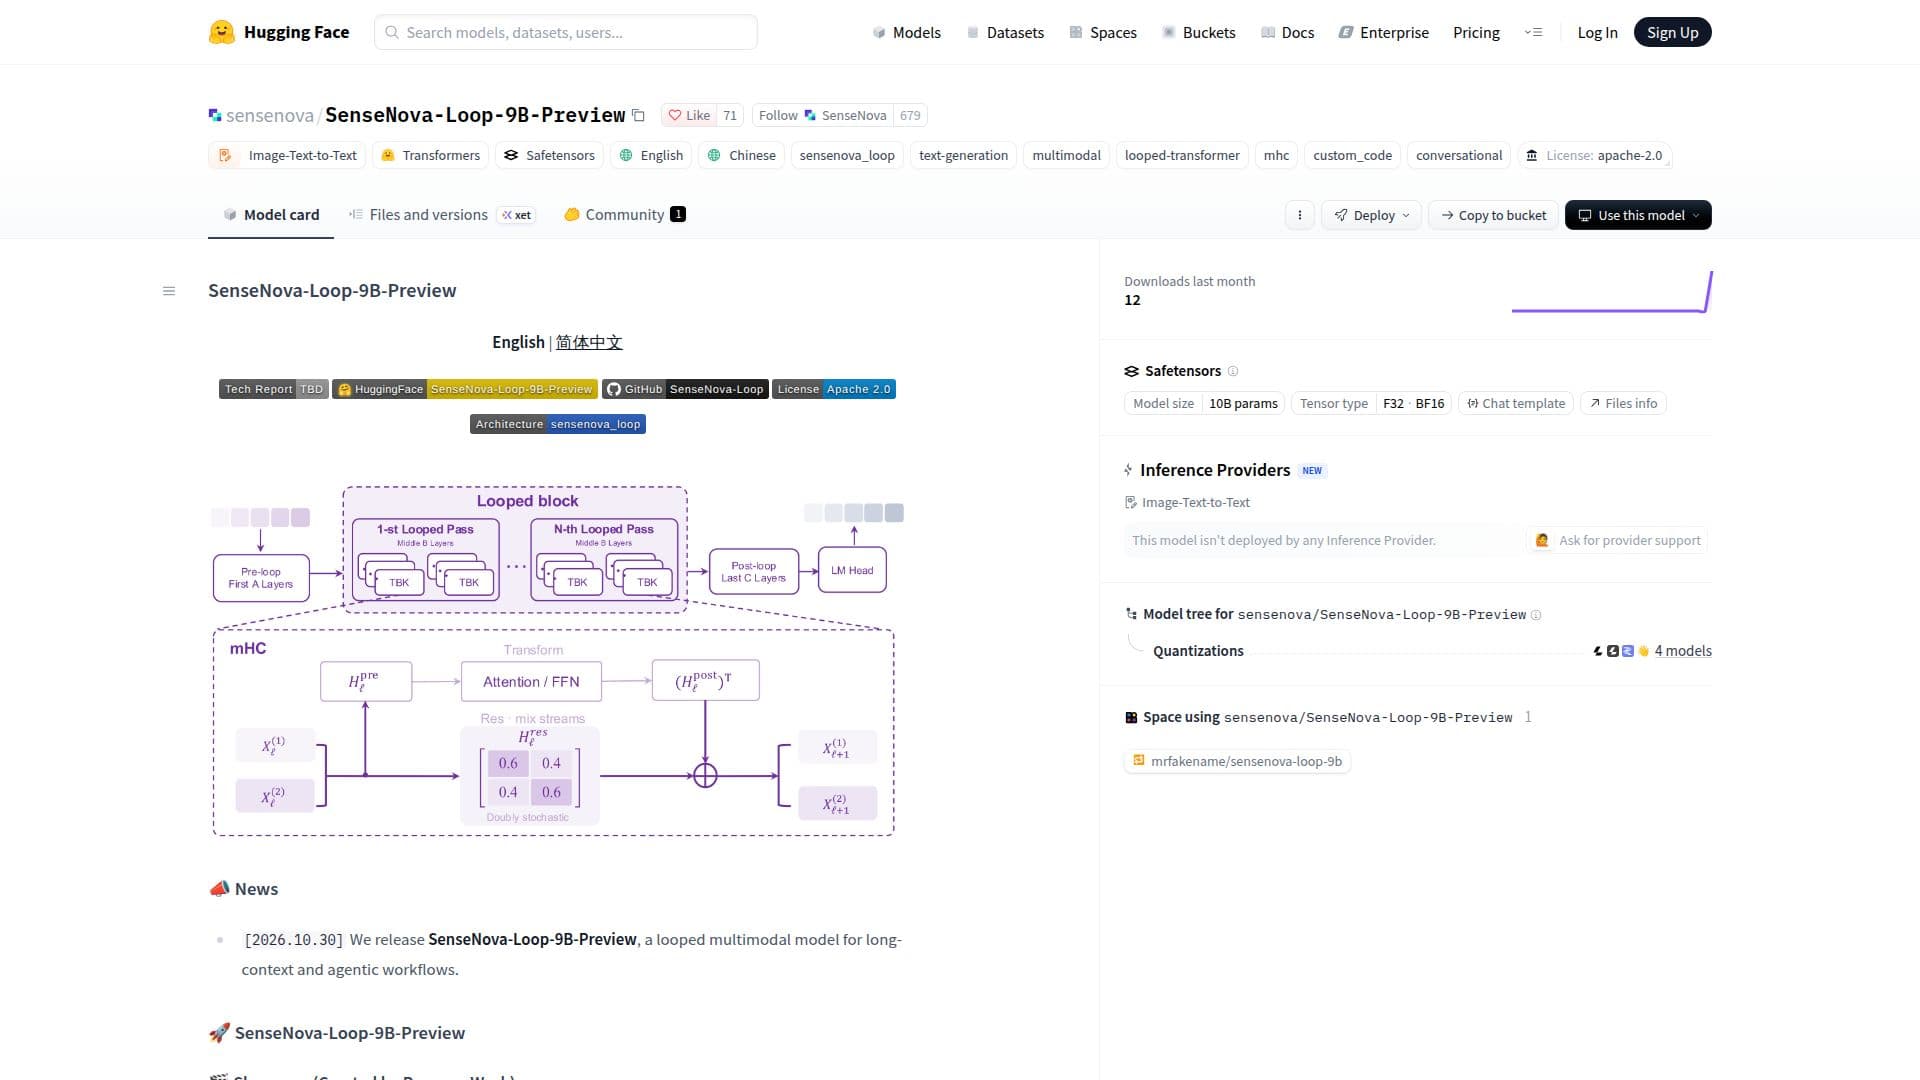
The core of SenseNova-Loop-9B-Preview's architecture lies in its innovative combination of a looped decoder and two-stream manifold-constrained hyper-connections (mHC). This design allows a contiguous block of decoder layers to be executed twice using shared weights, significantly deepening the execution path without duplicating parameters. Learned mappings within the mHC system efficiently manage information flow between two residual streams in the looped section, enhancing the model's ability to process and synthesize information.
Training recipes for the model incorporate long sequences, diverse multimodal inputs, and supervised task trajectories, with a maximum training sequence length reaching 262,144 tokens. This extensive training enables robust performance across a wide range of complex tasks. For optimal operation, users are advised to utilize the documented deployment environment and configuration parameters.
Key architectural highlights include a shared looped block where 24 decoder layers are applied twice, resulting in 56 decoder-layer executions from just 32 distinct layers. The two-stream mHC facilitates intelligent routing and combination of information across the residual streams. Furthermore, the decoder employs a hybrid attention mechanism, interleaving linear and full attention in a repeating four-layer pattern, which is preserved across loop passes. The model also supports MTP for accelerated inference, with Dspark and Dflash2 currently under development to further enhance speed.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsWeb
SenseNova-Loop-9B-Preview Highlights
Multimodal Input: Accepts both text and images
Text Generation: Produces text outputs
Looped Decoder Architecture: Executes decoder layers twice with shared weights
Two-Stream Manifold-Constrained Hyper-Connections (mHC): Manages information flow between residual streams
Long-Context Processing: Supports training sequence lengths up to 262,144 tokens
Agentic Workflow Support: Designed for interaction with external tools
Hybrid Attention: Interleaves linear and full attention layers
Parameter Efficiency: Achieves 56 decoder-layer executions from 32 distinct layers
Document Understanding: Capable of processing complex documents
Coding Applications: Supports code-related tasks
MTP Inference Acceleration: Available for faster processing
Fine-tuning Support: Provides documented training recipes for customization
Apache License 2.0: Open-source licensing for usage and modification
Hugging Face Integration: Available for download and deployment on Hugging Face
Getting Started with SenseNova-Loop-9B-Preview
Access Model Page: Navigate to the SenseNova-Loop-9B-Preview page on Hugging Face.
Install Dependencies: Install PyTorch compatible with your CUDA environment, then install Transformers 5.18.0 and PyTorch 2.11.0.
Load Model: Use the Transformers library to load the model and its custom implementation from the Hugging Face repository or a local directory.
Configure Inference: Set `model_id` to the repository ID or local path and configure parameters like `enable_thinking` and `device`.
Generate Text: Run the provided Python example to perform text generation, specifying the number of new tokens.
Fine-tune Model: Use the documented training commands with your SFT dataset on a single node with 8 GPUs for fine-tuning.
Deploy Model: Utilize deployment options like LightLLM or SGLang by replacing the local model path in the provided examples.
SenseNova-Loop-9B-Preview's Use Cases
- Long-Context Document Understanding
- Agentic Workflow Automation
- Multimodal Content Generation
- Advanced Coding Assistance
- PPT Design Automation
- Motion Design Text Generation
- Data Analysis Reporting
- Multimodal Research and Development