Description
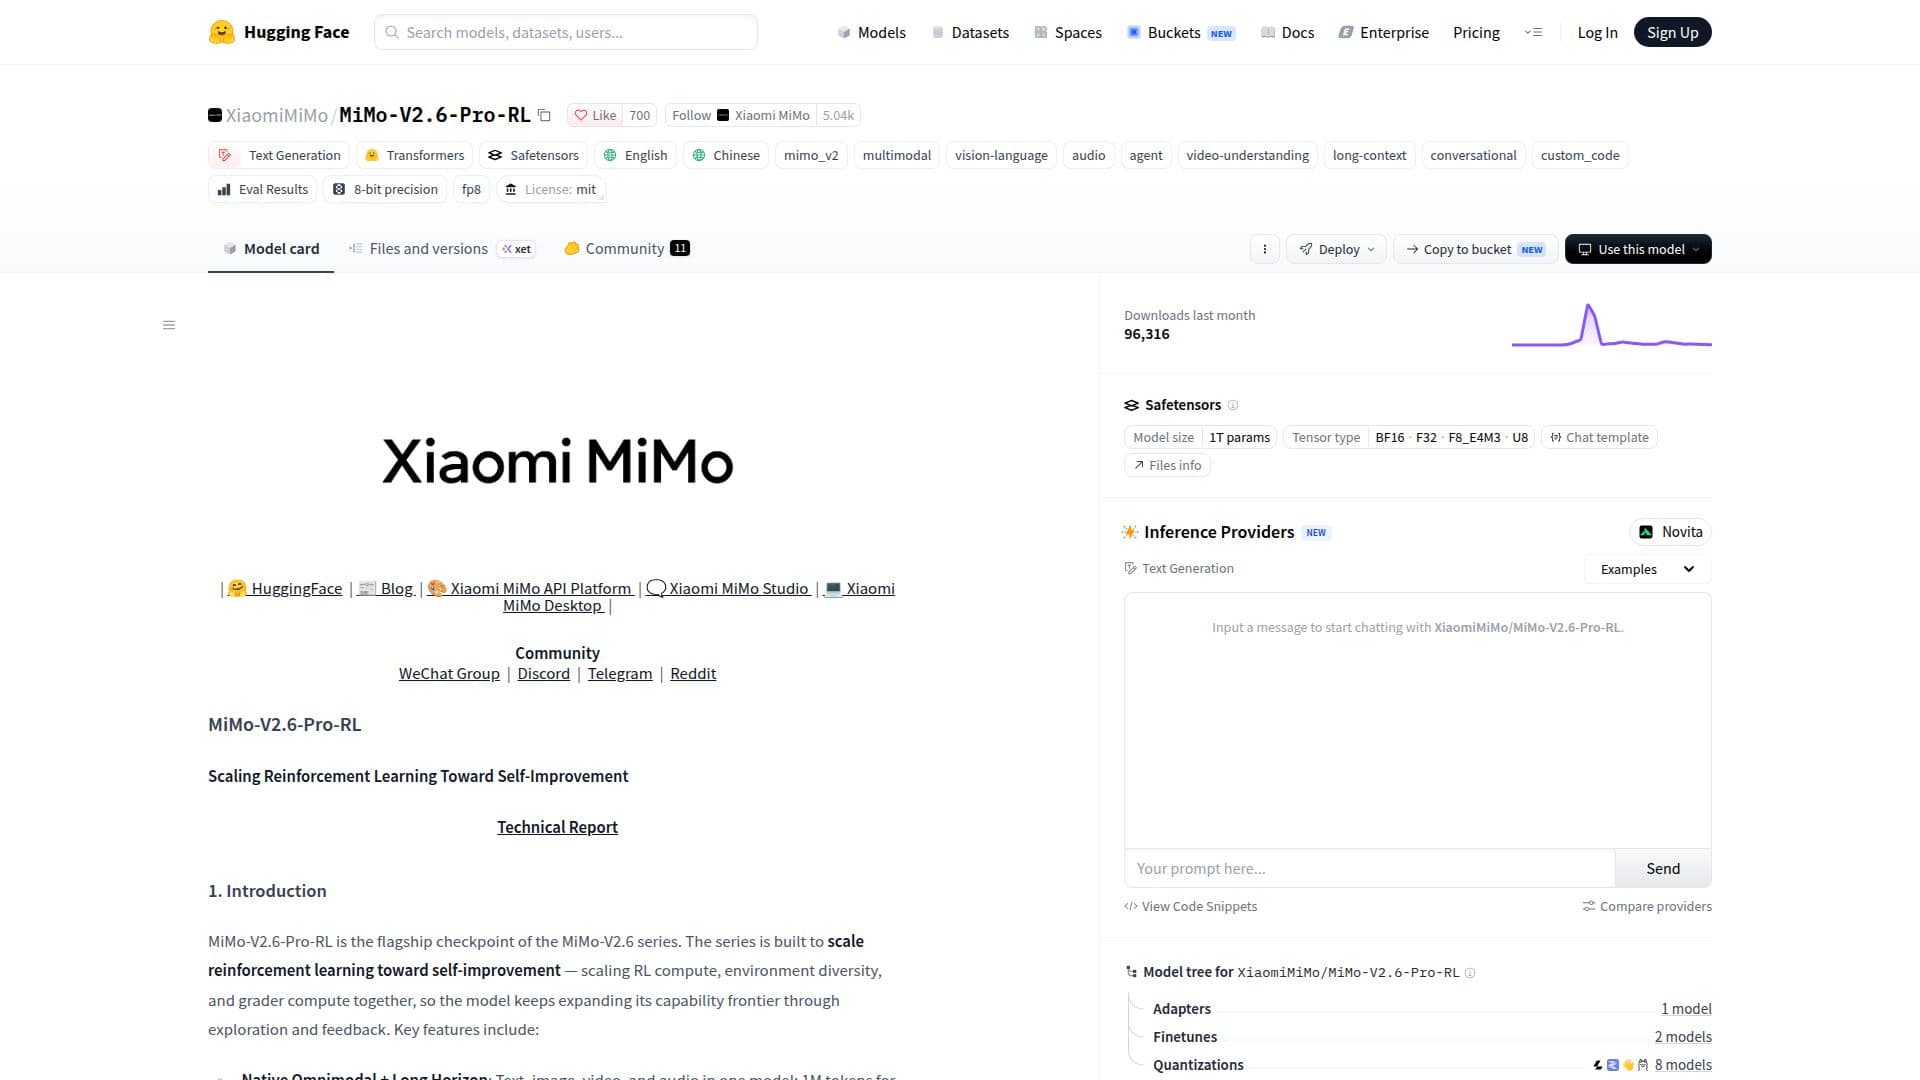
MiMo-V2.6-Pro-RL is the leading model in the MiMo series, developed to advance reinforcement learning towards self-improvement. This model is built to scale RL compute, environment diversity, and grader compute together, allowing it to expand its capabilities through exploration and feedback. Key features include a native omnimodal approach, integrating text, image, video, and audio into one model, and a long context length of 1 million tokens for handling extensive repositories and multi-session agent runs.
Read More
The model employs a unique 'You Only RL Once' strategy, mixing tasks and harnesses in a single batch to reinforce capabilities and transfer strategies across domains. It utilizes fully asynchronous Group Relative Policy Optimization (GRPO) on large batches, processing billions of tokens per update. The Groupwise Agentic Grading system enhances the self-improvement loop by ranking solutions and steering towards efficient paths.
MiMo-V2.6-Pro-RL also features Multi-Prefix Multi-Teacher On-Policy Distillation (MOPD2), which combines autonomous student rollouts with prefix-conditioned rollouts, extending capabilities to complex tasks. The model's architecture includes a Sparse Mixture of Experts with 1.02 trillion total parameters and a vision encoder with 681 million parameters.
This model is available for deployment through various platforms, including AI Studio, MiMo Code, and Xiaomi MiMo Desktop. It supports Docker deployment for optimal performance and is accessible via the Xiaomi MiMo Open Platform API and OpenRouter.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsWeb
MiMo-V2.6-Pro-RL Highlights
Native Omnimodal Integration
1M Token Context Length
You Only RL Once Strategy
Group Relative Policy Optimization
Groupwise Agentic Grading
Multi-Prefix Multi-Teacher Distillation
Sparse Mixture of Experts Architecture
Available on Multiple Platforms
Getting Started with MiMo-V2.6-Pro-RL
Access model page: Visit the official Hugging Face page for MiMo-V2.6-Pro-RL.
Authenticate: Ensure you have the necessary credentials to access the model.
Configure: Set up the model parameters according to your requirements.
Send prompts: Input your data to interact with the model and receive outputs.
MiMo-V2.6-Pro-RL's Use Cases
- Multimodal Processing
- Reinforcement Learning
- Large-Scale Data Handling
- Cross-Domain Strategy Transfer
- Advanced Grading Systems