Description
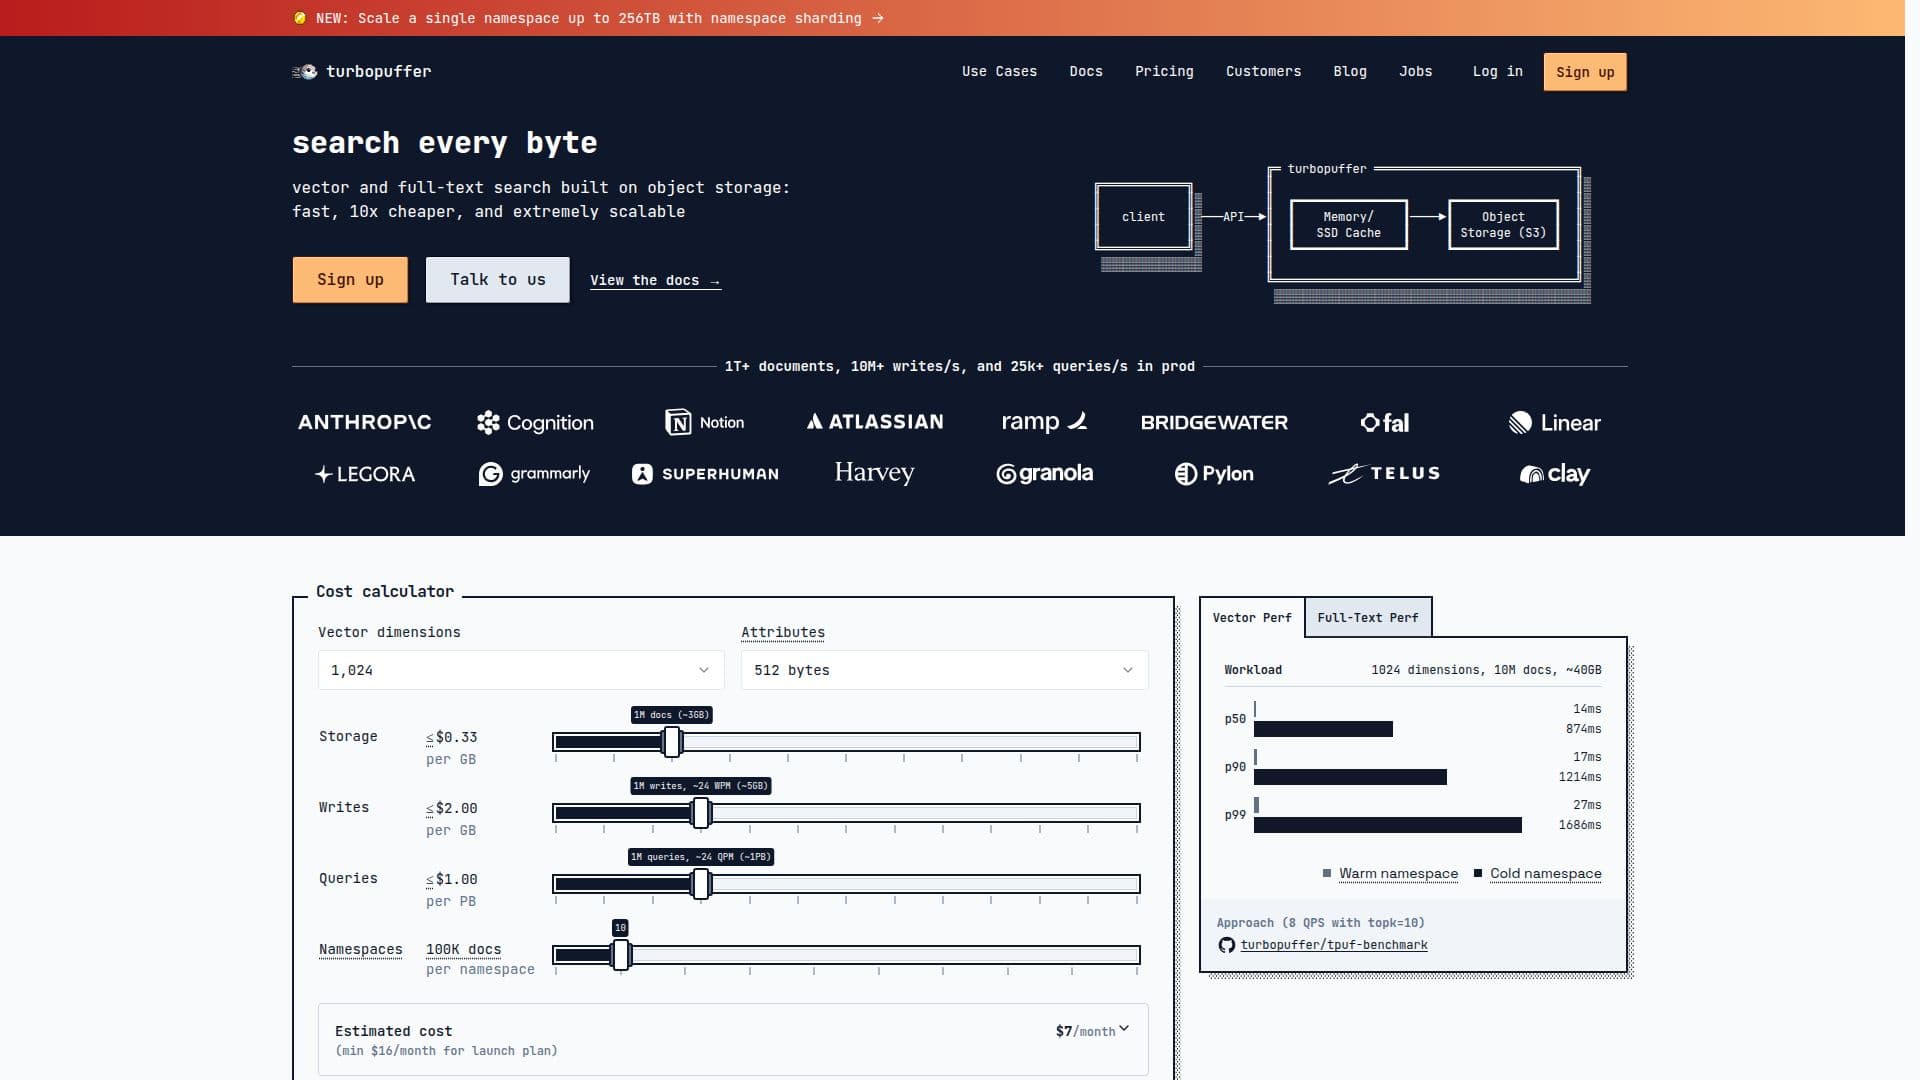
Turbopuffer is designed to make every byte searchable, providing a fast and scalable search engine built on object storage. It supports vector and full-text search, allowing users to efficiently search through vast amounts of data. With the ability to handle over 1 trillion documents, 10 million writes per second, and 25,000 queries per second, turbopuffer is engineered for high performance and reliability.
Read More
The architecture of turbopuffer leverages object storage as the sole source of truth, which allows for significant cost savings and scalability. By separating compute and storage, turbopuffer minimizes operational complexity while ensuring that search indexes can scale automatically to meet demand. This unique approach enables users to create isolated namespaces for data, ensuring strict data isolation and security, which is particularly beneficial for industries like healthcare and finance.
Turbopuffer is particularly suited for organizations that require fast, reliable search capabilities across large datasets. Its object-storage-native design allows for efficient indexing and retrieval, making it an excellent choice for applications that need to search more than 10 million documents. The platform also supports a unified API for various search types, including dense and sparse vector search, full-text search, and regex search, providing flexibility for developers.
With a focus on performance, turbopuffer achieves high query speeds and low latency, making it a strong contender for businesses looking to enhance their data retrieval capabilities. The pricing model is usage-based, making it accessible for organizations of all sizes, and it is designed to scale seamlessly as data needs grow. Overall, turbopuffer stands out as a powerful tool for connecting AI with large amounts of fresh data, enabling smarter and more efficient search solutions.
- CategoryVector Databases & Retrieval
- Pricing ModelUsage-based
- DeploymentCloud
- PlatformsWeb
turbopuffer's Core Features
Vector search with >90% recall
Full-text search capabilities
Regex search with fast trigram indexes
Multi-tenant or single-tenant deployments
Encryption options with customer-controlled keys
Unlimited namespaces for data isolation
High write throughput of 10M+ writes/s
Fast query handling with 25k+ queries/s
How to use turbopuffer?
Configure: Set up your turbopuffer environment and connect to your object storage.
Index: Write your documents to turbopuffer to create searchable indexes.
Query: Use the unified API to perform searches across your indexed data.
Optimize: Adjust settings for query performance and data retrieval as needed.
turbopuffer's Use Cases
- Document Search
- Recommendation Systems
- Data Retrieval for AI
- Multi-Tenant Applications
- Web Search