ToolPotion
AI Advisor
Submit a Tool (Free)

oMLX

AI AppsMLOps & Model Deployment#101Open source · macOS 15+

oMLX is a native macOS inference server optimized for Apple Silicon. It significantly reduces agent TTFT from 30-90 seconds to under 5 seconds using paged SSD KV caching. Compatible with OpenAI and Anthropic APIs, it enhances local AI performance on Mac.

Visit Website
Share
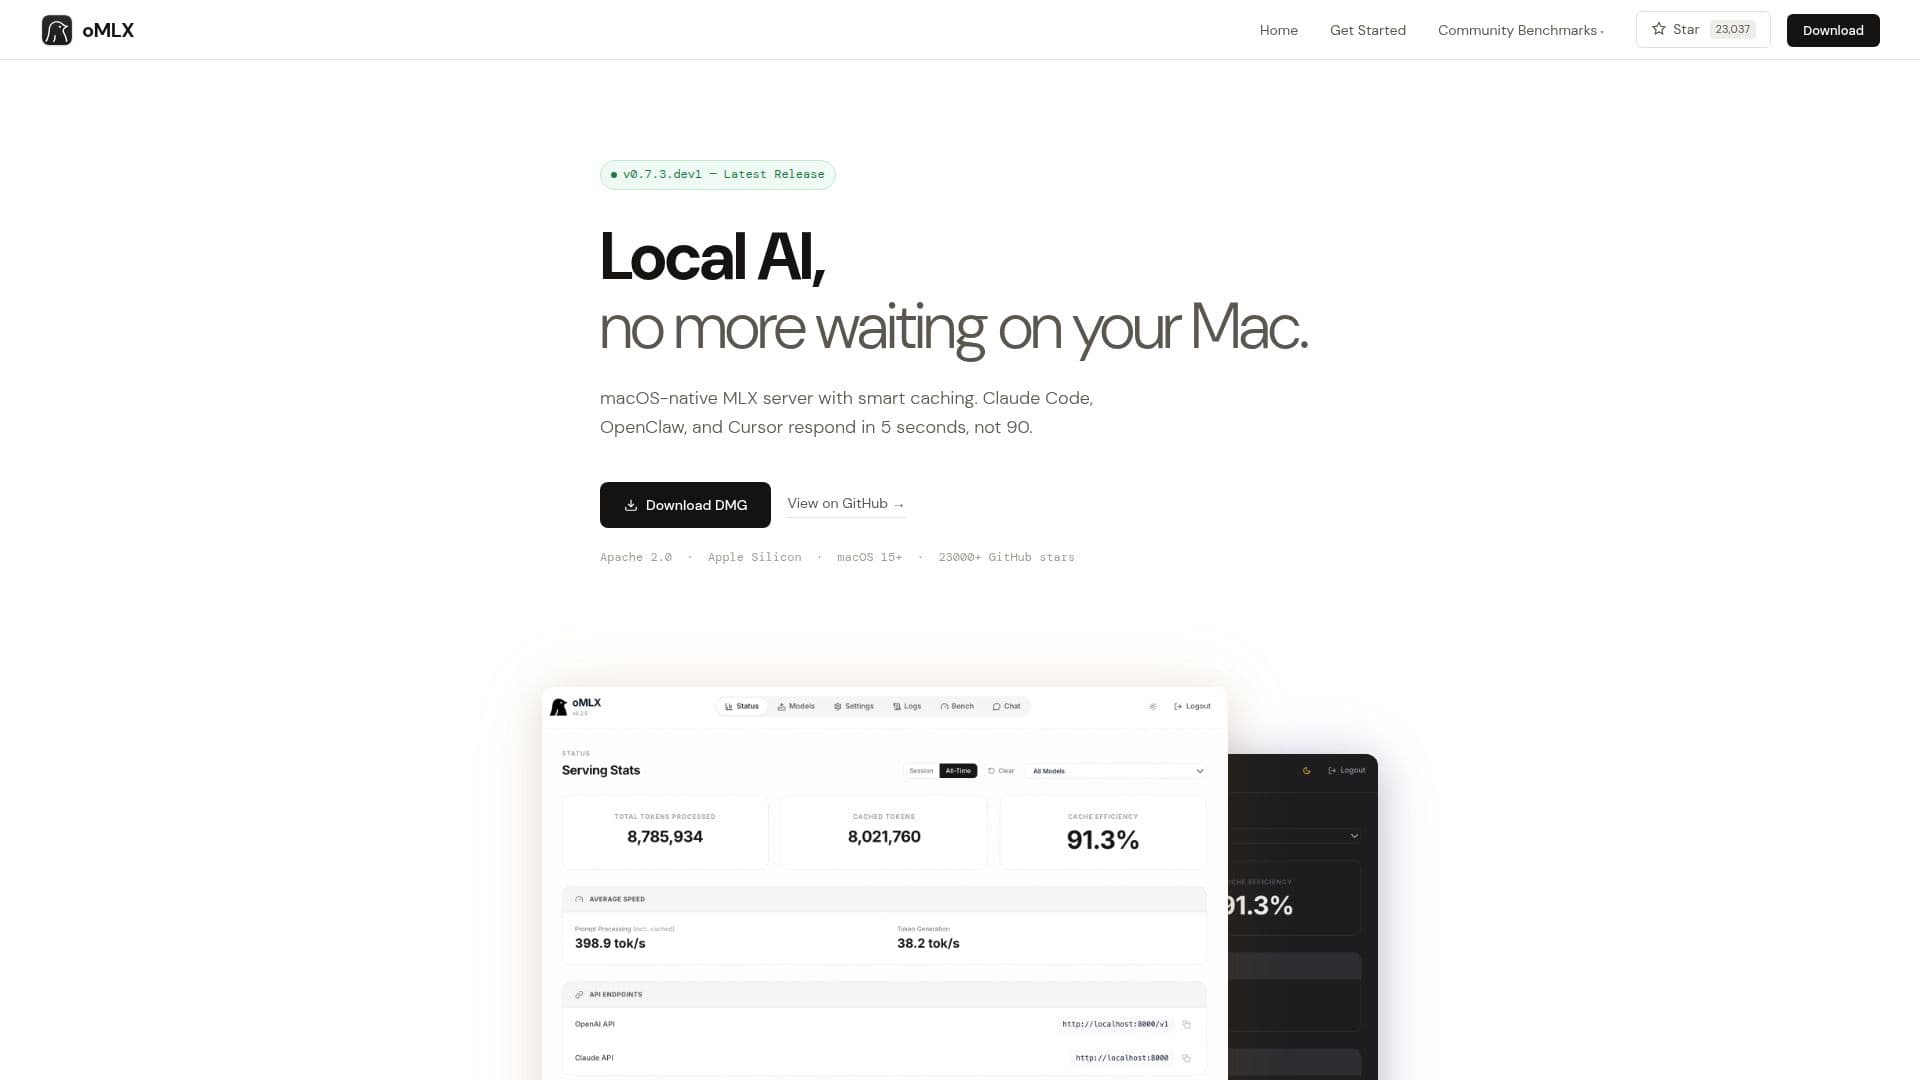
oMLX screenshot
oMLX screenshot

oMLX is a cutting-edge inference server designed specifically for macOS, leveraging the power of Apple Silicon. Built on the MLX framework, it offers a native solution for running large language models (LLMs) locally on Mac computers. One of its standout features is the paged SSD KV caching, which drastically reduces the time to first token (TTFT) from a typical 30-90 seconds to under 5 seconds. This improvement is particularly beneficial for coding agents that frequently invalidate the cache, as oMLX ensures that every cache block is persisted to SSD, allowing for rapid restoration from disk.

Read More

The server is compatible with popular APIs such as OpenAI and Anthropic, making it a versatile tool for developers working with these platforms. It supports continuous batching and provides a drop-in API for models like Claude Code, OpenClaw, and Cursor, ensuring that responses are delivered in mere seconds. The performance benchmarks conducted on an M3 Ultra with 512GB RAM demonstrate impressive throughput and memory efficiency across various contexts and batch sizes.

oMLX is designed for developers and AI enthusiasts who require a reliable and fast local AI solution on their Macs. It eliminates the need for cloud-based inference, reducing latency and dependency on external servers. The tool is open-source under the Apache 2.0 license, with a strong community presence, as evidenced by its 23,000+ GitHub stars. Users can easily get started by downloading the DMG or installing from source, with compatibility for standard Hugging Face caches and LM Studio folders.

Overall, oMLX offers a robust and efficient solution for running AI models locally on macOS, providing significant speed improvements and seamless integration with existing AI workflows.

  • CategoryMLOps & Model Deployment
  • Pricing ModelOpen source
  • DeploymentLocal
  • PlatformsmacOS 15+

  • Native macOS inference server

  • Paged SSD KV caching

  • OpenAI & Anthropic API compatibility

  • Continuous batching support

  • Drop-in API for Claude Code, OpenClaw, and Cursor

  • Rapid cache restoration from SSD

  • Open-source under Apache 2.0

  • 23,000+ GitHub stars

  1. Download: Get the DMG or source

  2. Install: Follow installation instructions

  3. Configure: Set up with Hugging Face cache

  4. Use: Run models with reduced TTFT

  5. Optimize: Leverage continuous batching

  • Local AI Development
  • API Integration
  • Coding Agents
  • Batch Processing
  • Open-Source Contribution

From oMLX

oMLX Reviews

Loading...

Popular AI Tools Like oMLX

omlx

AI GitHub Repos

omlx is an LLM inference server designed for Apple Silicon, featuring continuous batching and SSD caching. It is managed directly from the macOS menu bar, providing an efficient…

MLOps & Model Deployment

Ranked #185 in Coding & Development

View Tool

AI GitHub Repos

LLM inference server designed for Apple Silicon, featuring continuous batching and SSD caching. It is managed directly from the macOS menu bar, providing an efficient…omlx is an LLM inference server designed for Apple Silicon, featuring continuous batching and SSD caching. It is managed directly from the macOS menu bar, providing an efficient…

MLOps & Model Deployment
Ranked #185 in Coding & Development

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
View Tool

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
See the Top 250 AI Apps

RunInfra

AI Apps

RunInfra is a hosted API gateway for open-source AI models, giving developers one API key compatible with the OpenAI and Anthropic SDKs. It serves models like Nemotron, Qwen, and…

MLOps & Model Deployment

Ranked #98 in MLOps & Model Deployment

View Tool

AI Apps

Hosted API gateway for open-source AI models, giving developers one API key compatible with the OpenAI and Anthropic SDKs. It serves models like Nemotron, Qwen, and…RunInfra is a hosted API gateway for open-source AI models, giving developers one API key compatible with the OpenAI and Anthropic SDKs. It serves models like Nemotron, Qwen, and…

MLOps & Model Deployment
Ranked #98 in MLOps & Model Deployment

vLLM

AI Apps

vLLM is a high-throughput and memory-efficient inference and serving engine for Large Language Models (LLMs). It enables faster deployment of AI models with state-of-the-art…

MLOps & Model Deployment
View Tool

AI Apps

High-throughput and memory-efficient inference and serving engine for Large Language Models (LLMs). It enables faster deployment of AI models with state-of-the-art…vLLM is a high-throughput and memory-efficient inference and serving engine for Large Language Models (LLMs). It enables faster deployment of AI models with state-of-the-art…

MLOps & Model Deployment
See the Top 250 AI Apps

Inference.net provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…

MLOps & Model Deployment

Ranked #78 for Fine-tuning AI models

View Tool

Provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…Inference.net provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…

MLOps & Model Deployment
Ranked #78 for Fine-tuning AI models

Runware

AI Apps

Runware is a generative AI inference platform that provides one unified API for image, video, audio, 3D, LLM, and vision models. It offers 400K+ models, managed infrastructure,…

MLOps & Model Deployment
View Tool

AI Apps

Generative AI inference platform that provides one unified API for image, video, audio, 3D, LLM, and vision models. It offers 400K+ models, managed infrastructure,…Runware is a generative AI inference platform that provides one unified API for image, video, audio, 3D, LLM, and vision models. It offers 400K+ models, managed infrastructure,…

MLOps & Model Deployment
See the Top 250 AI Apps

BLACKBOX AI is an inference platform that routes requests across 300+ open and closed language models through one encrypted, OpenAI-compatible API, plus dedicated single-tenant…

MLOps & Model Deployment

Ranked #125 in AI Apps

View Tool

Inference platform that routes requests across 300+ open and closed language models through one encrypted, OpenAI-compatible API, plus dedicated single-tenant…BLACKBOX AI is an inference platform that routes requests across 300+ open and closed language models through one encrypted, OpenAI-compatible API, plus dedicated single-tenant…

MLOps & Model Deployment
Ranked #125 in AI Apps

Chutes is a serverless AI compute platform that allows users to deploy, run, and scale any AI model in seconds. With a focus on open-source models, it provides a flexible and…

MLOps & Model Deployment
View Tool

Serverless AI compute platform that allows users to deploy, run, and scale any AI model in seconds. With a focus on open-source models, it provides a flexible and…Chutes is a serverless AI compute platform that allows users to deploy, run, and scale any AI model in seconds. With a focus on open-source models, it provides a flexible and…

MLOps & Model Deployment
See the Top 250 AI Apps
1 of 8