Description
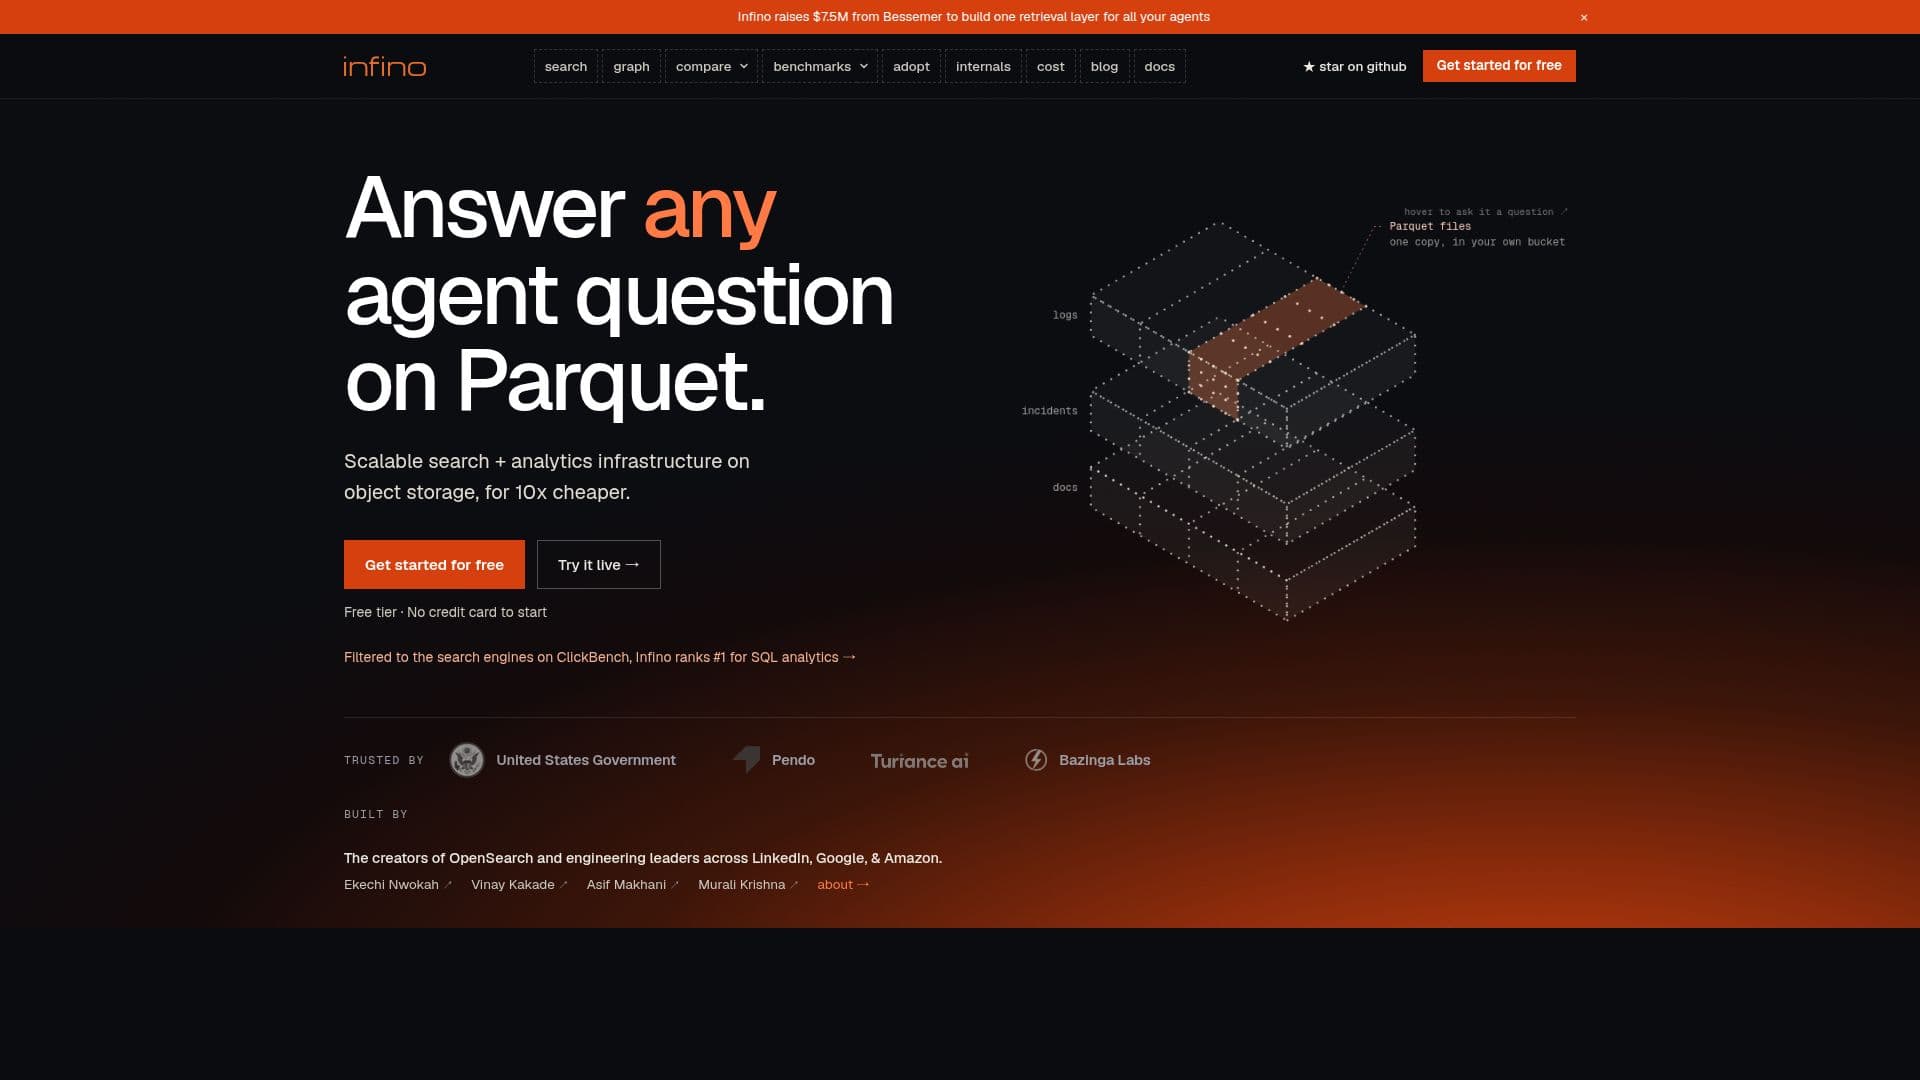
Infino is an open-source retrieval engine that provides full-text, vector, and SQL search capabilities natively over Apache Parquet files stored in object storage. This architecture allows for scalable search and analytics infrastructure at a significantly lower cost, often cited as 10x cheaper than traditional solutions.
Read More
The core of Infino's functionality lies in its ability to embed various search functions directly into SQL queries. This means that AI agents can formulate complex questions that might typically require multiple steps across different databases (e.g., keyword search, semantic search, graph search, and SQL aggregations) into a single, unified SQL statement. Infino handles the underlying complexity, executing these combined search modes to deliver highly accurate retrieval results.
The engine supports multiple search types, including BM25 for full-text search, HNSW and OPANN + Sq16 for vector indexing, and hybrid search that combines these methods. It also integrates graph search capabilities, allowing for the identification of linked records based on shared keys. This multi-modal approach enhances retrieval accuracy and efficiency.
Infino is built for performance and cost-efficiency, utilizing less memory and compute resources by keeping data on cheap object storage while maintaining high query speeds. It offers flexible deployment options: users can run the open-source core engine themselves on their object storage (S3, GCS, Azure Blob, or local disk), or opt for Infino Cloud, a managed multi-tenant serverless service. An Enterprise option provides single-tenant deployments with additional features like multi-node queries and customer-managed keys.
For existing Parquet data, Infino can build retrieval indexes through a process called hydration, allowing current tools like DuckDB, pandas, and Spark to continue reading the columnar data while Infino provides indexed access. This makes it a complementary solution for existing data platforms, capable of replacing dedicated retrieval paths like Elasticsearch or vector databases for specific workloads, while integrating seamlessly with data warehouses and lakehouses.
- CategoryVector Databases & Retrieval
- Pricing ModelFreemium
- DeploymentCloud, On-premise, Self-hosted
- PlatformsWeb
Infino's Core Features
Open-source retrieval engine
Full-text search (BM25)
Vector search (HNSW, OPANN + Sq16)
Hybrid search combining multiple modes
SQL query support (Apache DataFusion)
Native operation on Apache Parquet files
Object storage compatibility (S3, GCS, Azure Blob)
Graph search capabilities
Embeds functions in SQL for complex queries
Cost-effective and scalable architecture
Low-latency query performance
On-premise and hosted cloud deployment options
SOC 2 Type II compliant (Infino Cloud)
TLS in transit and AES-256 at rest encryption
Data hydration for existing Parquet files
How to use Infino?
Install Infino: Use `pip install infino` or `npm install @infino-ai/infino` to set up the open-source core engine.
Store Data: Keep your data in Apache Parquet format within your own object storage bucket (S3, GCS, Azure Blob) or local disk.
Ingest Data: Append new JSON, Arrow, columns, or vectors through Infino, or hydrate existing Parquet files to build retrieval indexes.
Formulate Queries: Express complex questions using a single SQL statement, leveraging Infino's embedded functions for keyword, semantic, and graph search.
Execute Searches: Run queries to perform full-text, vector, or hybrid searches, retrieving ranked results directly from your Parquet data.
Analyze Results: Utilize the returned data for agentic applications or integrate with other Parquet readers like DuckDB, Spark, or pandas for further analysis.
Infino's Use Cases
- Agentic Question Answering
- Cost-Effective Data Retrieval
- Unified Search and Analytics
- Log Analysis and Incident Response
- Data Lakehouse Integration
- Semantic Search on Unstructured Data
- Real-time Data Exploration