Description
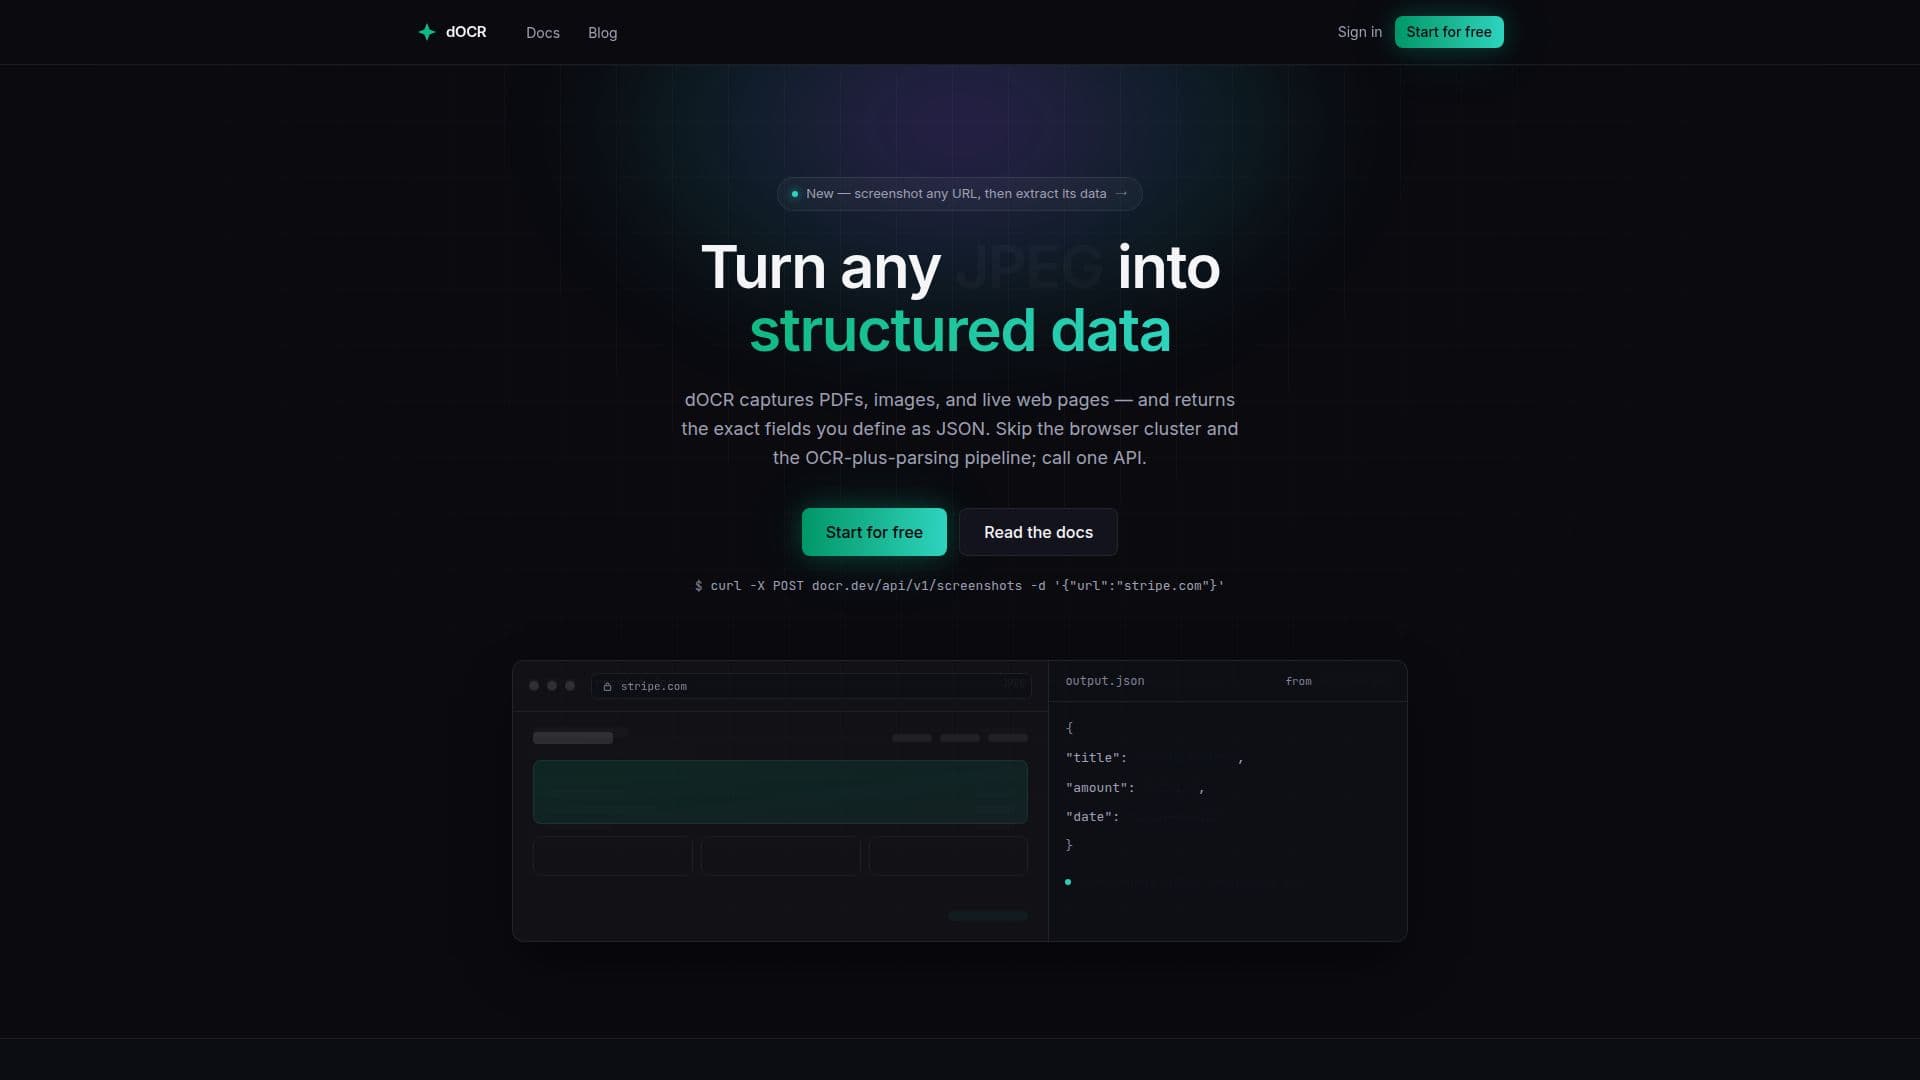
dOCR provides a robust document data-extraction API designed to transform various document types and live web pages into structured JSON data. The service handles the complexities of rendering pages and parsing documents, delivering clean screenshots and validated JSON fields. This approach allows users to bypass traditional browser clusters and OCR-plus-parsing pipelines, simplifying data acquisition through a single API call.
Read More
The platform supports a wide range of inputs, including PDFs, images, and live URLs. Users can define the exact fields they need, and dOCR will locate, validate, and score each one, ensuring consistent data output without requiring any parsing code. This capability is particularly useful for processing business documents like invoices, receipts, forms, and IDs, as well as for extracting data from any live web page.
Key functionalities include the ability to screenshot any URL, rendering pages to various formats such as PNG, JPEG, WebP, or PDF, with options for full-page capture and different device viewports. dOCR also automatically blocks ads and cookie banners, further streamlining the data capture process. The service is designed for speed, with most documents processed within a couple of seconds, including multi-page PDFs, making it suitable for real-time requests rather than batch jobs.
Users can define custom document types, specifying the desired fields once to ensure every extraction returns data in that exact shape. The platform offers both a dashboard for testing and browsing extraction history, and an API for backend automation. This flexibility allows developers to integrate dOCR into their workflows with minimal infrastructure overhead.
Transparency is a core aspect of dOCR, providing detailed logs for every extraction. Users can trace each field from upload through OCR, field extraction, and schema validation, complete with confidence scores. This visibility helps identify and address any discrepancies, ensuring data accuracy and reliability. The service is accessible via a single API key, supporting both screenshot and structured data extraction, and offers a free tier to get started.
- CategoryWeb Scraping & Data Extraction
- Pricing ModelFreemium
- DeploymentCloud
- PlatformsWeb
dOCR's Core Features
Document data-extraction API
Converts documents and websites to structured JSON
Supports invoices, receipts, forms, and IDs
Captures PDFs, images, and live web pages
Returns user-defined fields as JSON
Provides clean screenshots of web pages
Validates and scores extracted JSON fields
Renders pages to PNG, JPEG, WebP, or PDF
Blocks ads and cookie banners during web capture
Fast processing, typically within seconds
Supports multi-page PDF processing
Allows definition of custom document types
Offers dashboard for testing and history
Provides detailed extraction logs with confidence scores
Single API key for all functionalities
How to use dOCR?
Create Account: Sign up on docr.dev to get an API key.
Define Document Type: Specify the JSON fields you want to extract for your document type.
Send Document or URL: Use the API to send a document (PDF, image, DOCX) or a live URL.
Receive Structured Data: Get back the defined fields as validated JSON with confidence scores.
Review Extractions: Monitor extraction history and logs in the dashboard for transparency.
dOCR's Use Cases
- Invoice Processing Automation
- Receipt Data Capture
- Form Data Extraction
- Web Page Data Scraping
- Document Archiving with Metadata
- Real-time Data Processing
- Automated Reporting
- Compliance and Audit Trails