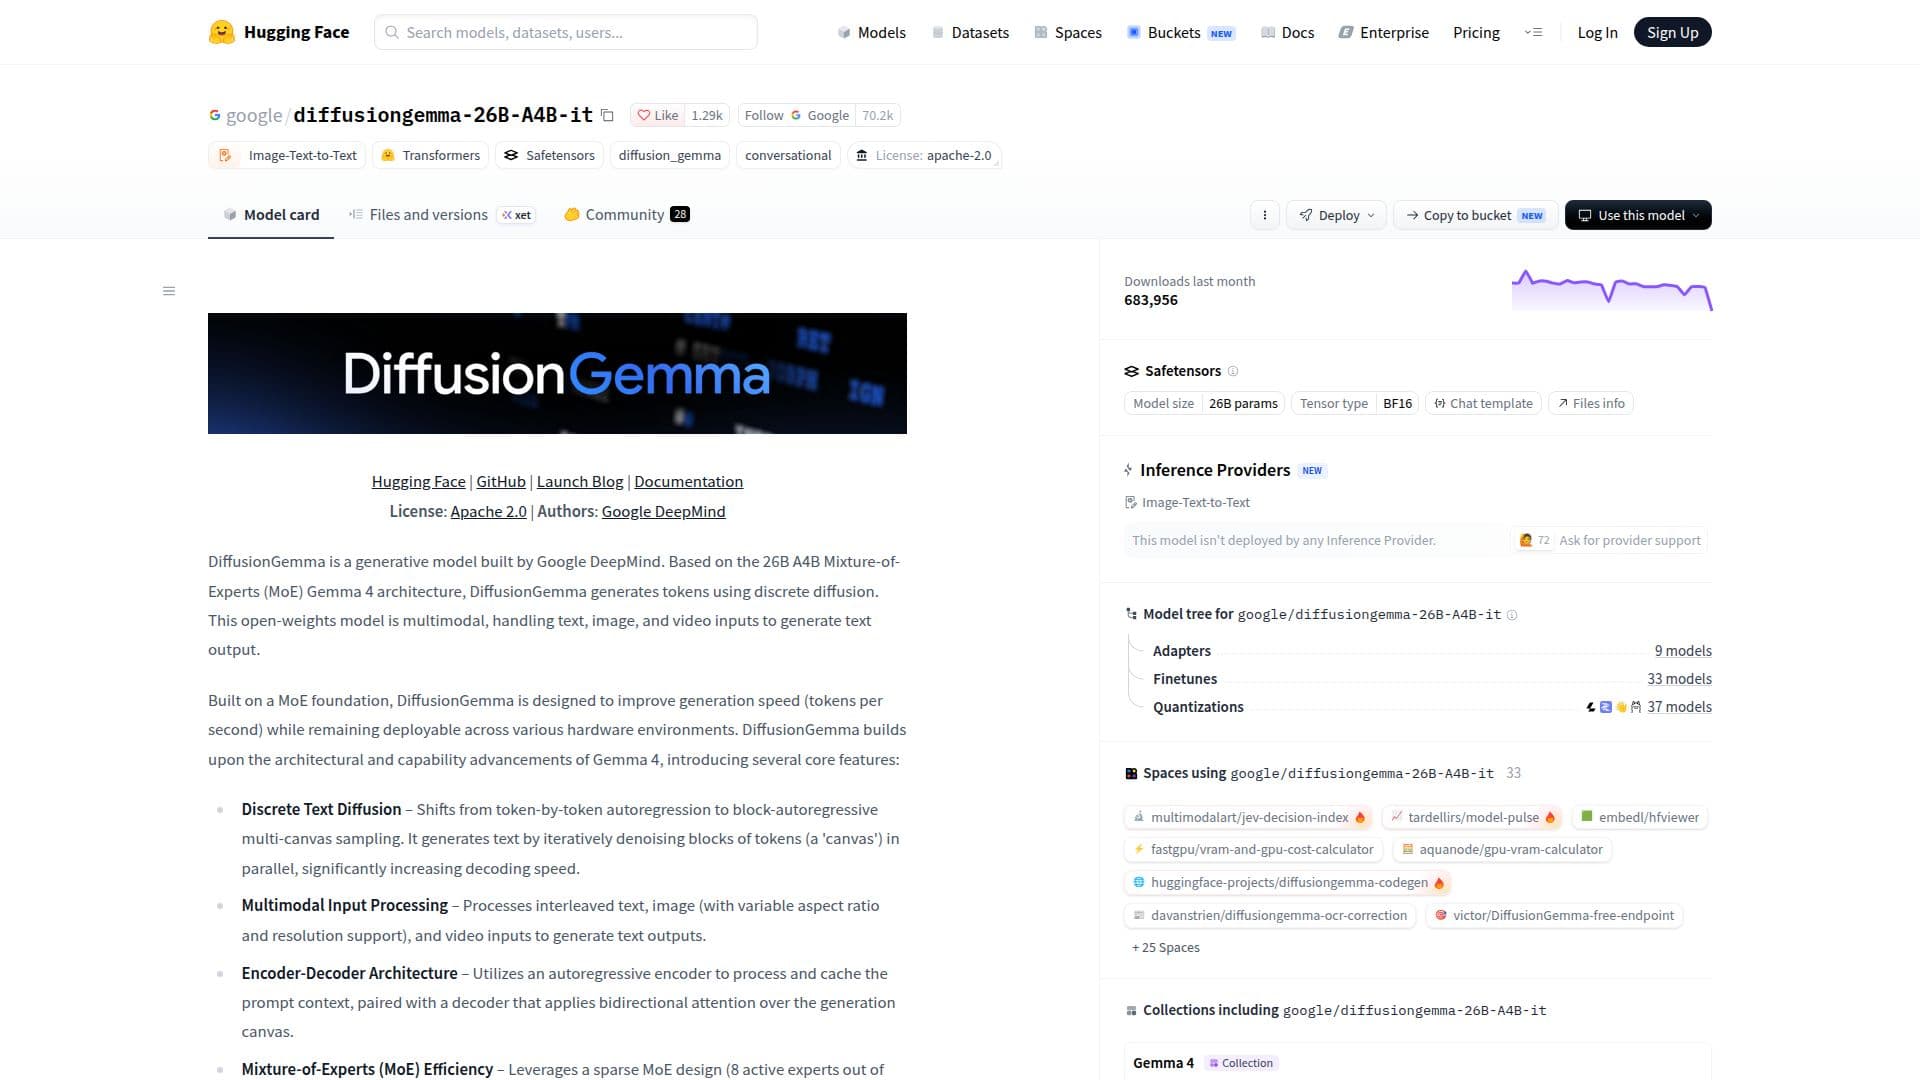
Description
DiffusionGemma, developed by Google DeepMind, is a generative model that leverages the 26B A4B Mixture-of-Experts (MoE) Gemma 4 architecture. It is designed to generate text outputs from multimodal inputs, including text, images, and videos. The model employs discrete diffusion to enhance token generation speed, making it suitable for deployment across diverse hardware environments.
Read More
The model's architecture features a block-autoregressive multi-canvas sampling method, which significantly increases decoding speed by denoising blocks of tokens in parallel. This approach allows DiffusionGemma to generate text at a higher speed compared to traditional autoregressive models. The encoder-decoder architecture utilizes an autoregressive encoder to process and cache the prompt context, while the decoder applies bidirectional attention over the generation canvas.
DiffusionGemma's sparse MoE design, with 8 active experts out of 128, provides strong reasoning capabilities while maintaining a low memory footprint. This efficiency makes it suitable for local execution and optimized for small batch size inference, achieving high-speed generation on a single capable accelerator.
The model supports native system prompt updates, enabling structured and controllable conversations. It also includes a configurable thinking mode for enhanced reasoning capabilities. With a context window of up to 256K tokens, DiffusionGemma can handle long-context tasks effectively.
DiffusionGemma has been evaluated against various benchmarks, showing competitive performance in text generation and reasoning tasks. It supports multilingual capabilities, pre-trained on over 140 languages, and offers robust image and video understanding features, including object detection, document parsing, and video content analysis.
Overall, DiffusionGemma is a versatile model designed for high-speed, multimodal text generation, suitable for a wide range of applications in content creation, research, and education.
- CategoryAI Models & LLMs
- Pricing ModelOpen Weights
- DeploymentCloud
- PlatformsWeb
DiffusionGemma Highlights
Discrete Text Diffusion
Multimodal Input Processing
Encoder-Decoder Architecture
Mixture-of-Experts Efficiency
Thinking Mode
Optimized for Small Batch Size Inference
Native System Prompt Support
Long Context Handling
Getting Started with DiffusionGemma
Access model page: Visit the Hugging Face model page
Authenticate: Log in or create an account
Configure: Set up the model parameters
Send prompts: Input text, image, or video prompts
Fine-tune: Adjust settings for specific tasks
DiffusionGemma's Use Cases
- Text Generation
- Image Data Extraction
- Video Understanding
- Multilingual Support
- Research and Education