ToolPotion
AI Advisor
Submit a Tool (Free)

Throttle

AI AppsMLOps & Model Deployment#193Freemium · OpenAI-compatible

Throttle optimizes AI inference costs on GPUs by identifying inefficient serving configurations. It provides savings in dollars per million tokens, ensuring cost-effective AI operations. Compatible with various AI servers, it offers an open-source CLI and a free 2-month pilot.

Visit Website
Share
Throttle screenshot
Throttle screenshot

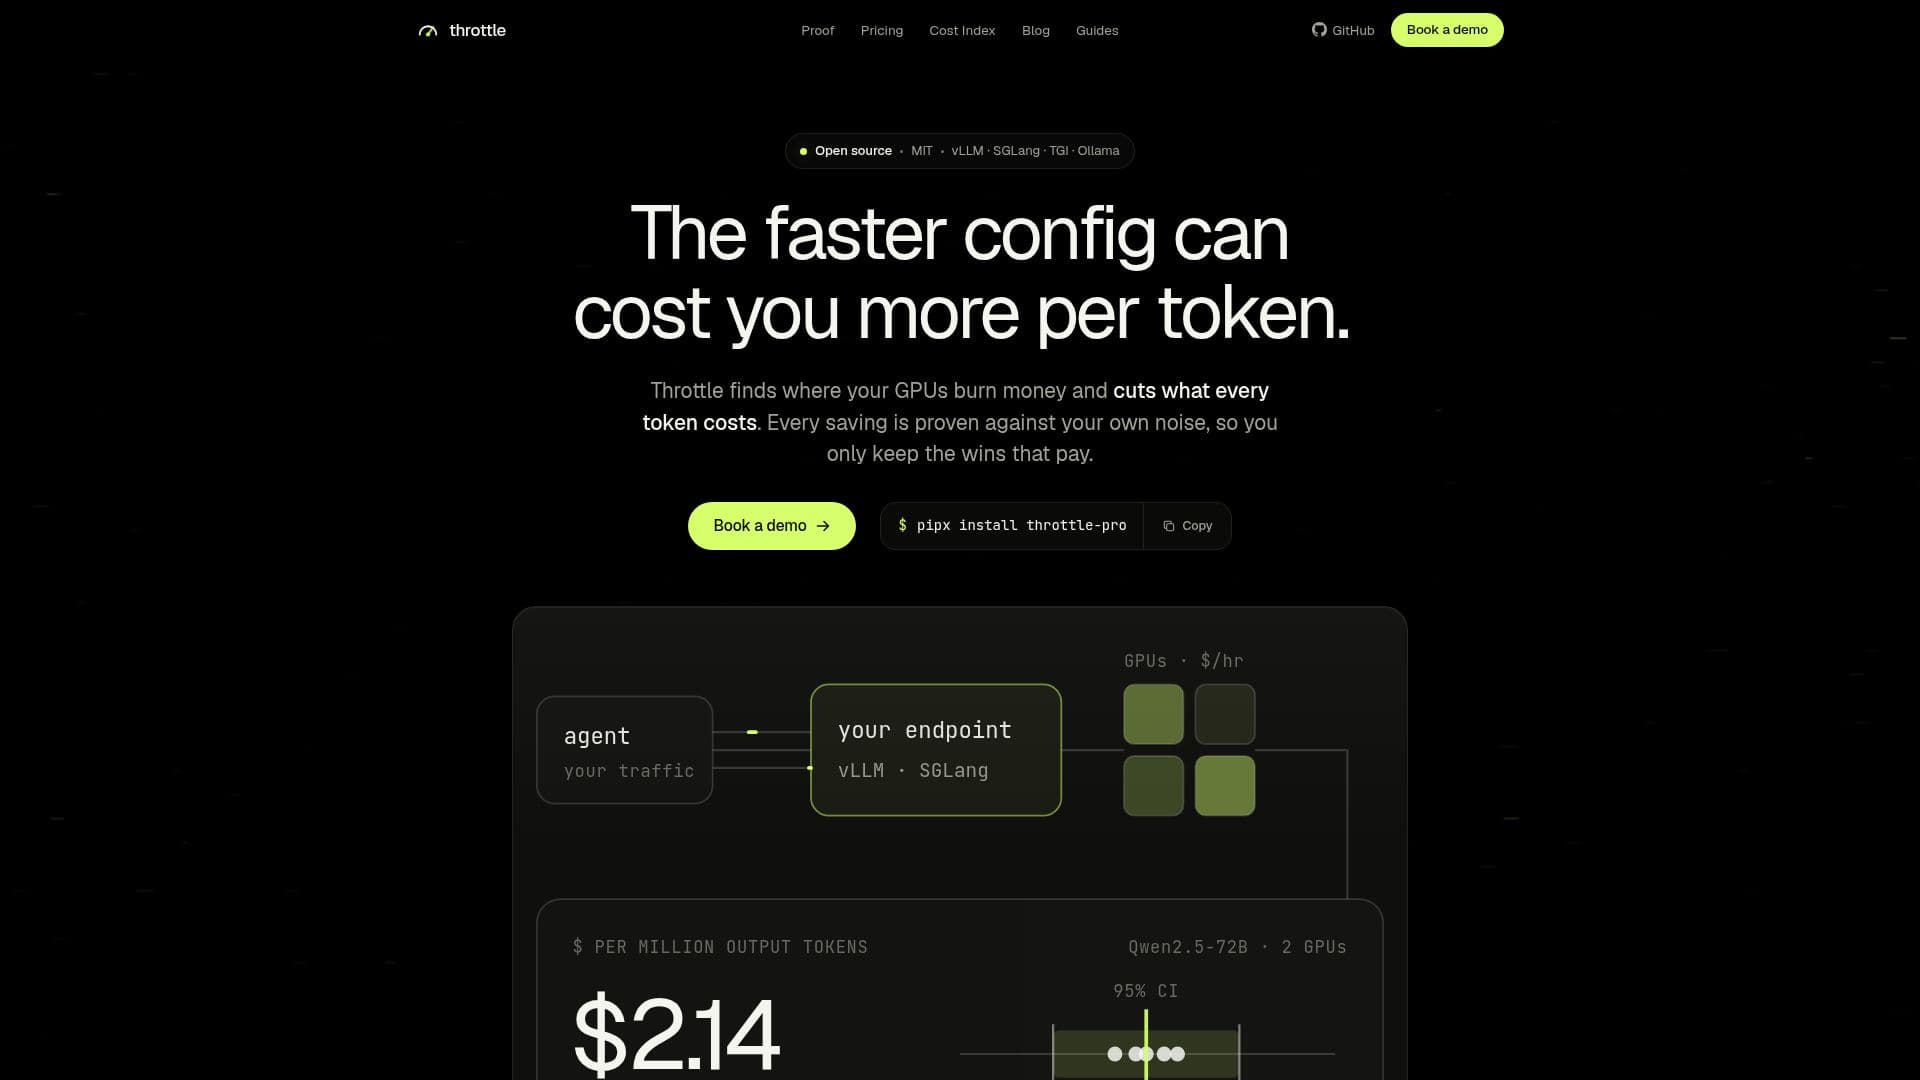
Throttle is a tool designed to reduce the costs associated with AI inference on GPUs, whether they are owned or rented. It achieves this by identifying serving configurations that are inefficient and proving the savings in terms of dollars per million tokens. This ensures that users only retain configurations that provide genuine cost benefits. Throttle is compatible with a wide range of AI servers, including vLLM, SGLang, TGI, Ollama, LMDeploy, llama.cpp, TensorRT-LLM, and NIM, among others.

Read More

The tool is open-source and available under the MIT license, allowing users to inspect and modify the code as needed. It operates locally, meaning that all prompts, responses, and keys remain within the user's environment, ensuring data privacy and security. Throttle provides a command-line interface (CLI) that is free to use, and it also offers a free 2-month pilot for enterprise users.

Throttle's pricing model is flexible, starting with $10 of free credits for Throttle Cloud, which does not require a credit card. The Starter plan is priced at $30 per month, the Pro plan at $50 per month, and the Team plan at $100 per month, each including equivalent usage credits. Enterprise plans are custom-priced and involve a hands-on pilot where users pay only from verified savings.

The tool's core functionality includes running checks to determine the cost per million tokens, with a 95% confidence interval to account for noise. It flags any changes in output length or token cap hits, ensuring that only genuine savings are considered. Throttle also provides a user interface (UI) for visualizing savings and costs, which can be accessed locally on the user's machine.

  • CategoryMLOps & Model Deployment
  • Pricing ModelFreemium
  • DeploymentLocal
  • PlatformsOpenAI-compatible

  • Open-source CLI

  • Cost optimization for AI inference

  • Compatibility with multiple AI servers

  • Local data processing

  • Free 2-month enterprise pilot

  • 95% confidence interval for savings

  • Noise-calibrated verdicts

  • Throttle Cloud with usage credits

  1. Install: pipx install throttle-pro

  2. Run: Execute throttle check on your setup

  3. Analyze: Review cost savings and configurations

  4. Optimize: Implement cost-effective configurations

  • Cost Reduction
  • Configuration Analysis
  • Data Privacy
  • Enterprise Savings
  • Open Source Development

Throttle Reviews

Loading...

Popular AI Tools Like Throttle

Hopscotch

AI Apps

Hopscotch provides access to over 500 AI models from providers like Anthropic, OpenAI, and Google through a single API. It allows users to set spending limits for each API key,…

MLOps & Model Deployment

Ranked #72 for Fine-tuning AI models

View Tool

AI Apps

Provides access to over 500 AI models from providers like Anthropic, OpenAI, and Google through a single API. It allows users to set spending limits for each API key,…Hopscotch provides access to over 500 AI models from providers like Anthropic, OpenAI, and Google through a single API. It allows users to set spending limits for each API key,…

MLOps & Model Deployment
Ranked #72 for Fine-tuning AI models

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
View Tool

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
See the Top 250 AI Apps

ZETIC Melange automates on-device AI deployment for any model on any device. Built by ex-Qualcomm engineers, it optimizes NPU acceleration, benchmarks on over 200 devices, and…

MLOps & Model Deployment

Ranked #149 in MLOps & Model Deployment

View Tool

Automates on-device AI deployment for any model on any device. Built by ex-Qualcomm engineers, it optimizes NPU acceleration, benchmarks on over 200 devices, and…ZETIC Melange automates on-device AI deployment for any model on any device. Built by ex-Qualcomm engineers, it optimizes NPU acceleration, benchmarks on over 200 devices, and…

MLOps & Model Deployment
Ranked #149 in MLOps & Model Deployment

Navige

AI Apps

Navige optimizes AI agent costs by routing calls to the right models, blocking unnecessary calls, and reusing completed work. It ensures the same output while reducing expenses,…

MLOps & Model Deployment

Ranked #174 in MLOps & Model Deployment

View Tool

AI Apps

Optimizes AI agent costs by routing calls to the right models, blocking unnecessary calls, and reusing completed work. It ensures the same output while reducing expenses,…Navige optimizes AI agent costs by routing calls to the right models, blocking unnecessary calls, and reusing completed work. It ensures the same output while reducing expenses,…

MLOps & Model Deployment
Ranked #174 in MLOps & Model Deployment

Inference.net provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…

MLOps & Model Deployment

Ranked #78 for Fine-tuning AI models

View Tool

Provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…Inference.net provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…

MLOps & Model Deployment
Ranked #78 for Fine-tuning AI models

GPUX

AI Apps

GPUX offers serverless GPU inference for AI models, enabling fast deployment and execution of machine learning workloads. It provides quick cold starts, supports various AI models…

MLOps & Model Deployment
View Tool

AI Apps

Offers serverless GPU inference for AI models, enabling fast deployment and execution of machine learning workloads. It provides quick cold starts, supports various AI models…GPUX offers serverless GPU inference for AI models, enabling fast deployment and execution of machine learning workloads. It provides quick cold starts, supports various AI models…

MLOps & Model Deployment
See the Top 250 AI Apps

Chutes is a serverless AI compute platform that allows users to deploy, run, and scale any AI model in seconds. With a focus on open-source models, it provides a flexible and…

MLOps & Model Deployment
View Tool

Serverless AI compute platform that allows users to deploy, run, and scale any AI model in seconds. With a focus on open-source models, it provides a flexible and…Chutes is a serverless AI compute platform that allows users to deploy, run, and scale any AI model in seconds. With a focus on open-source models, it provides a flexible and…

MLOps & Model Deployment
See the Top 250 AI Apps

GMI Cloud

AI Apps

GMI Cloud offers high-performance GPU cloud infrastructure for AI workloads. It supports serverless inference, dedicated GPU clusters, and bare metal AI infrastructure, providing…

MLOps & Model Deployment

Ranked #76 in AI DevOps & Cloud Tools

View Tool

AI Apps

Offers high-performance GPU cloud infrastructure for AI workloads. It supports serverless inference, dedicated GPU clusters, and bare metal AI infrastructure, providing…GMI Cloud offers high-performance GPU cloud infrastructure for AI workloads. It supports serverless inference, dedicated GPU clusters, and bare metal AI infrastructure, providing…

MLOps & Model Deployment
Ranked #76 in AI DevOps & Cloud Tools
1 of 8