Description
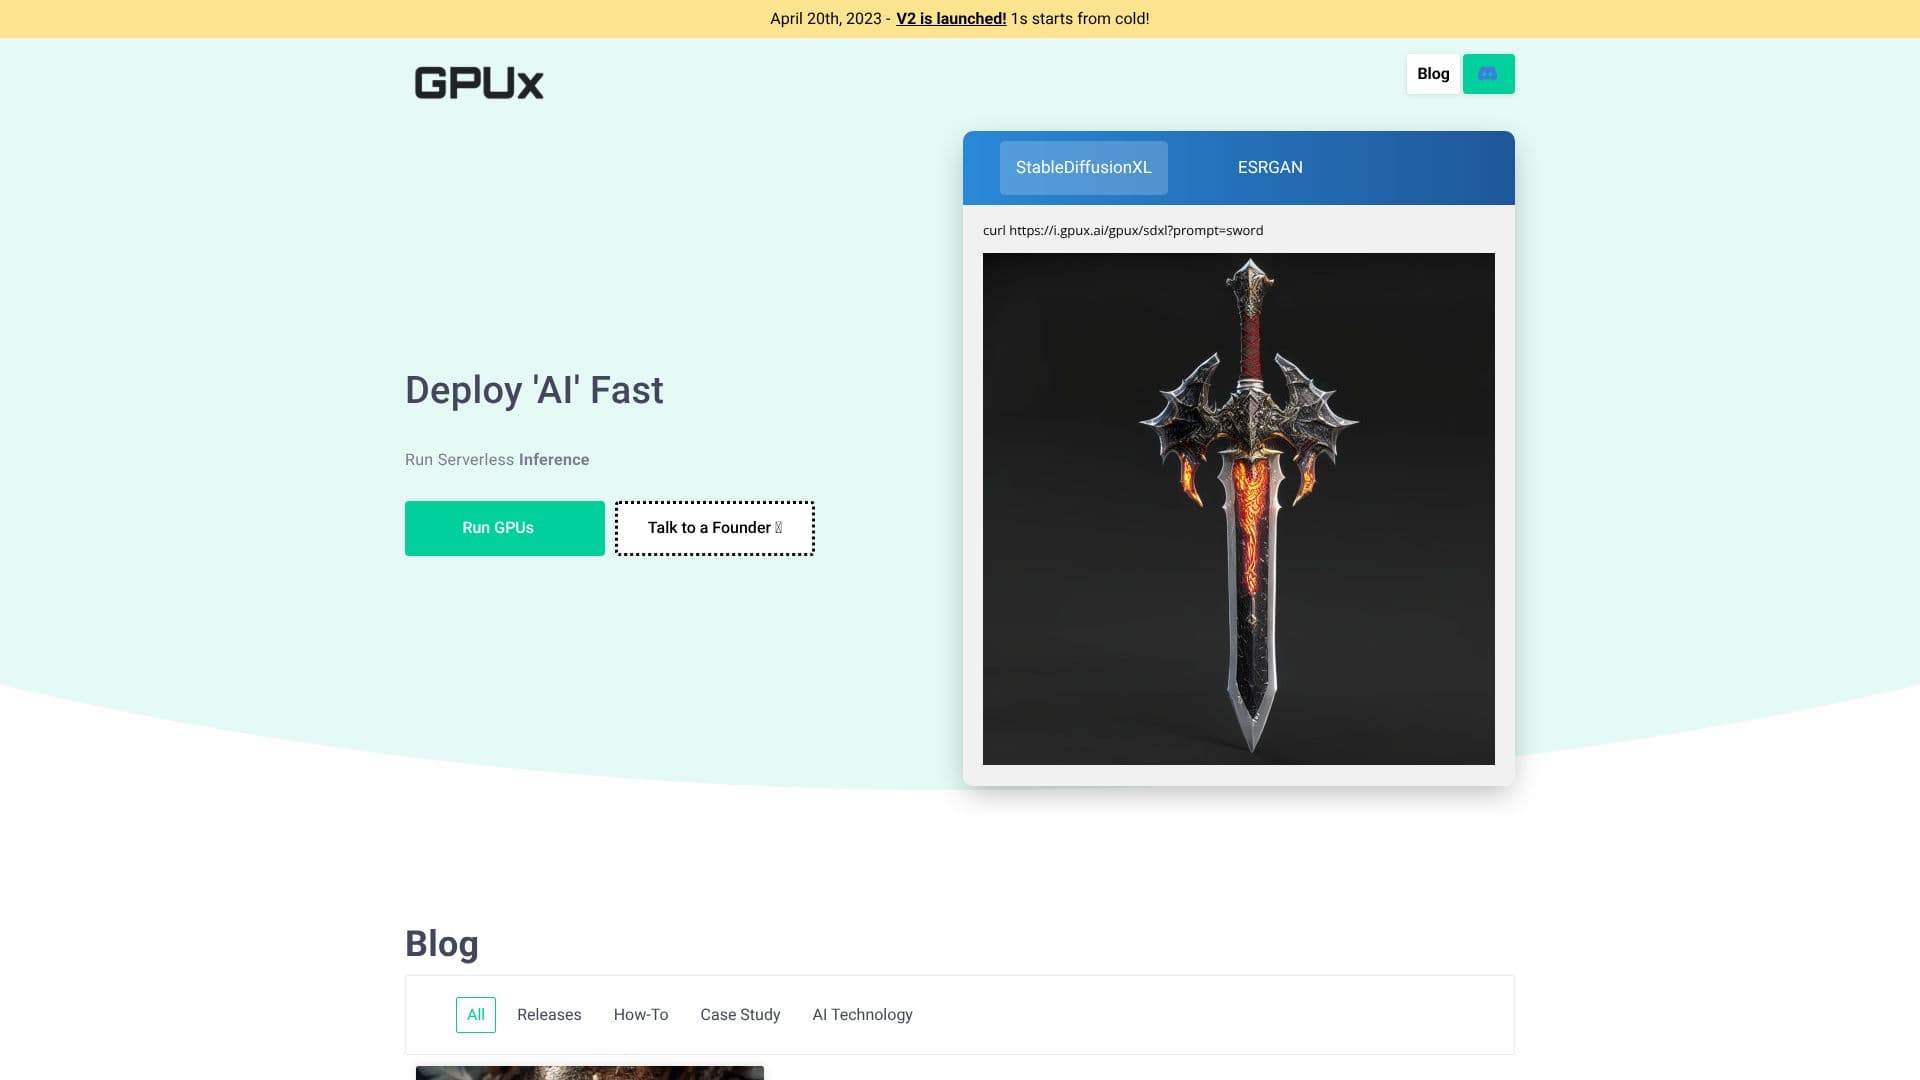
GPUX is a serverless inference platform designed to accelerate the deployment and execution of AI and machine learning models. Launched with V2 on April 20th, 2023, GPUX focuses on providing rapid cold starts, with instances beginning from just 1 second. This capability is crucial for applications requiring immediate responsiveness.
Read More
The platform supports a range of popular AI models, including Stable Diffusion XL (SDXL), ESRGAN, and WHISPER, making it versatile for various AI tasks such as image generation, upscaling, and speech-to-text. GPUX allows users to deploy their AI models and run serverless inference, abstracting away the complexities of infrastructure management.
Beyond running inference, GPUX offers a unique feature for monetizing AI models. Users can sell inference requests on their private models to other organizations, creating a marketplace for AI capabilities. This peer-to-peer (P2P) model can generate revenue for model owners while providing access to specialized AI for other businesses.
GPUX emphasizes the importance of the "right fit" for machine learning workloads, drawing a parallel to how Nike now crafts specialized women's cleats. This means tailoring the infrastructure and deployment to the specific needs of the AI task. The platform supports features like ReadWrite Volumes, enhancing flexibility for data handling during inference.
The target audience for GPUX includes developers, data scientists, and organizations looking to efficiently deploy and scale AI models without managing underlying hardware. The platform aims to democratize access to GPU compute for AI inference, making it faster and more cost-effective. The team behind GPUX includes Annie (Marketing), Ivan (Tech), and Henry (Operations), with contact information and LinkedIn profiles provided for engagement.
GPUX also offers resources such as a blog with articles on AI technology, how-to guides, and case studies. Recent blog posts highlight performance improvements, such as making Stable Diffusion XL 50% faster on RTX 4090, demonstrating a commitment to optimization and user education. The platform is built with a focus on ease of use and performance, enabling users to "Deploy 'AI' Fast."
- CategoryMLOps & Model Deployment
- DeploymentServerless
- PlatformsWeb
GPUX's Core Features
Serverless GPU inference
1-second cold starts
Support for Stable Diffusion XL
Support for WHISPER
Support for ESRGAN
Run inference on deployed models
Sell inference requests on private models
ReadWrite Volumes support
P2P model for inference requests
Fast deployment of AI models
Scalable inference infrastructure
How to use GPUX?
Deploy Model: Upload your trained AI model to the GPUX platform.
Configure Inference: Set up the parameters for running inference on your model.
Run Inference: Execute inference tasks on demand, leveraging serverless GPUs.
Optimize Performance: Utilize features to enhance model speed and efficiency.
Monetize Model (Optional): Offer inference services for your private model to other users.
GPUX's Use Cases
- AI Model Deployment
- Serverless Inference
- Image Generation
- Speech-to-Text
- Model Monetization
- AI Performance Optimization
- GPU Compute Access