ToolPotion
AI Advisor
Submit a Tool (Free)

three.dev

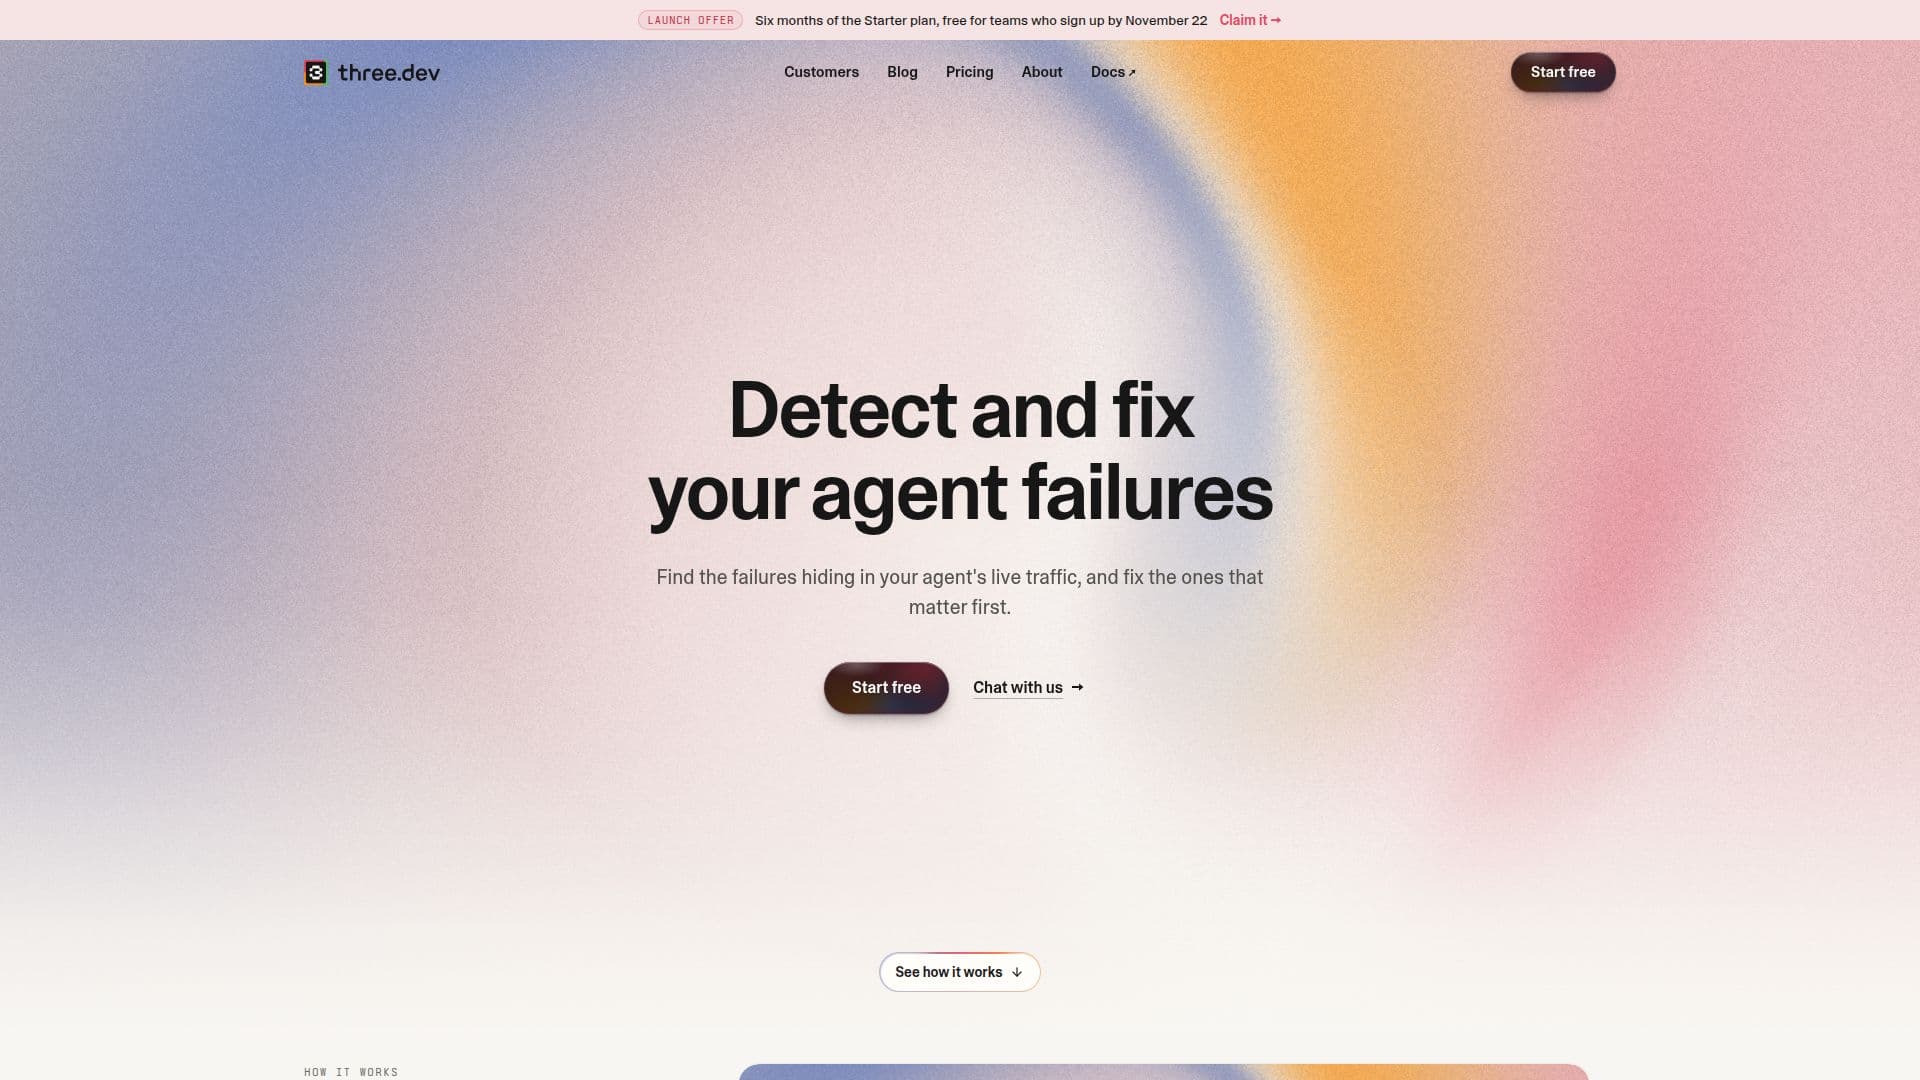
three.dev helps teams detect and fix AI agent failures by scoring live LLM traffic and grouping issues into ranked failure modes. It integrates with coding agents to automate fixes, allowing developers to ship AI changes based on evidence rather than assumptions. The platform ensures high-quality AI features by identifying and resolving critical errors efficiently.

Visit Website
Share
three.dev screenshot

three.dev is a specialized platform designed to help development teams detect and fix failures in their AI agents. It operates by recording the Large Language Model (LLM) traffic of an AI feature, scoring individual requests, and then grouping identified failures into named failure modes. These failure modes are ranked by severity, allowing teams to prioritize and address the most impactful issues first.

Read More

The platform integrates seamlessly into existing development workflows. Users can set up three.dev with a single prompt, which enables their coding agent to install the necessary skills and route LLM calls through the three.dev proxy. This proxy forwards requests to the AI provider while simultaneously sending responses to three.dev's evaluator, ensuring that scoring adds no latency to the application's performance. Once enough failures accumulate, three.dev automatically groups them, providing clear insights into common problems like incorrect refund windows or ignored language requests.

A key capability of three.dev is its ability to provide evidence-backed issues. Every identified problem cites exactly where it went wrong, down to a specific line in the system prompt or a message within a conversation. This precision allows coding agents, often integrated via MCP (Managed Code Platform), to automatically fix these issues. For instance, if an agent is giving a wrong refund window, three.dev can pinpoint the conflicting code and suggest a fix, as demonstrated by an example where a hardcoded 14-day window was updated to align with a 30-day policy.

three.dev also supports robust experimentation. Teams can replay past traffic to test new agent versions (v4) against recorded requests without impacting live users, observing changes in failure rates. For more advanced testing, it allows splitting real sessions, where a portion of live users interact with the new version, enabling comparison of quality and business metrics. This approach helps teams ship changes on evidence, ensuring improvements before full deployment. The platform also supports the development of Specialized Language Models (SLMs) trained on specific traffic, which can outperform frontier models in quality, latency, and cost for particular use cases.

Pricing for three.dev includes a Free plan, a Starter plan at $79/month, and a Pro plan at $249/month, with Enterprise options available for custom needs. All plans include scoring and unlimited seats. The Free plan offers 0.1 GB of processed data and 5,000 scored requests per month. The Starter plan increases this to 5 GB of data and 10,000 scored requests, while the Pro plan provides 20 GB of data and 25,000 scored requests. Additional usage is charged per GB of data and per 1,000 scored requests. The platform ensures that going over plan limits never blocks traffic; it simply stops recording or scoring requests until the next billing cycle. Data is stored in the United States, encrypted in transit, and provider keys are encrypted at rest. three.dev does not train on customer traffic for anyone but the customer, ensuring data privacy and security.

  • CategoryAI Code Review & Testing
  • Pricing ModelFreemium
  • DeploymentCloud
  • PlatformsWeb

  • LLM Traffic Recording: Records live LLM traffic from AI features.

  • Request Scoring: Scores individual LLM requests for performance and accuracy.

  • Failure Mode Grouping: Groups identified failures into named categories ranked by severity.

  • Evidence-Backed Issues: Pinpoints exact sources of errors, down to specific prompt lines.

  • Coding Agent Integration: Facilitates automated fixes via MCP integration for coding agents.

  • Live Conversation Analysis: Analyzes live conversations to identify agent failures.

  • Before and After Comparison: Compares agent performance before and after fixes.

  • Traffic Replay: Allows testing new agent versions on recorded past traffic.

  • Live Session Experiments: Enables A/B testing of agent changes on a share of live users.

  • Specialized Language Model (SLM) Training: Supports building custom models trained on specific traffic.

  • Chat Interface: Allows asking about traffic and failures in natural language.

  • Unlimited Seats: All plans include unlimited user seats for team collaboration.

  • Data Encryption: Encrypts traffic in transit with TLS 1.2+ and provider keys at rest with AES-256-GCM.

  • No Training on Customer Data: Ensures customer traffic is not used for general model training.

  • Customizable Failure Modes: Allows reshaping failure modes to match team's mental model.

  1. Set Up: Paste a single prompt into your agent (Claude Code, Codex, or Cursor) to install three.dev skills and integrate it into your code.

  2. Route Traffic: Your app's LLM requests pass through the three.dev proxy to your AI provider, with responses simultaneously sent to the evaluator.

  3. Monitor Failures: three.dev records and scores requests, grouping failures into ranked failure modes as they collect.

  4. Analyze Issues: Read detailed failure modes with evidence, showing where and why the agent went wrong.

  5. Fix Failures: Use the MCP integration to hand the top failure modes to your coding agent for automated fixes.

  6. Experiment Safely: Test changes on recorded traffic or a share of live sessions to verify improvements before full deployment.

  7. Optimize Performance: Utilize insights from failure analysis and experiments to continuously improve agent quality and business metrics.

  • AI Agent Quality Assurance
  • Automated Bug Fixing
  • LLM Performance Monitoring
  • Evidence-Based AI Development
  • Custom LLM Training
  • Proactive Failure Detection
  • Conversation Analysis
  • A/B Testing AI Agents
  • Developer Workflow Integration

three.dev Reviews

Loading...

Popular AI Tools Like three.dev

Checksum automates the generation, execution, and maintenance of end-to-end tests, enabling teams to ship code confidently. With 70% of failures resolving autonomously, it reduces…

AI Code Review & Testing

Ranked #48 in AI Code Review & Testing

View Tool

Automates the generation, execution, and maintenance of end-to-end tests, enabling teams to ship code confidently. With 70% of failures resolving autonomously, it reduces…Checksum automates the generation, execution, and maintenance of end-to-end tests, enabling teams to ship code confidently. With 70% of failures resolving autonomously, it reduces…

AI Code Review & Testing
Ranked #48 in AI Code Review & Testing

LangWatch

AI Apps

LangWatch is an AI agent testing, LLM evaluation, and observability platform. It allows developers to simulate real-world scenarios, prevent regressions, and debug issues by…

MLOps & Model Deployment

Ranked #14 in Prompt Engineering Tools

View Tool

AI Apps

AI agent testing, LLM evaluation, and observability platform. It allows developers to simulate real-world scenarios, prevent regressions, and debug issues by…LangWatch is an AI agent testing, LLM evaluation, and observability platform. It allows developers to simulate real-world scenarios, prevent regressions, and debug issues by…

FeaturedMLOps & Model Deployment
Ranked #14 in Prompt Engineering Tools

evalship

AI Apps

evalship provides quality control for LLM evaluations, identifying flaws and optimizing prompts and models. It integrates with existing eval frameworks, comments on pull requests…

AI Code Review & Testing

Ranked #209 in AI Code Review & Testing

View Tool

AI Apps

Provides quality control for LLM evaluations, identifying flaws and optimizing prompts and models. It integrates with existing eval frameworks, comments on pull requests…evalship provides quality control for LLM evaluations, identifying flaws and optimizing prompts and models. It integrates with existing eval frameworks, comments on pull requests…

AI Code Review & Testing
Ranked #209 in AI Code Review & Testing

AI CodeOps

AI Apps

AI CodeOps is a browser-based platform that uses AI agents to plan, build, review, test, and ship code. It ensures code quality through automated checks and human approval,…

AI Code Review & Testing

Ranked #238 in AI Code Review & Testing

View Tool

AI Apps

Browser-based platform that uses AI agents to plan, build, review, test, and ship code. It ensures code quality through automated checks and human approval,…AI CodeOps is a browser-based platform that uses AI agents to plan, build, review, test, and ship code. It ensures code quality through automated checks and human approval,…

AI Code Review & Testing
Ranked #238 in AI Code Review & Testing

Raindrop

AI Apps

Raindrop is an observability and monitoring platform for AI agents that captures every production run, automatically detects silent failures like hallucinations and loops, and…

MLOps & Model Deployment

Ranked #41 in MLOps & Model Deployment

View Tool

AI Apps

Observability and monitoring platform for AI agents that captures every production run, automatically detects silent failures like hallucinations and loops, and…Raindrop is an observability and monitoring platform for AI agents that captures every production run, automatically detects silent failures like hallucinations and loops, and…

MLOps & Model Deployment
Ranked #41 in MLOps & Model Deployment

Latitude

AI Apps

An open-source AI agent observability and monitoring platform that traces agents in production, surfaces failures, and dispatches coding agents to fix them automatically.

MLOps & Model Deployment

Ranked #40 in Prompt Engineering Tools

View Tool

AI Apps

An open-source AI agent observability and monitoring platform that traces agents in production, surfaces failures, and dispatches coding agents to fix them automatically.

FeaturedMLOps & Model Deployment
Ranked #40 in Prompt Engineering Tools

Resolve.ai

AI Apps

Resolve.ai is an AI-driven platform that manages alerts, conducts root cause analysis, and troubleshoots incidents quickly, allowing engineers to focus on building software. It…

AI DevOps & Cloud Tools

Ranked #19 for CTOs

View Tool

AI Apps

AI-driven platform that manages alerts, conducts root cause analysis, and troubleshoots incidents quickly, allowing engineers to focus on building software. It…Resolve.ai is an AI-driven platform that manages alerts, conducts root cause analysis, and troubleshoots incidents quickly, allowing engineers to focus on building software. It…

AI DevOps & Cloud Tools
Ranked #19 for CTOs

HoneyHive

AI Apps

HoneyHive provides an observability layer for production AI agents, unifying monitoring and evaluation. It enables continuous improvement loops, allowing teams to confidently ship…

MLOps & Model Deployment

Ranked #32 for Prompt Engineers

View Tool

AI Apps

Provides an observability layer for production AI agents, unifying monitoring and evaluation. It enables continuous improvement loops, allowing teams to confidently ship…HoneyHive provides an observability layer for production AI agents, unifying monitoring and evaluation. It enables continuous improvement loops, allowing teams to confidently ship…

FeaturedMLOps & Model Deployment
Ranked #32 for Prompt Engineers
1 of 8