ToolPotion
AI Advisor
Submit a Tool (Free)

evalship

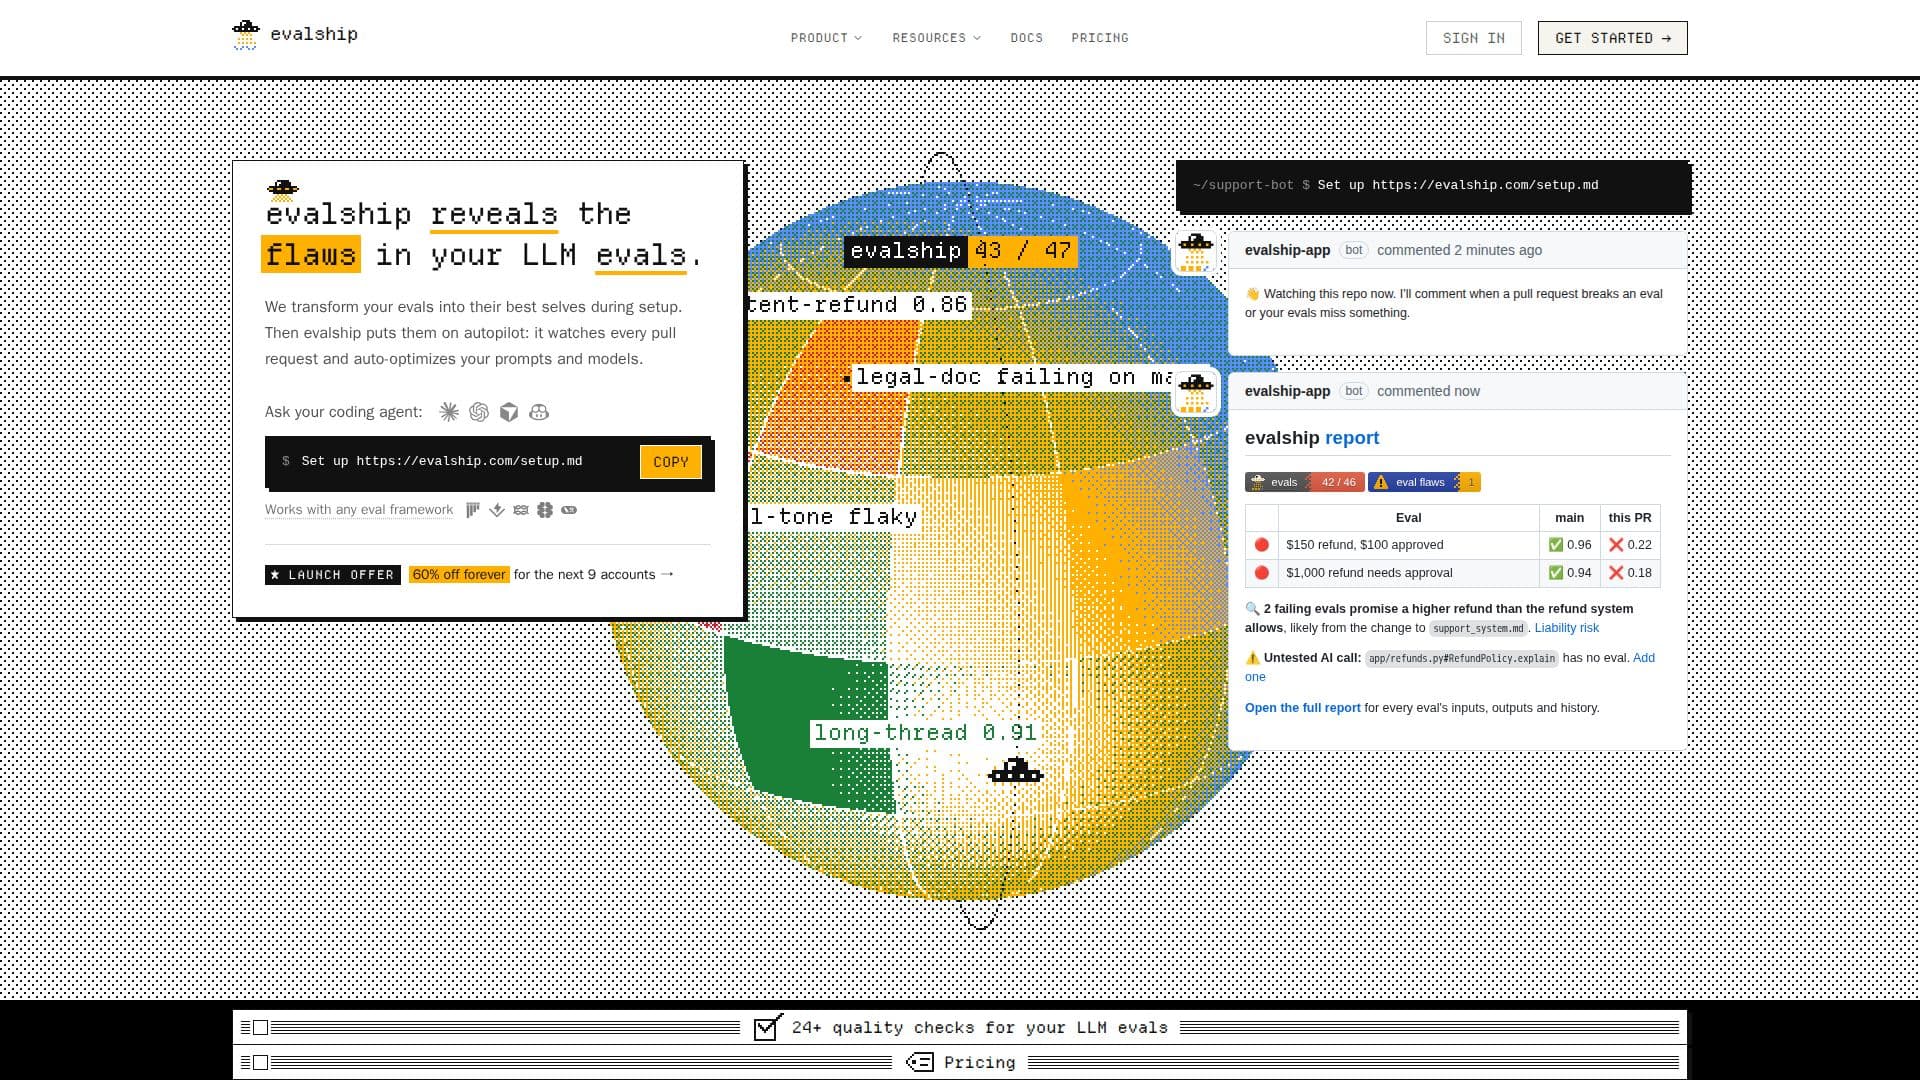
evalship provides quality control for LLM evaluations, identifying flaws and optimizing prompts and models. It integrates with existing eval frameworks, comments on pull requests with detailed breakdowns of what broke and why, and helps ensure AI calls are thoroughly tested. The platform aims to put your LLM evals on autopilot, improving reliability and performance.

Visit Website
Share
evalship screenshot
evalship screenshot

evalship offers a comprehensive quality control solution specifically designed for Large Language Model (LLM) evaluations. It integrates directly into your GitHub workflow, acting as a vigilant guardian for your LLM development process. The core purpose of evalship is to identify and address flaws in your evaluation setups, ensuring that your LLMs perform as expected and do not introduce regressions.

Read More

Upon setup, evalship thoroughly reviews your existing evaluators, judges, and prompts to pinpoint weaknesses such as evals that incorrectly pass or rules that lack proper test coverage. It then monitors every pull request, providing immediate feedback on what broke, why it broke, and the likely cause. This includes flagging untested AI calls and separating genuine regressions from flaky eval results by analyzing historical performance on your default branch.

The platform works seamlessly with various eval frameworks, including those that produce JUnit XML, promptfoo JSON, or evalship JSON, such as pytest, Vitest, Jest, RSpec, Go, Java, PHPUnit, Rust, Langfuse, Braintrust, and LangSmith. It doesn't run your evals directly; instead, your GitHub Actions workflow or coding agent executes them using your API keys, and evalship processes the results.

Beyond identifying issues, evalship helps optimize your prompts and models. Through your coding agent, it tests different changes on your machine, such as cheaper models or clearer rules, and reports which changes yield statistically significant improvements. This allows teams to make data-driven decisions to enhance model performance and cost-efficiency. evalship also provides weekly reports summarizing eval performance and highlighting critical issues caught before they reach production.

Pricing includes a free tier for public repositories and one private repository with one user, offering 100 PR analyses and 30 days of eval history. Paid plans (Team, Pro, Business) offer increased users, private repositories, PR analyses, and longer eval history, with options for monthly or yearly billing. A launch offer provides significant discounts for early adopters. evalship ensures security by not storing your source code or API keys, only processing diffs and eval results.

  • CategoryAI Code Review & Testing
  • Pricing ModelFreemium
  • DeploymentCloud
  • PlatformsWeb

  • Identifies flaws in LLM evaluations during setup

  • Comments on every pull request with detailed breakdown of eval failures

  • Auto-optimizes prompts and models based on performance data

  • Works with any existing eval framework (JUnit XML, promptfoo, evalship JSON)

  • Provides 24+ quality checks for LLM evals

  • Separates regressions from flaky evals using historical data

  • Detects untested AI calls in pull requests

  • Blocks merges that break evaluation rules (configurable)

  • Unblocks pull requests once issues are fixed

  • Emails weekly eval reports summarizing performance and issues

  • Supports monorepos and multiple eval workflows

  • Integrates with Langfuse, Braintrust, and LangSmith without requiring a switch

  • Offers a free review of evals at setup

  • Allows coding agents to check changes before opening pull requests

  • Ensures security by not storing source code or API keys

  1. Set up: Connect your GitHub repository and ask your coding agent to set up evalship, which reviews your evals and creates a setup pull request.

  2. Monitor pull requests: evalship automatically watches every pull request, commenting on changes that break evals or introduce untested AI calls.

  3. Review reports: Access detailed reports for every eval's inputs, outputs, and history to understand what broke and why.

  4. Optimize: Use evalship's optimization feature to test prompt and model changes with your coding agent, identifying improvements beyond chance.

  5. Receive reports: Get weekly email reports summarizing eval performance and highlighting critical issues caught before merging.

  • LLM Evaluation Quality Control
  • Automated Pull Request Review
  • Prompt and Model Optimization
  • Regression Prevention
  • Untested AI Call Detection
  • Flaky Eval Management
  • Compliance and Liability Risk Mitigation
  • Developer Workflow Enhancement

evalship Reviews

Loading...

Popular AI Tools Like evalship

LangWatch

AI Apps

LangWatch is an AI agent testing, LLM evaluation, and observability platform. It allows developers to simulate real-world scenarios, prevent regressions, and debug issues by…

MLOps & Model Deployment

Ranked #14 in Prompt Engineering Tools

View Tool

AI Apps

AI agent testing, LLM evaluation, and observability platform. It allows developers to simulate real-world scenarios, prevent regressions, and debug issues by…LangWatch is an AI agent testing, LLM evaluation, and observability platform. It allows developers to simulate real-world scenarios, prevent regressions, and debug issues by…

FeaturedMLOps & Model Deployment
Ranked #14 in Prompt Engineering Tools

EvalCore

AI Apps

EvalCore provides snapshot testing for AI behavior, allowing you to record how your LLM app behaves and replay it in CI on every change. It ensures that any modifications do not…

AI Code Review & Testing
View Tool

AI Apps

Provides snapshot testing for AI behavior, allowing you to record how your LLM app behaves and replay it in CI on every change. It ensures that any modifications do not…EvalCore provides snapshot testing for AI behavior, allowing you to record how your LLM app behaves and replay it in CI on every change. It ensures that any modifications do not…

AI Code Review & Testing
See the Top 250 AI Apps

Confident AI provides a comprehensive LLM evaluation platform that benchmarks AI systems, compares prompts and models, and identifies regressions using research-backed metrics. It…

Machine Learning Platforms

Ranked #48 for Monitoring AI models

View Tool

Provides a comprehensive LLM evaluation platform that benchmarks AI systems, compares prompts and models, and identifies regressions using research-backed metrics. It…Confident AI provides a comprehensive LLM evaluation platform that benchmarks AI systems, compares prompts and models, and identifies regressions using research-backed metrics. It…

Machine Learning Platforms
Ranked #48 for Monitoring AI models

Evidently AI provides open-source tools for evaluating and monitoring AI applications. It helps ensure AI systems are production-ready by testing LLMs and monitoring performance…

MLOps & Model Deployment

Ranked #21 in MLOps & Model Deployment

View Tool

Provides open-source tools for evaluating and monitoring AI applications. It helps ensure AI systems are production-ready by testing LLMs and monitoring performance…Evidently AI provides open-source tools for evaluating and monitoring AI applications. It helps ensure AI systems are production-ready by testing LLMs and monitoring performance…

MLOps & Model Deployment
Ranked #21 in MLOps & Model Deployment

mabl

AI Apps

mabl is an automated software testing platform that empowers teams to accelerate releases and ensure software quality. It utilizes machine learning and self-healing tests to…

AI Code Review & Testing

Ranked #32 in AI Code Review & Testing

View Tool

AI Apps

Automated software testing platform that empowers teams to accelerate releases and ensure software quality. It utilizes machine learning and self-healing tests to…mabl is an automated software testing platform that empowers teams to accelerate releases and ensure software quality. It utilizes machine learning and self-healing tests to…

AI Code Review & Testing
Ranked #32 in AI Code Review & Testing

Giskard OSS

AI GitHub Repos

Giskard OSS is an open-source evaluation and testing library designed for LLM agents. It provides tools to assess and improve the performance of language models, ensuring robust…

AI Code Review & Testing

Ranked #109 in AI GitHub Repos

View Tool

AI GitHub Repos

Open-source evaluation and testing library designed for LLM agents. It provides tools to assess and improve the performance of language models, ensuring robust…Giskard OSS is an open-source evaluation and testing library designed for LLM agents. It provides tools to assess and improve the performance of language models, ensuring robust…

AI Code Review & Testing
Ranked #109 in AI GitHub Repos

Future AGI

AI Apps

Future AGI is an open-source platform for building, testing, and monitoring AI agents. It helps catch and fix AI hallucinations in real-time with guardrails, comprehensive…

MLOps & Model Deployment

Ranked #38 in MLOps & Model Deployment

View Tool

AI Apps

Open-source platform for building, testing, and monitoring AI agents. It helps catch and fix AI hallucinations in real-time with guardrails, comprehensive…Future AGI is an open-source platform for building, testing, and monitoring AI agents. It helps catch and fix AI hallucinations in real-time with guardrails, comprehensive…

FeaturedMLOps & Model Deployment
Ranked #38 in MLOps & Model Deployment

DeepEval

AI GitHub Repos

DeepEval is an open-source framework designed for evaluating large language models (LLMs). It allows developers to contribute and improve the evaluation process, enhancing the…

MLOps & Model Deployment

Ranked #90 in AI GitHub Repos

View Tool

AI GitHub Repos

Open-source framework designed for evaluating large language models (LLMs). It allows developers to contribute and improve the evaluation process, enhancing the…DeepEval is an open-source framework designed for evaluating large language models (LLMs). It allows developers to contribute and improve the evaluation process, enhancing the…

MLOps & Model Deployment
Ranked #90 in AI GitHub Repos
1 of 8