Description
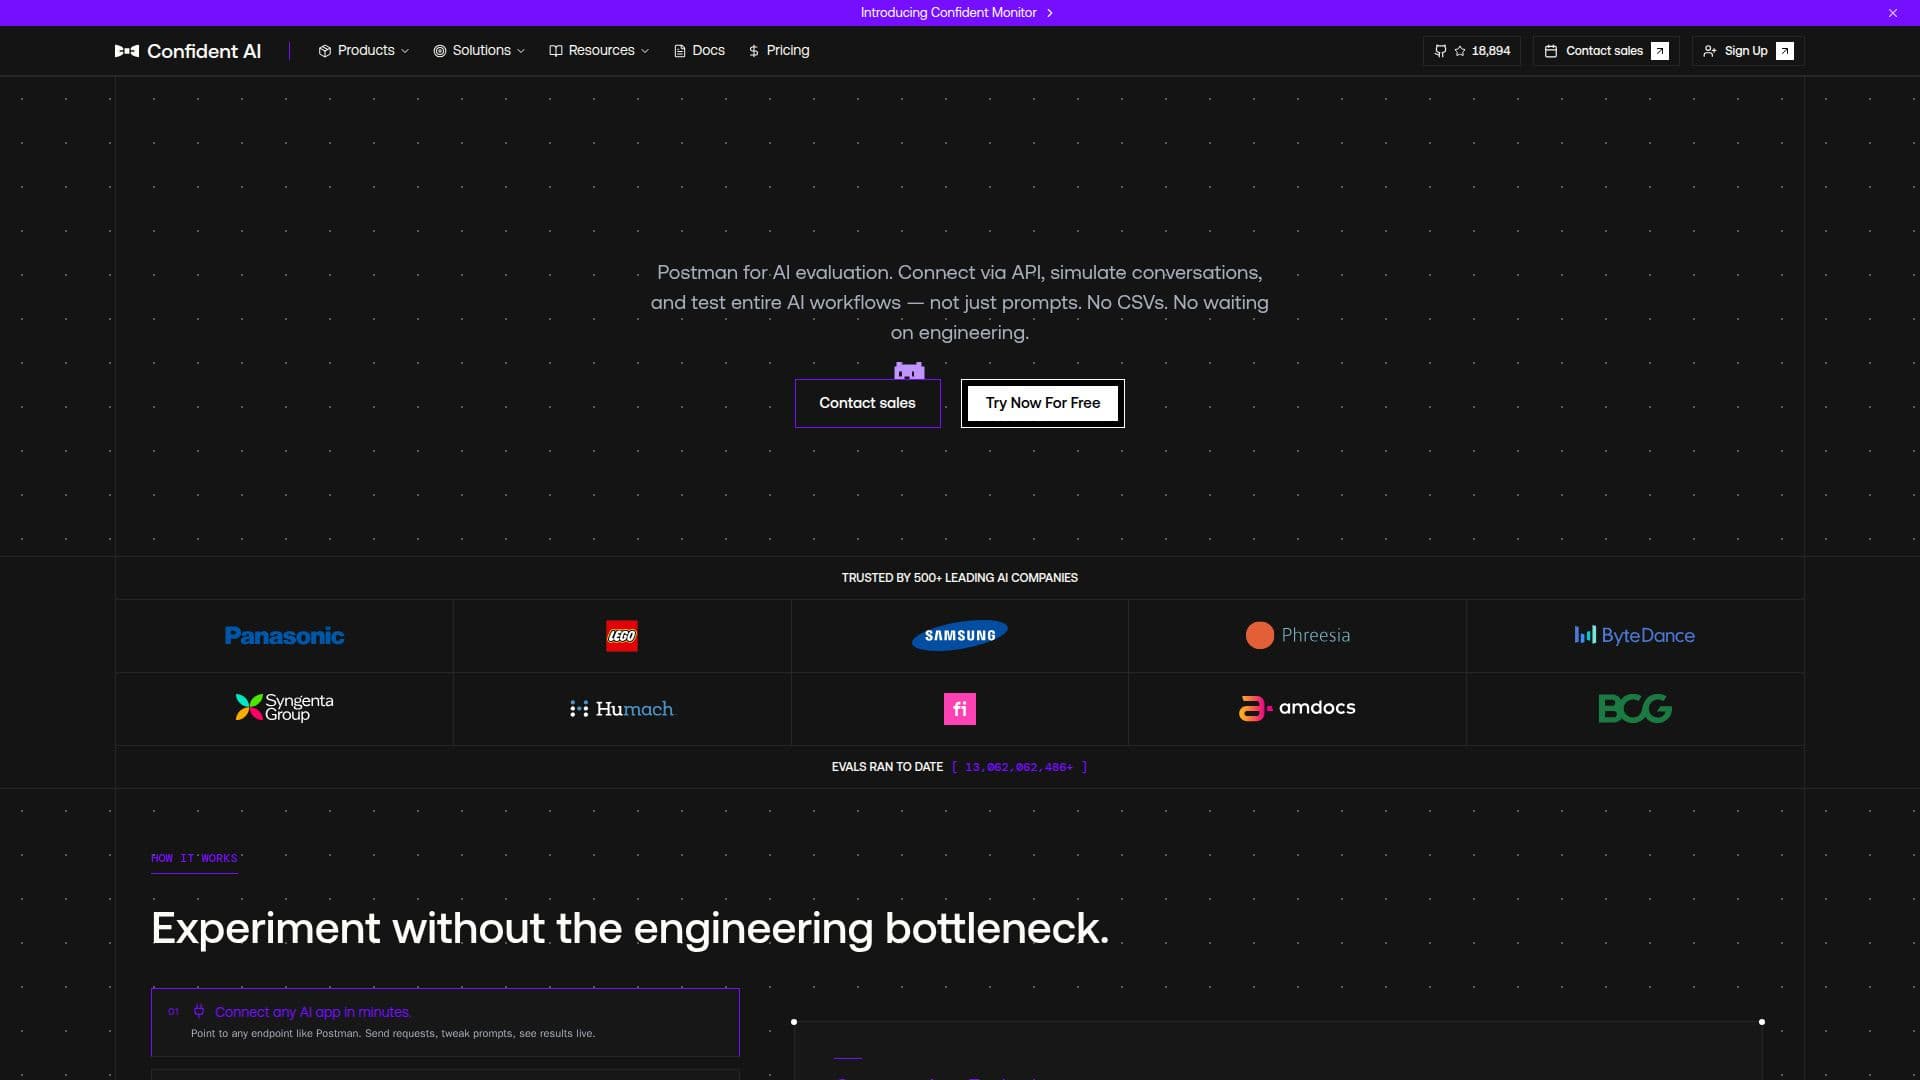
Confident AI offers a robust platform for evaluating large language models (LLMs). Built by the creators of DeepEval, it allows users to benchmark AI systems, compare prompts and models, and catch regressions using over 50 research-backed metrics. These metrics assess quality, tone, safety, and more, leveraging LLM-as-a-judge evaluators.
Read More
The platform supports multi-turn conversation testing, enabling users to simulate full conversations and identify failures that may only surface across multiple exchanges. Users can change variables such as models, prompts, and system logic, and run experiments to compare results side by side across every metric and pipeline step.
Confident AI is designed to be user-friendly, allowing product managers and domain experts to tweak prompts, run experiments, and evaluate results without needing engineering support. It supports major LLM providers like OpenAI, Anthropic, and Google, and integrates with cloud providers and gateways.
Pricing for Confident AI starts at $0 for individual developers, with plans scaling up to $2,000 per month for teams running business-critical AI. Enterprise pricing is customized based on organizational needs. The platform offers a free tier with generous limits, and users can upgrade or downgrade plans at any time.
Confident AI is trusted by companies that prioritize AI quality, offering tools to turn production failures into datasets, align metrics, and prevent regressions without custom engineering work. It saves significant time in AI evaluation and provides data to support quality decisions across teams.
- CategoryMachine Learning Platforms
- Pricing ModelFreemium
- DeploymentCloud
- PlatformsWeb
Confident AI's Core Features
LLM evaluation suite
50+ research-backed metrics
Multi-turn conversation testing
No engineering dependency
Supports major LLM providers
Side-by-side experiment comparison
Customizable evaluation models
Integration with CI/CD pipelines
How to use Confident AI?
Connect: Point to any AI app endpoint
Define: Upload test cases and set metrics
Run: Execute experiments on live apps
Ship: Integrate evals into CI for quality checks
Confident AI's Use Cases
- AI Benchmarking
- Prompt Testing
- Regression Detection
- Multi-Turn Conversations
- Custom Model Evaluation