Description
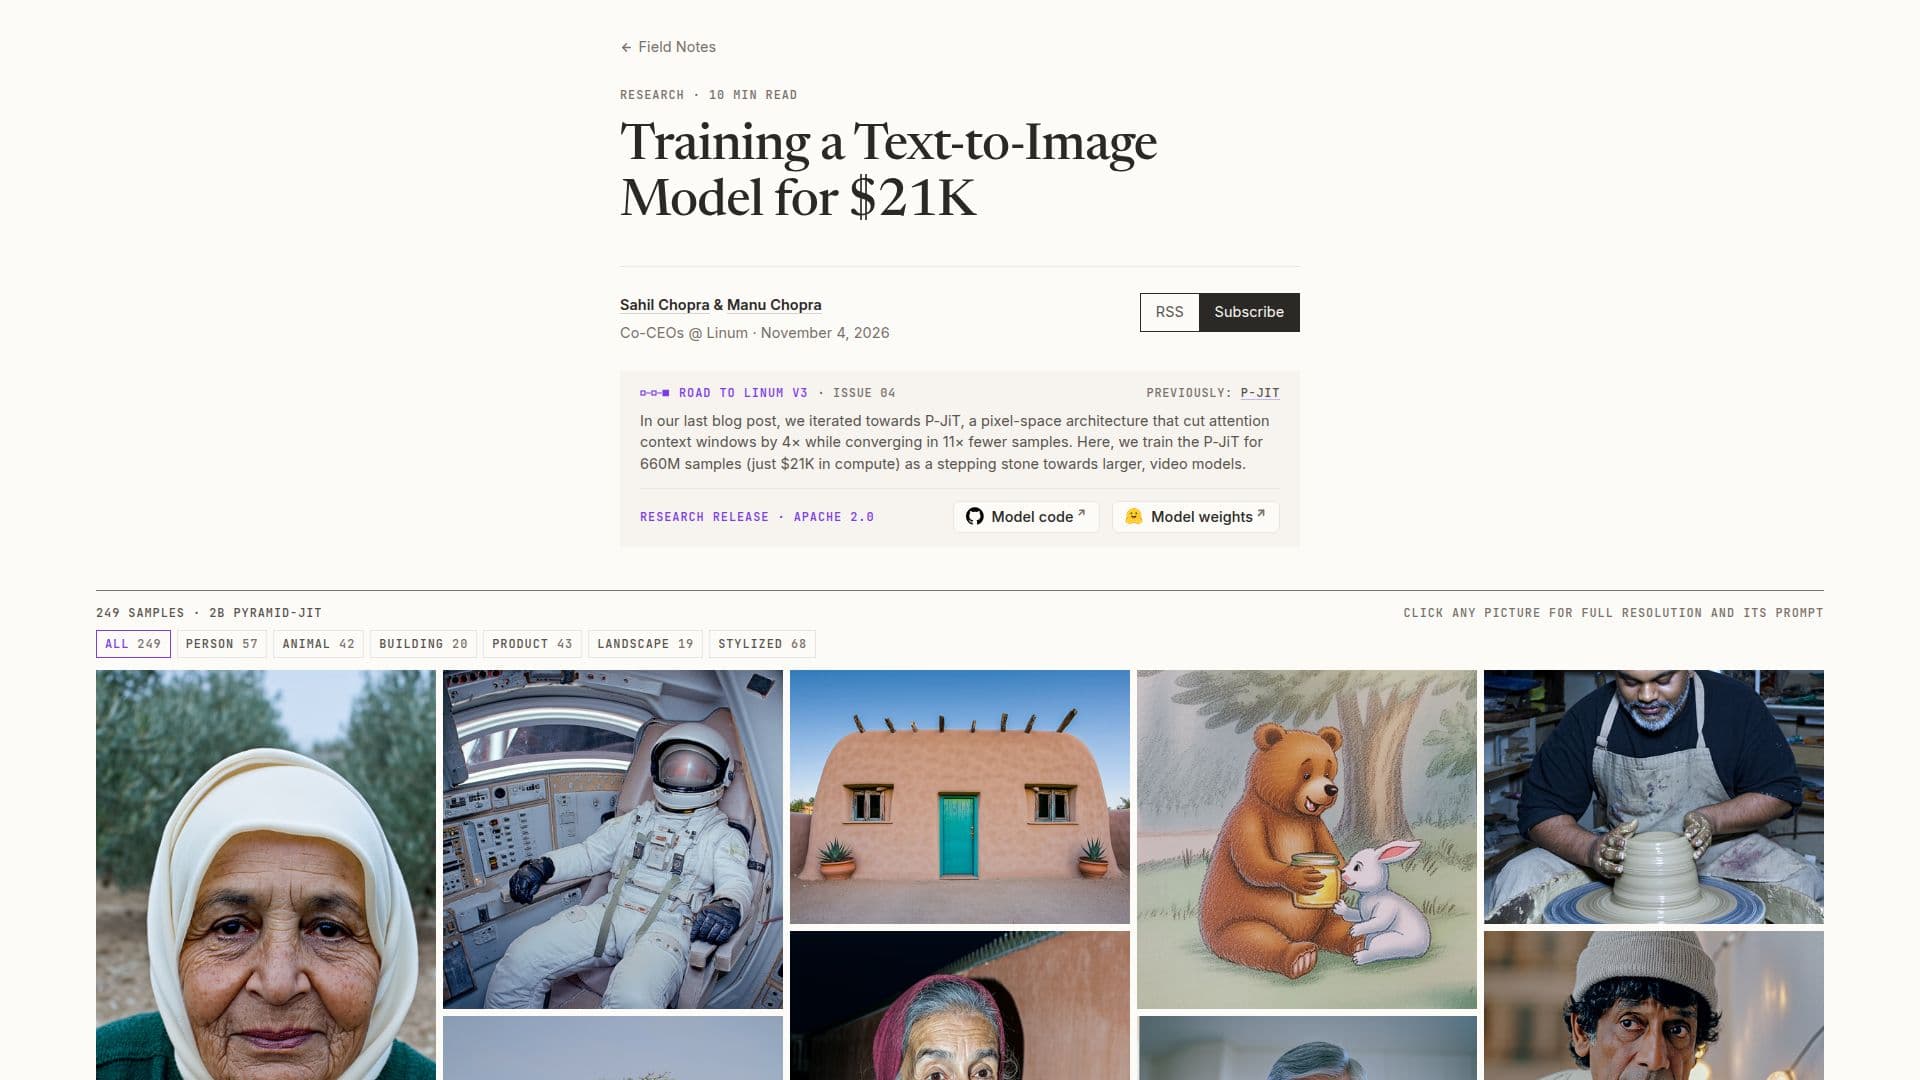
Linum P-JiT is an experimental text-to-image model developed by Linum, a two-person research lab dedicated to training generative video models from scratch. This particular model, a 2B-parameter Pyramid-JiT (P-JiT), serves as a proof-of-concept for their ongoing research into democratizing access to animation through cost-effective and controllable generative tools. The training run for this model cost approximately $21,038, demonstrating the potential for high-quality results at a relatively low computational expense.
Read More
The core innovation behind P-JiT is its ability to achieve more aggressive compression and faster learning by eliminating the traditional Variational Autoencoder (VAE) from the diffusion model architecture. Instead, the diffusion model learns a latent space purpose-built for its use case, allowing for greater compression and improved generation. This pixel-space model converges in 11 times fewer samples than Linum v2 and offers four times more aggressive token reduction, representing a 512x512 image with the same number of tokens previously used for a 256x256 image. This translates to a four-fold reduction in the attention context window, significantly cutting down training and inference costs.
The P-JiT architecture incorporates a text and image processing pipeline, where each modality passes through single-modality "refiner" DiT blocks before merging into a stream of 22 identical DiT blocks. The text representation is derived from a frozen Qwen3.5-4B model, while images are split into 32x32 patches and compressed into a 1024-dimensional space. The model also features PixelREPA readouts aligned to DINOv3-L and additional linear readout heads along the trunk to accelerate convergence by predicting low-resolution versions of the final image.
Training was conducted in several stages, starting at 512x512 resolution for 610 million samples and then transitioning to 1024x1024 resolution for 50 million samples. A curriculum over the noise schedule was employed, initially concentrating on high noise to learn basic structure, then widening the distribution for fine-grained details. Post-training involved a variant of Finite Difference Flow Optimization (FDFO) with JEV-Image and human-in-the-loop judges. While the model shows promising results, it has limitations, particularly with full-body generation, multiple entities, multi-person interactions, and world knowledge, which are common for models of its size. It was not trained with images of rendered text, thus cannot generate text or posters.
- CategoryAI Models & LLMs
- Pricing ModelOpen source
- DeploymentCloud
- PlatformsWeb
Linum P-JiT's Core Features
Pyramid-JiT (P-JiT) Architecture: Novel pixel-space model for efficient generation
2B-Parameter DiT: Core diffusion transformer model size
4B Text Encoder: Utilizes a frozen Qwen3.5-4B model for text representation
VAE-Free Design: Eliminates VAE for more aggressive compression and faster learning
4x Token Reduction: Represents 512x512 images with 4x fewer tokens than Linum v2
11x Faster Convergence: Achieves results with significantly fewer training samples
Multi-Stage Training: Progresses from 512x512 to 1024x1024 resolution
Curriculum Noise Schedule: Adapts noise distribution for structure and detail learning
PixelREPA Readouts: Aligns latent space to DINOv3-L for improved detail learning
Linear Readout Heads: Predicts clean images at quarter and half resolution for accelerated convergence
Finite Difference Flow Optimization (FDFO): Utilized for post-training refinement
Apache 2.0 License: Weights are released under an open-source license
Cost-Effective Training: Achieved high-quality results for approximately $21K
Focus on Generative Video Research: A step towards future video models
How to use Linum P-JiT?
Understand Architecture: Review the P-JiT architecture details, including text and image processing flows.
Examine Training Regime: Learn about the multi-stage training process, noise schedules, and resolution transitions.
Explore Model Limitations: Understand the current limitations regarding full-body generation, multiple entities, and text generation.
Access Training Settings: Refer to Appendix A for detailed training parameters and configurations.
Review Cost Breakdown: See the breakdown of pre-training and post-training compute costs.
Analyze Example Failures: Study provided examples of model failures to grasp current capabilities and areas for improvement.
Linum P-JiT's Use Cases
- Text-to-Image Generation Research
- Cost-Effective Model Training
- Generative Video Model Development
- Architectural Innovation Testing
- Open-Source AI Experimentation