ToolPotion
AI Advisor
Submit a Tool (Free)

Flide

Flide is a high-performance inference infrastructure designed for Jev-style decision models. It accelerates decision inference by forking a single state into all its questions within one forward pass, ensuring each question receives an answer identical to what it would get if asked alone. This approach significantly boosts throughput and maintains high accuracy for complex decision-making processes.

Visit Website
Share
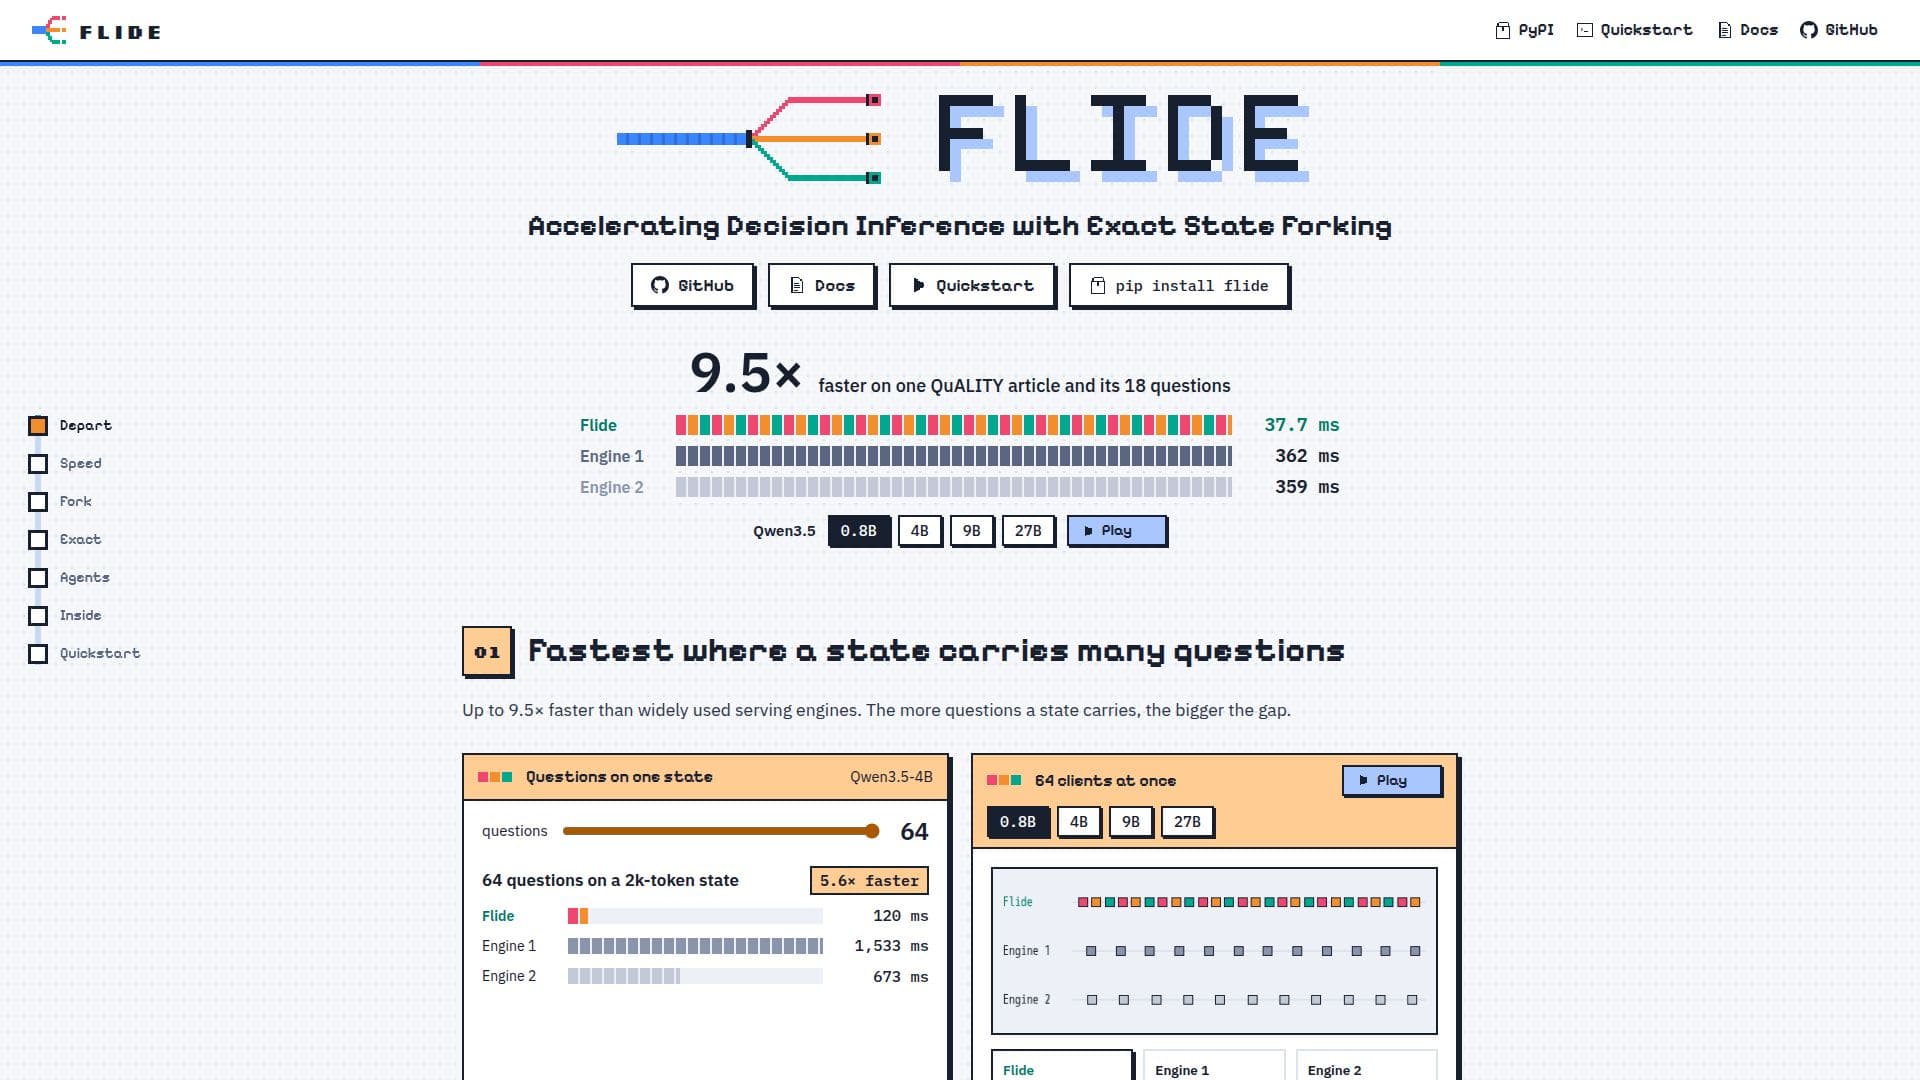
Flide screenshot
Flide screenshot

Flide is an advanced inference infrastructure specifically engineered to accelerate Jev-style decision models. Its core innovation lies in its ability to perform exact state forking, allowing a single input state to be processed for multiple questions in one forward pass. This means the state is read only once, and then efficiently forked, ensuring that every question receives the precise answer it would obtain if it were asked in isolation.

Read More

This unique architecture provides substantial performance gains, with Flide demonstrating up to 9.5 times faster inference compared to widely used serving engines like vLLM and SGLang. The performance advantage becomes even more pronounced as the number of questions associated with a given state increases. For instance, with 64 questions on a 2k-token state, Flide achieves a 9.5x speedup and 2.2x higher throughput with 64 clients.

Beyond speed, Flide prioritizes accuracy, staying within 1.1 points of a float32 reference, making it one of the closest engines to a ground truth reference. It supports a variety of models, including chat models based on Qwen3.5 and Gemma 4, as well as OneJev models. Flide also handles hybrid models, where Gated DeltaNet layers ensure each question starts from the exact state of the shared context. The system offers a `--batch-invariant` option, guaranteeing that a request yields the same bits regardless of how it is batched.

Installation is straightforward via pip, and it supports serving with prebuilt kernels for various NVIDIA GPUs, including A40, A10, RTX 30, H100, and H200. Flide exposes the same `/v1/systemone` API as vLLM and SGLang, providing probabilities for every option in the answer. It supports multimodal inputs, including text, images, and video, depending on the backbone model. Features like FP8 quantization for Qwen3.5 on Ada, Hopper, and Blackwell GPUs, and a session cache for resuming agent states, further enhance its capabilities.

  • CategoryMLOps & Model Deployment
  • DeploymentSelf-hosted
  • PlatformsWeb

  • Exact State Forking: Processes one state for all questions in a single forward pass.

  • Accelerated Inference: Up to 9.5x faster than other serving engines.

  • High Throughput: Achieves 2.2x throughput with 64 clients on specific benchmarks.

  • Float32 Reference Proximity: Stays within 1.1 points of a float32 reference for accuracy.

  • Batch Invariance: Ensures consistent results regardless of batching with `--batch-invariant`.

  • ForkAttention Mechanism: Each question reads its state in place, as if asked alone.

  • Exact on Hybrid Models: Supports Gated DeltaNet layers for precise context handling.

  • One Flat Stream Processing: Runs requests as a single token stream replayed by CUDA graphs.

  • vLLM/SGLang Compatible API: Uses the `/v1/systemone` API standard.

  • Prebuilt Kernels: Optimized for NVIDIA A40, A10, RTX 30, H100, and H200 GPUs.

  • Model Backbones: Supports Qwen3.5 (0.8B, 2B, 4B, 9B, 27B) and Gemma 4 (E2B, E4B, 12B, 26B-A4B, 31B).

  • Multimodal Inputs: Handles text, images, and video inputs.

  • FP8 Quantization: Runs Qwen3.5 in FP8 on Ada, Hopper, and Blackwell GPUs.

  • Session Cache: Keeps earlier states for agents to resume from (e.g., `--session-cache-gb 40`).

  • Frontend Processes: Supports running HTTP, rendering, and tokenizing in separate processes for many clients.

  1. Install Flide: Use pip to install the Flide package.

  2. Start a Server: Run `flide serve` to start the inference server, optionally specifying `--host`.

  3. Configure Models: Serve chat models like Qwen3.5 or Gemma 4 directly, or merge Open-Jev adapters.

  4. Send Requests: Interact with the server using the `/v1/systemone` API to send states and questions.

  5. Process Multimodal Inputs: Include image paths in the state and send media for models supporting images.

  • Accelerated Decision Models
  • Multimodal Inference
  • Consistent Batch Processing
  • Agent State Management
  • High-Performance LLM Serving
  • Research & Development

Flide Reviews

Loading...

Popular AI Tools Like Flide

vLLM

AI Apps

vLLM is a high-throughput and memory-efficient inference and serving engine for Large Language Models (LLMs). It enables faster deployment of AI models with state-of-the-art…

MLOps & Model Deployment
View Tool

AI Apps

High-throughput and memory-efficient inference and serving engine for Large Language Models (LLMs). It enables faster deployment of AI models with state-of-the-art…vLLM is a high-throughput and memory-efficient inference and serving engine for Large Language Models (LLMs). It enables faster deployment of AI models with state-of-the-art…

MLOps & Model Deployment
See the Top 250 AI Apps

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
View Tool

A high-speed AI inference provider that serves models on purpose-built ASIC infrastructure through an OpenAI-compatible API, offering low time-to-first-token and high throughput…

MLOps & Model Deployment
See the Top 250 AI Apps

Inference.net provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…

MLOps & Model Deployment

Ranked #78 for Fine-tuning AI models

View Tool

Provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…Inference.net provides infrastructure for AI-native teams to run, monitor, and optimize AI workloads. It offers blazing fast inference for open-source, custom, and fine-tuned…

MLOps & Model Deployment
Ranked #78 for Fine-tuning AI models

Jev AI

AI Apps

Jev AI is a decision intelligence tool for software teams, offering a fast AI model with no waitlist. It transforms real-world state into structured, probability-backed decisions,…

AI DevOps & Cloud Tools
View Tool

AI Apps

Decision intelligence tool for software teams, offering a fast AI model with no waitlist. It transforms real-world state into structured, probability-backed decisions,…Jev AI is a decision intelligence tool for software teams, offering a fast AI model with no waitlist. It transforms real-world state into structured, probability-backed decisions,…

AI DevOps & Cloud Tools
See the Top 250 AI Apps

JevModel

AI Apps

JevModel is a platform that uses the Jev model for structured AI decisions, offering Choice, Score, and Noul outputs. It allows users to test text or JSON, build decision flows,…

Machine Learning Platforms
View Tool

AI Apps

Platform that uses the Jev model for structured AI decisions, offering Choice, Score, and Noul outputs. It allows users to test text or JSON, build decision flows,…JevModel is a platform that uses the Jev model for structured AI decisions, offering Choice, Score, and Noul outputs. It allows users to test text or JSON, build decision flows,…

Machine Learning Platforms
See the Top 250 AI Apps

Morph

AI Apps

An inference platform built for coding agents, offering fast frontier models plus specialized models for code search, applying edits, context compaction, and monitoring through…

MLOps & Model Deployment
View Tool

AI Apps

An inference platform built for coding agents, offering fast frontier models plus specialized models for code search, applying edits, context compaction, and monitoring through…

MLOps & Model Deployment
See the Top 250 AI Apps

vLLM

AI GitHub Repos

vllm-project/vllm is a high-throughput and memory-efficient inference and serving engine designed for large language models (LLMs). It optimizes performance while minimizing…

MLOps & Model Deployment

Ranked #23 in AI GitHub Repos

View Tool

AI GitHub Repos

High-throughput and memory-efficient inference and serving engine designed for large language models (LLMs). It optimizes performance while minimizing…vllm-project/vllm is a high-throughput and memory-efficient inference and serving engine designed for large language models (LLMs). It optimizes performance while minimizing…

FeaturedMLOps & Model Deployment
Ranked #23 in AI GitHub Repos

trnrt

AI GitHub Repos

trnrt is an open-source LLM inference engine designed for AWS Trainium, offering NKI megakernels and supporting a 1M-token context. Developed by RunAnywhere, it provides an…

MLOps & Model Deployment

Ranked #160 in MLOps & Model Deployment

View Tool

AI GitHub Repos

Open-source LLM inference engine designed for AWS Trainium, offering NKI megakernels and supporting a 1M-token context. Developed by RunAnywhere, it provides an…trnrt is an open-source LLM inference engine designed for AWS Trainium, offering NKI megakernels and supporting a 1M-token context. Developed by RunAnywhere, it provides an…

MLOps & Model Deployment
Ranked #160 in MLOps & Model Deployment
1 of 8