ToolPotion
AI Advisor
Submit a Tool (Free)

Runcrate

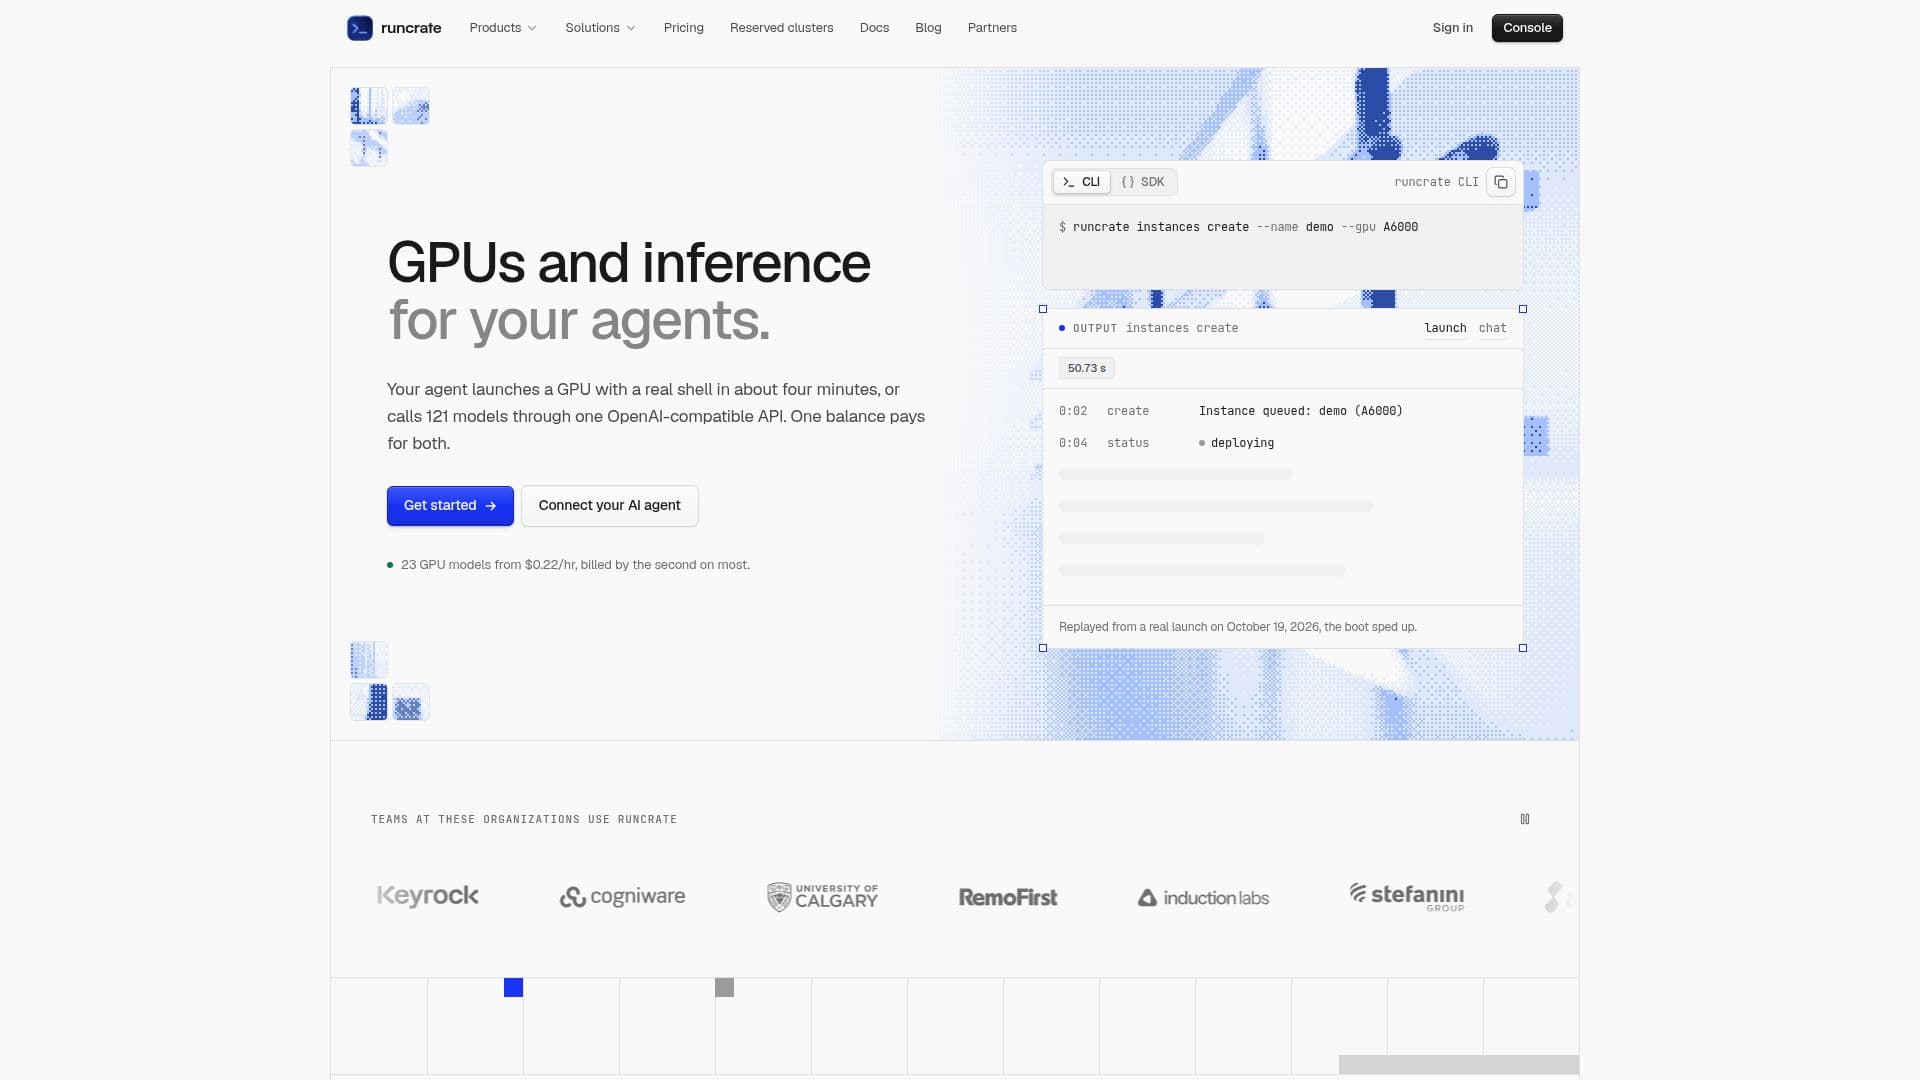
Runcrate provides on-demand GPUs and an inference API for AI teams and agents. It offers a range of GPU models like H100, A100, and RTX 4090, billed per second, with instances running in minutes. Users can fine-tune models, serve LLMs, transcribe audio, and manage GPU instances through a unified platform.

Visit Website
Share
Runcrate screenshot
Runcrate screenshot

Runcrate, developed by Aeonmind, offers a comprehensive AI cloud infrastructure designed for AI and machine learning teams. It provides on-demand access to powerful GPUs, including H100, H200, A100, L40S, and RTX 4090, which are billed per second for most models. GPU instances can be launched and become operational within minutes, eliminating approval queues and quota requests.

Read More

The platform also features an OpenAI-compatible inference API, allowing users to call 121 different models for various tasks such as text generation, vision, image processing, video, speech, transcription, and embeddings. This unified API simplifies model integration and usage, with a single balance covering both GPU usage and model inference.

Runcrate supports a wide array of AI development activities. Users can fine-tune open models like Llama, Mistral, or Qwen with their own data using LoRA, serve open-source LLMs on dedicated GPUs with vLLM, and transcribe audio and video files at scale using the Whisper API. The platform also facilitates running ComfyUI on RTX 4090 instances and developing RAG pipelines by embedding documents and using chat models for answers.

For data persistence, Runcrate offers storage volumes that keep code, data, and checkpoints between instances, ensuring work is not lost when GPUs are terminated. Billing is precise, starting only when an instance is running and typically charged by the second, with no charges for boot time. The platform integrates with tools like Claude Code, Codex, and Cursor, allowing agents to launch and manage GPU instances directly.

Runcrate's pricing model includes per-second billing for GPU instances, per-token pricing for inference API calls, and monthly rates for storage volumes. Prepaid options are available for GPUs and inference, and users can reserve multi-node clusters for longer-term projects. The company's vision is to make AI development cheaper and more accessible by removing infrastructure bottlenecks and promoting open models.

  • CategoryMachine Learning Platforms
  • Pricing ModelPay-as-you-go
  • DeploymentCloud
  • PlatformsWeb

  • On-demand GPU instances (H100, H200, A100, L40S, RTX 4090)

  • Per-second billing for most GPUs

  • OpenAI-compatible inference API with 121 models

  • Fast GPU instance deployment (typically within minutes)

  • Support for fine-tuning LLMs (Llama, Mistral, Qwen) with LoRA/QLoRA

  • Serve open-source LLMs on dedicated GPUs with vLLM

  • Whisper API for audio and video transcription

  • Storage volumes for persistent data across instances

  • Unified account and balance for all products (GPUs, inference, storage)

  • Integration with AI agents and developer tools (Claude Code, Codex, Cursor)

  • Prepaid options and reserved clusters available

  • No billing during GPU boot time

  • Access to Jupyter and VS Code in the browser

  • Ready images for fine-tuning and serving

  • Auto-recharge for credit threshold management

  1. Connect: Add Runcrate to your preferred tool (Claude Code, Codex, Cursor, or terminal) with one command.

  2. Sign In: Approve access through your browser, without needing to paste a key.

  3. Launch GPU: Ask your agent to launch a specific GPU with a desired crate, e.g., "Launch an H100 with the Finetune crate."

  4. Configure Resources: Select your GPU model and configure necessary resources.

  5. Deploy: Launch the instance; billing starts when the GPU instance is running.

  6. Manage: Deploy, manage, and terminate GPU instances directly from the terminal or integrated tools.

  7. Utilize: Use the GPU for training, serving models, or call models via the OpenAI-compatible API.

  8. Store Data: Keep your work between instances using persistent storage volumes.

  • Model Training
  • AI Inference
  • Fine-tuning LLMs
  • RAG Pipelines
  • AI Agent Operations
  • Image and Video Generation
  • Speech and Audio Processing
  • Computer Vision Tasks
  • Data Processing
  • Research and Experiments

Runcrate Reviews

Loading...

Popular AI Tools Like Runcrate

A specialized AI inference and integration provider that hosts open, proprietary, and custom models behind one OpenAI-compatible API, with pay-as-you-go pricing, higher rate…

Machine Learning Platforms
View Tool

A specialized AI inference and integration provider that hosts open, proprietary, and custom models behind one OpenAI-compatible API, with pay-as-you-go pricing, higher rate…

Machine Learning Platforms
See the Top 250 AI Apps

GMI Cloud

AI Apps

GMI Cloud offers high-performance GPU cloud infrastructure for AI workloads. It supports serverless inference, dedicated GPU clusters, and bare metal AI infrastructure, providing…

MLOps & Model Deployment

Ranked #74 in AI DevOps & Cloud Tools

View Tool

AI Apps

Offers high-performance GPU cloud infrastructure for AI workloads. It supports serverless inference, dedicated GPU clusters, and bare metal AI infrastructure, providing…GMI Cloud offers high-performance GPU cloud infrastructure for AI workloads. It supports serverless inference, dedicated GPU clusters, and bare metal AI infrastructure, providing…

MLOps & Model Deployment
Ranked #74 in AI DevOps & Cloud Tools

CloudGPU

AI Apps

CloudGPU offers on-demand GPU rentals and an OpenAI-compatible API for various models, all managed through a single prepaid balance. It provides flexible billing by the minute and…

AI DevOps & Cloud Tools

Ranked #94 for Fine-tuning AI models

View Tool

AI Apps

Offers on-demand GPU rentals and an OpenAI-compatible API for various models, all managed through a single prepaid balance. It provides flexible billing by the minute and…CloudGPU offers on-demand GPU rentals and an OpenAI-compatible API for various models, all managed through a single prepaid balance. It provides flexible billing by the minute and…

AI DevOps & Cloud Tools
Ranked #94 for Fine-tuning AI models

Runware

AI Apps

Runware is a generative AI inference platform that provides one unified API for image, video, audio, 3D, LLM, and vision models. It offers 400K+ models, managed infrastructure,…

MLOps & Model Deployment
View Tool

AI Apps

Generative AI inference platform that provides one unified API for image, video, audio, 3D, LLM, and vision models. It offers 400K+ models, managed infrastructure,…Runware is a generative AI inference platform that provides one unified API for image, video, audio, 3D, LLM, and vision models. It offers 400K+ models, managed infrastructure,…

MLOps & Model Deployment
See the Top 250 AI Apps

Ertas AI

AI Apps

Ertas AI enables users to build custom AI models for on-device deployment in iOS, Android, or desktop apps. It offers a privacy-first platform with zero per-inference cost,…

Machine Learning Platforms
View Tool

AI Apps

Enables users to build custom AI models for on-device deployment in iOS, Android, or desktop apps. It offers a privacy-first platform with zero per-inference cost,…Ertas AI enables users to build custom AI models for on-device deployment in iOS, Android, or desktop apps. It offers a privacy-first platform with zero per-inference cost,…

Machine Learning Platforms
See the Top 250 AI Apps

deAPI

AI Apps

deAPI is a unified API for open-source generative AI models, covering image generation, text-to-speech, transcription, and more. Requests run on a decentralized GPU cloud,…

MLOps & Model Deployment
View Tool

AI Apps

Unified API for open-source generative AI models, covering image generation, text-to-speech, transcription, and more. Requests run on a decentralized GPU cloud,…deAPI is a unified API for open-source generative AI models, covering image generation, text-to-speech, transcription, and more. Requests run on a decentralized GPU cloud,…

MLOps & Model Deployment
See the Top 250 AI Apps

Massed Compute offers on-demand NVIDIA cloud GPUs, from B300 to A30, with pre-installed CUDA and no bandwidth caps. Pay hourly with no contracts, and deploy AI workloads in…

Machine Learning Platforms
View Tool

Offers on-demand NVIDIA cloud GPUs, from B300 to A30, with pre-installed CUDA and no bandwidth caps. Pay hourly with no contracts, and deploy AI workloads in…Massed Compute offers on-demand NVIDIA cloud GPUs, from B300 to A30, with pre-installed CUDA and no bandwidth caps. Pay hourly with no contracts, and deploy AI workloads in…

Machine Learning Platforms
See the Top 250 AI Apps

The Local AI Playground is a free, open-source native app for running AI models offline and in private. It simplifies AI inferencing with a Rust backend, requiring no GPU. Manage…

Machine Learning Platforms
View Tool

The Local AI Playground is a free, open-source native app for running AI models offline and in private. It simplifies AI inferencing with a Rust backend, requiring no GPU. Manage…

Machine Learning Platforms
See the Top 250 AI Apps
1 of 8