Description
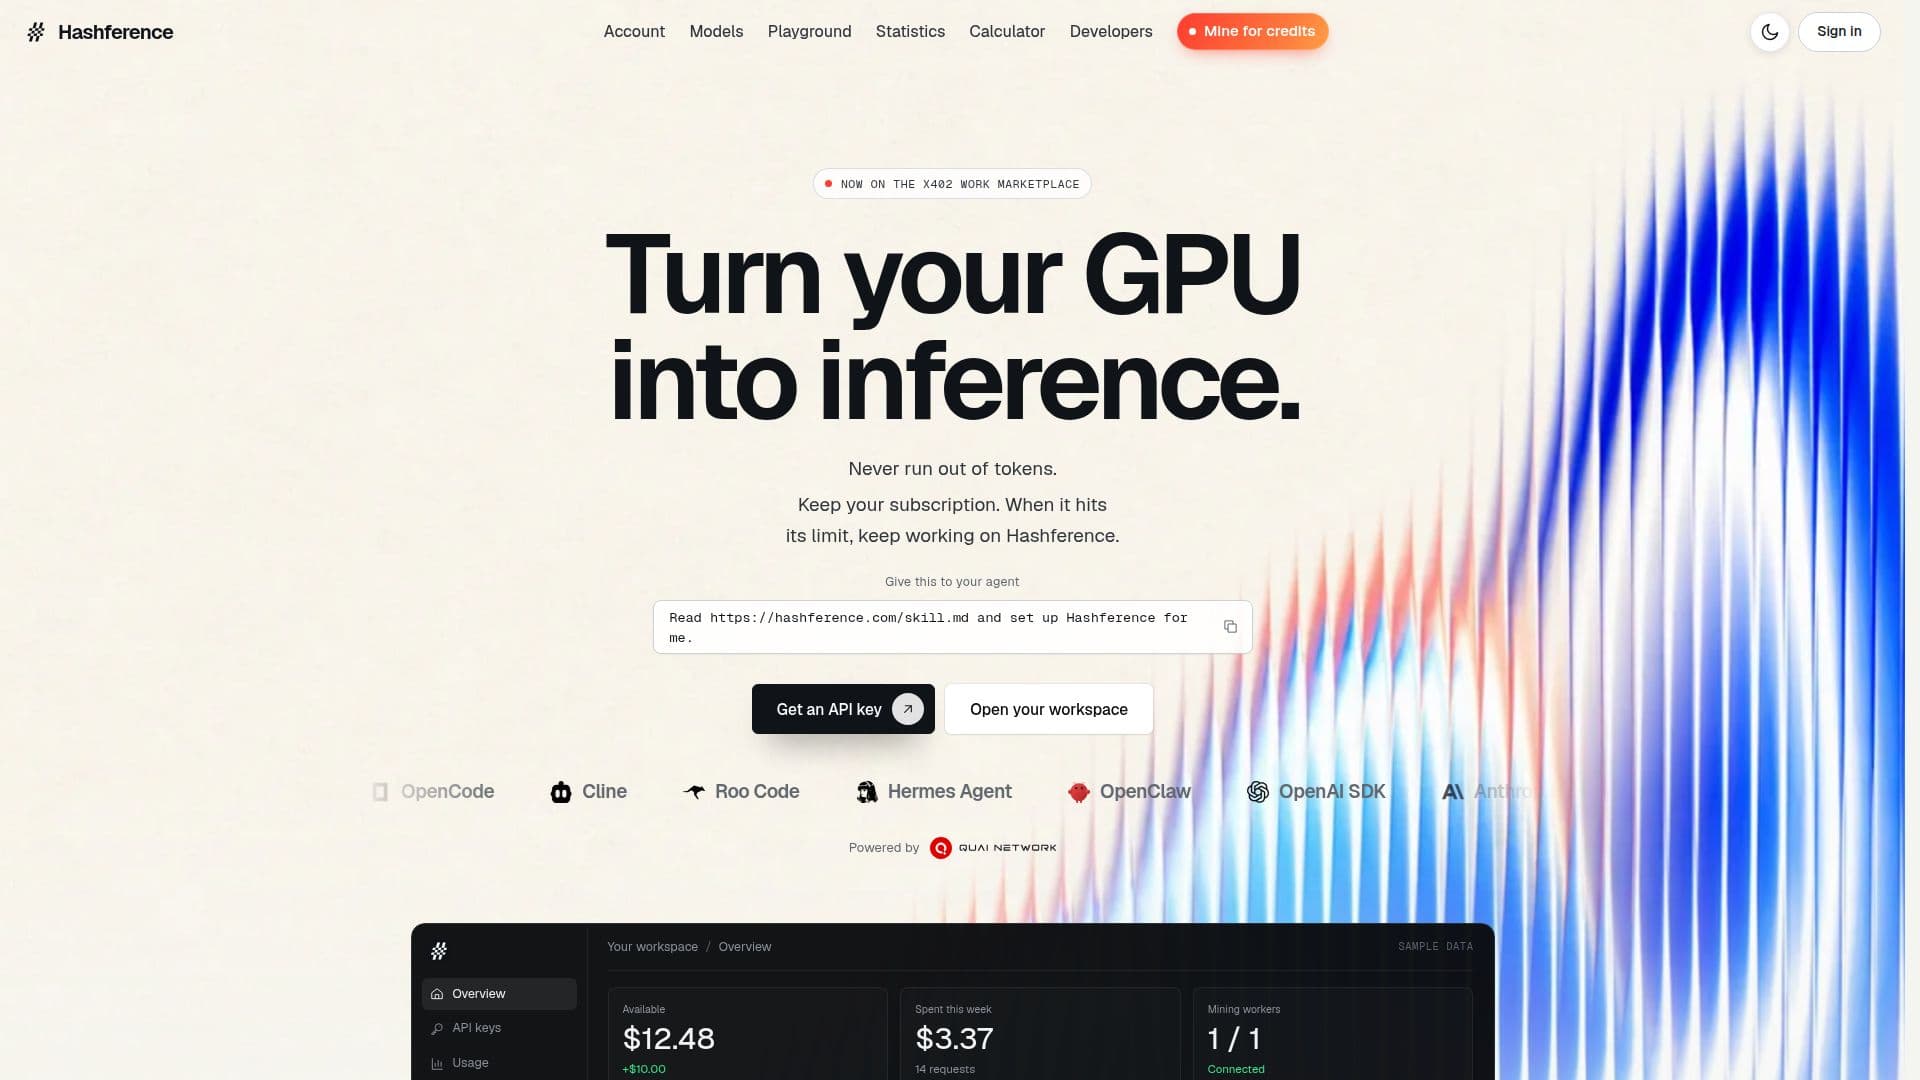
Hashference offers a flexible and private API solution for accessing a range of open AI models, including DeepSeek, Qwen, GLM, Kimi, and Claude. It is designed to be compatible with existing OpenAI and Anthropic SDKs, allowing developers to integrate it seamlessly into their current tools and workflows. The platform addresses the common issue of running out of tokens by providing multiple funding options, ensuring continuous access to AI inference capabilities.
Read More
One of Hashference's distinctive features is its diverse payment system. Users can fund their API keys by purchasing credits with cryptocurrencies such as QUAI or stablecoins. Alternatively, they can mine credits using their own hardware, including CPUs, GPUs, and ASICs (SHA-256 for Bitcoin miners, Scrypt for Litecoin/Dogecoin miners, and KawPoW for Ravencoin-style GPU miners). Accepted shares from mining directly convert into AI credits, eliminating payout thresholds and withdrawal fees often associated with traditional mining pools. For single requests without an account or balance, Hashference supports a unique "pay per request" model using x402 work, where an agent solves a small computational puzzle to cover the cost.
The service prioritizes user privacy, requiring no email or KYC (Know Your Customer) for account creation. It also implements a strict zero-retention policy for prompts and responses, meaning user data is not stored in its databases or logs. Requests to hosted models are routed through endpoints with zero data retention policies, and any potentially identifying fields are removed before reaching the provider. Billing records only metadata like model used, token counts, cost, and duration, without linking to IP addresses or browser details.
Hashference also offers a rate limit fallback mechanism for tools like Claude Code and Codex. When a user's primary subscription hits its usage limit, they can seamlessly switch to a cheaper open model on Hashference to continue their work in the same session. This ensures uninterrupted productivity and provides a cost-effective alternative for ongoing tasks or subagents. The platform supports integration with various developer tools and SDKs, making it a versatile option for accessing and managing AI model inference.
- CategoryAI Models & LLMs
- Pricing ModelPay-as-you-go
- DeploymentCloud
- PlatformsWeb
Hashference's Core Features
OpenAI-compatible API
Anthropic-compatible API
Access to DeepSeek, Qwen, GLM, Kimi, and Claude models
Pay with cryptocurrency (QUAI, stablecoins)
Mine credits with CPU, GPU, or ASIC
Pay per request with x402 work
No email required for account creation
No KYC required for account creation
Zero data retention for prompts and responses
API keys stored as hashes
Rate limit fallback for Claude Code and Codex
Supports subagent model delegation
Works with OpenAI SDK, Anthropic SDK, Vercel AI SDK, LangChain, n8n
Integration with Claude Code, Cursor, VS Code, Codex
How to use Hashference?
Create Workspace: Set up a Hashference workspace to manage API keys and balances.
Fund Workspace: Choose to buy credits with crypto, mine credits with hardware, or use x402 for per-request payments.
Generate API Key: Create an API key within your workspace for authentication.
Configure Tools: Point your existing OpenAI or Anthropic SDKs and tools (e.g., Claude Code, Cursor) to Hashference using provided environment variables.
Make Requests: Use your configured tools to send requests to various AI models available through the Hashference API.
Monitor Usage: Track your API usage and balance, with detailed ledger entries for every request.
Hashference's Use Cases
- Cost-Effective AI Inference
- Uninterrupted AI Workflows
- Private AI API Access
- Developer Tool Integration
- Hardware-Based Credit Earning
- Flexible Payment for AI
- Subagent Model Delegation
- Open Model Experimentation