Description
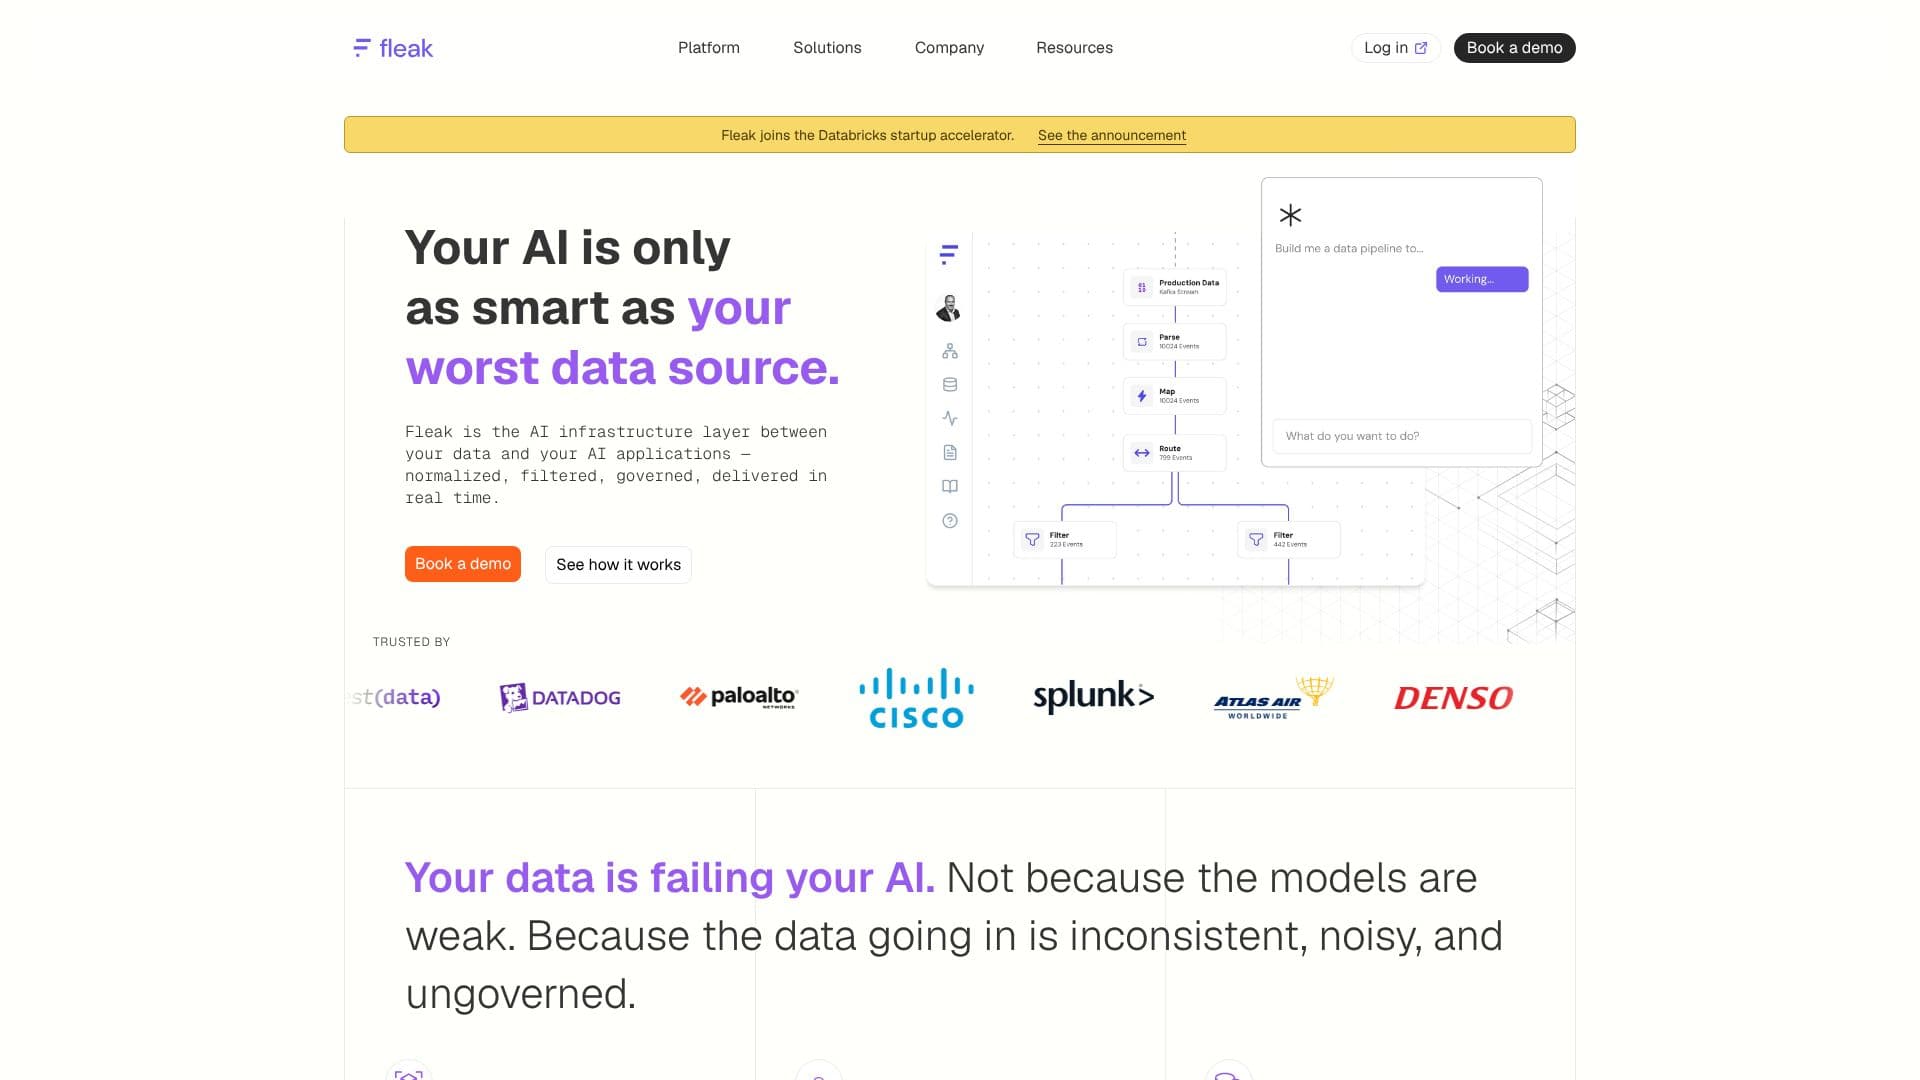
Fleak acts as the AI infrastructure layer situated between your data sources and your AI applications. Its core purpose is to ensure that the data feeding AI models is clean, consistent, and governed, thereby enhancing the intelligence and accuracy of AI outputs. The platform addresses common data challenges such as inconsistency, noise, and lack of governance that often lead AI models to produce incorrect reasoning.
Read More
Fleak operates by evaluating each incoming data point against the specific needs of downstream applications. This value-aware routing ensures that real-time valuable data moves quickly, compliance-sensitive data is stored appropriately, and data with no value is discarded. The system features AI-orchestrated, self-healing pipelines that automatically detect and adapt to upstream schema changes, minimizing manual intervention and maintenance overhead. This significantly reduces the time and effort required to onboard new data sources and manage schema evolution.
Key capabilities include value-aware routing, AI-orchestrated self-healing pipelines, and governed delivery to any destination. Fleak provides fine-grained access control at the data layer, a full audit trail for every transformation, and SOC 2 Type II compliance. The platform boasts impressive performance metrics, including a 6-month reduction in time to first source live compared to traditional pipelines, a 90% integration cost reduction, and a 50% storage cost reduction through deduplication. It can handle millions of events per second in real-time with zero storage required and averages a 3-minute self-heal time for schema drift.
Fleak is designed for organizations struggling with data quality issues that hinder their AI initiatives. This includes companies in cybersecurity, industrial IoT, and financial services, where data accuracy is critical for threat detection, predictive maintenance, and fraud prevention. By normalizing, filtering, and governing data, Fleak ensures that AI tools, LLMs, SIEMs, and data lakes operate on reliable signals rather than noise.
The value proposition of Fleak lies in its ability to turn data into a trusted signal for AI, reduce operational costs, and accelerate AI development cycles. It offers a solution to the common problem where AI performance is limited by the quality of the underlying data, providing a robust and intelligent data layer that adapts to evolving data landscapes.
- CategoryMachine Learning & Data Science
- DeploymentCloud
Fleak AI Data Layer's Core Features
AI-native data layer for AI applications
Normalizes, filters, and governs data in real-time
Value-aware routing of data points
AI-orchestrated, self-healing pipelines
Automated detection and adaptation to schema changes
Fine-grained access control at the data layer
Full audit trail for data transformations
SOC 2 Type II compliance
Connects to any data source (cloud, OT, endpoints, APIs, databases)
Natural language interface for pipeline orchestration
Real-time data delivery with zero storage
Deduplication at ingestion for cost reduction
LLM token cost savings through normalized inputs
How to use Fleak AI Data Layer?
Connect: Link any data source to Fleak without custom connectors.
Orchestrate: Use natural language to describe data transformation goals.
Transform: Fleak identifies event types, branches by intent, and normalizes schemas.
Deliver: Send clean, governed data in specified schemas to any destination in real-time.
Fleak AI Data Layer's Use Cases
- AI Data Preparation
- Real-time Data Processing
- Automated Pipeline Maintenance
- Data Governance for AI
- Cybersecurity Data Normalization
- Industrial IoT Data Unification
- Financial Services Data Integrity
- LLM Data Optimization