Description
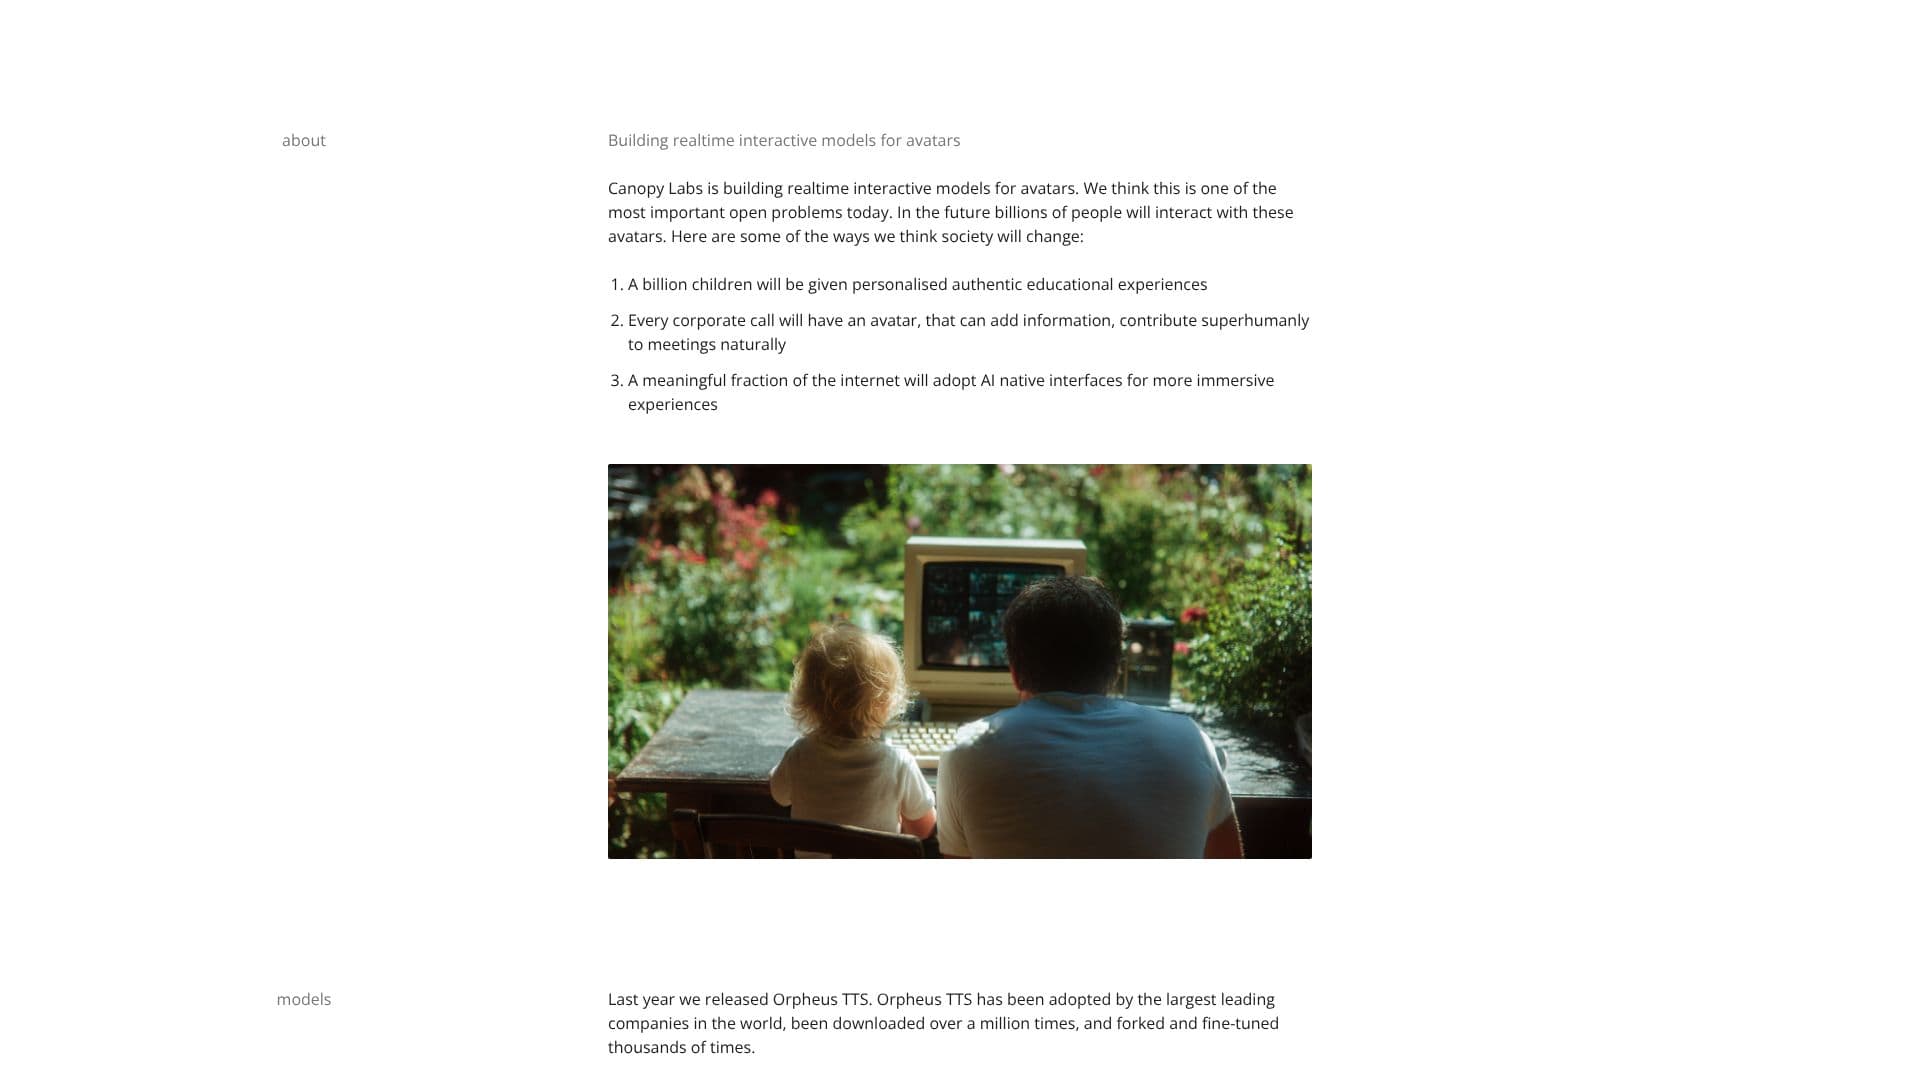
Canopy Labs describes its work as building real-time interactive models for avatars, with the stated goal of developing digital humans that are indistinguishable from real ones. The company frames this as an open research problem it expects to reshape how people interact with software, listing scenarios such as personalized educational experiences and avatars that participate in corporate meetings as directions it expects the technology to enable; these are the company's own stated vision rather than shipped features.
Read More
Canopy Labs previously released Orpheus TTS, which it says has been adopted by companies, downloaded over a million times, and forked or fine-tuned thousands of times (the company's own figures). Since then, Canopy Labs states it has raised $17 million and is developing further speech and avatar models that are not yet public.
The product available today is Orpheus v1, a text-to-speech model offered in two tiers, Base and Flash. It is natively multilingual, supporting English, Hindi, Mandarin, German, Japanese, French, Italian, Portuguese, Russian, Spanish, and Korean, and supports inline stage directions in a script, such as marking a line as slurred or emotional, to shape how it is delivered. Canopy Labs states the model has ultra-low latency, with p99 response time within 30 milliseconds of its baseline. A voice library ships with more than 30 preset voices, and professional or one-shot voice cloning can build a custom brand voice from a few hours of audio.
For enterprise customers, Orpheus can be deployed on-premise or in a private cloud with priority support and an SLA, rather than only through a hosted API. On its site, Canopy Labs demonstrates the model across several preset delivery styles, including a customer-support voice, a self-reflective tone, a theatrical reading, language-learning narration, and a meditation-coach voice, to show the same model handling different registers. Canopy Labs does not publish public pricing for Orpheus on its site.
- CategoryAI Avatar Generators
- DeploymentCloud
- PlatformsWeb
Canopy Labs's Core Features
Text-to-speech model (Orpheus v1) available in Base and Flash tiers
Natively multilingual across eleven languages including English, Hindi, and Mandarin
Supports inline stage directions to control the emotional delivery of a line
Offers professional and one-shot voice cloning from a few hours of audio
Provides a library of more than 30 preset voices
Claims ultra-low latency, with p99 within 30 milliseconds of baseline
Supports on-premise or private-cloud enterprise deployment with SLA support
Researching real-time interactive avatar models beyond its shipped speech product
How to use Canopy Labs?
Pick a model tier: Choose Orpheus v1 Base or Flash depending on latency and quality needs.
Select or clone a voice: Use a library voice or clone a custom one from sample audio.
Write the script: Add stage directions to shape delivery, such as tone or emotion.
Choose a deployment: Use the hosted model or arrange on-premise or private-cloud deployment.
Integrate the output: Feed generated speech into a product, avatar, or support workflow.
Canopy Labs's Use Cases
- Voice product prototyping
- Customer support voices
- Language learning narration
- Enterprise on-premise deployment