Description
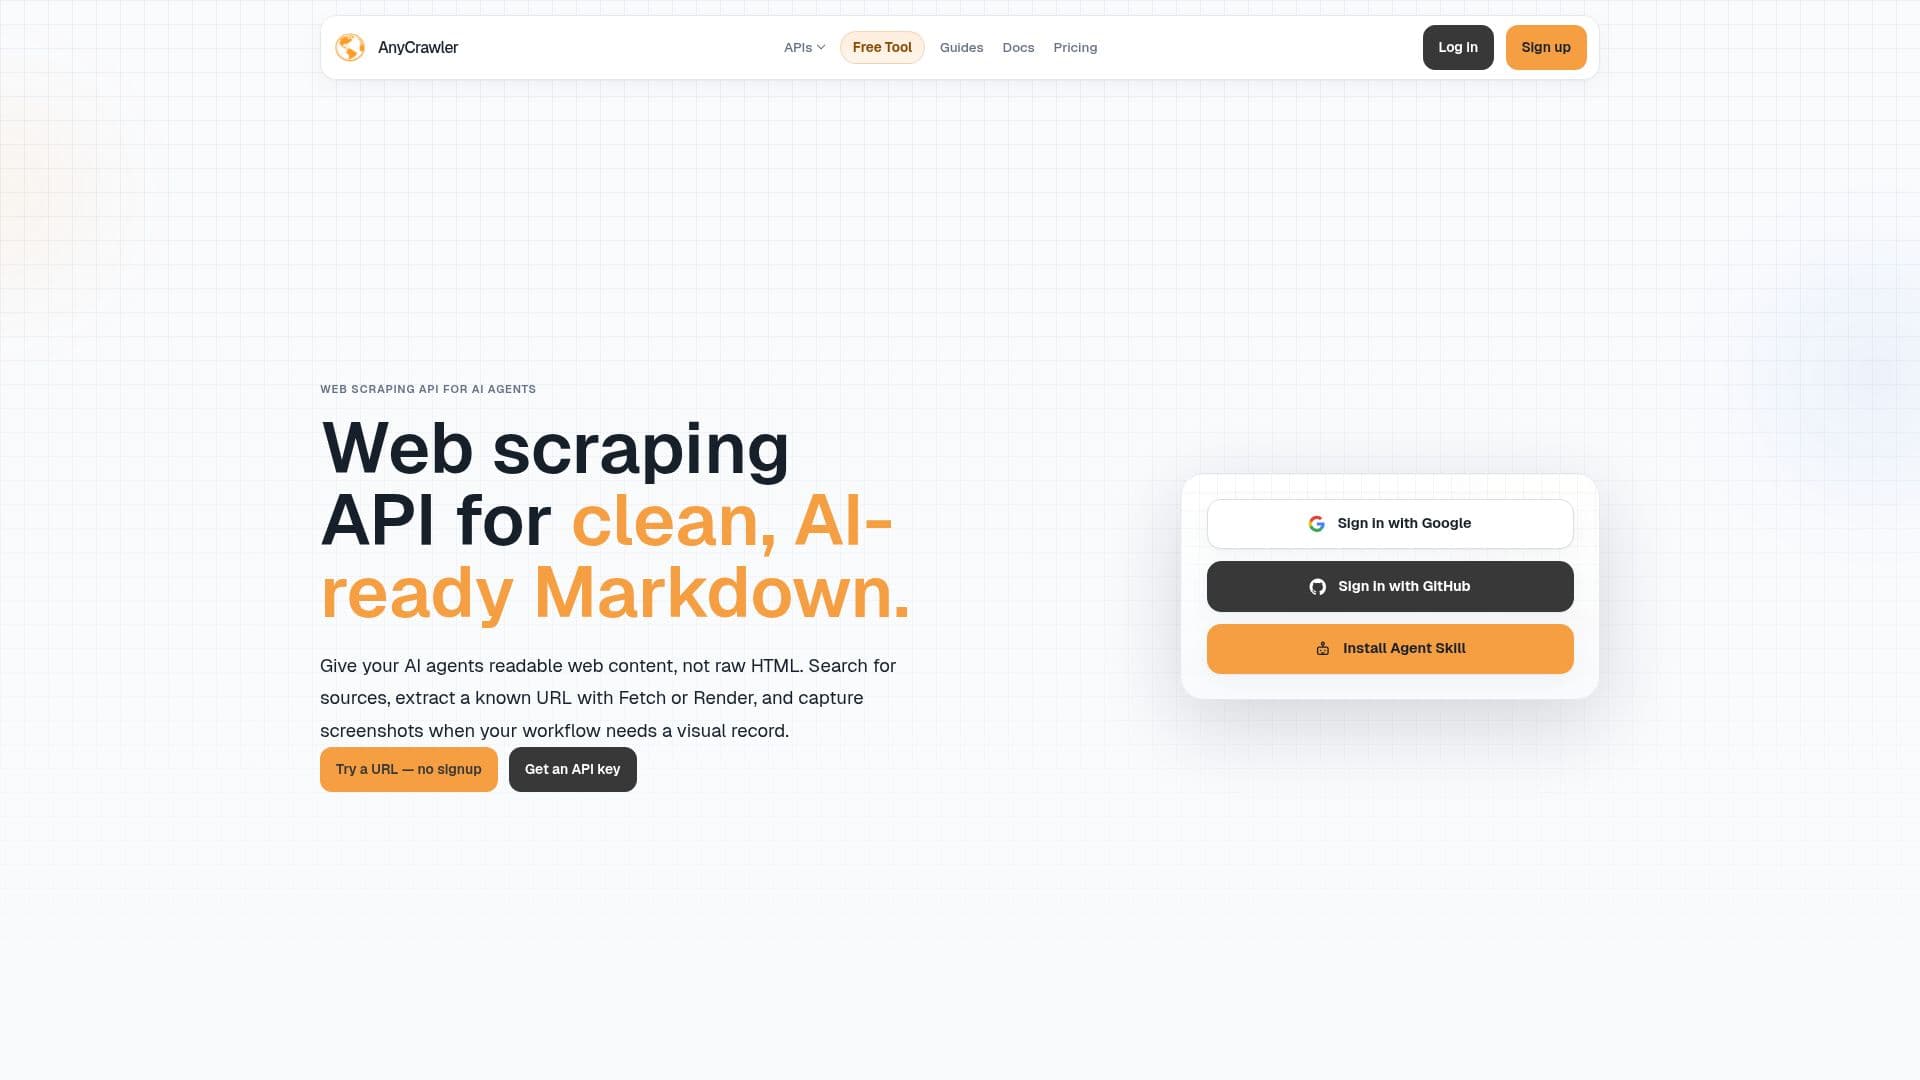
AnyCrawler provides a comprehensive web scraping API specifically engineered for AI agents, RAG systems, research tools, monitoring products, and automation workflows. It offers a unified solution for accessing current web data, eliminating the need for users to manage separate systems for search, crawling, browser rendering, parsing, and usage controls. The API supports a range of operations including searching for source URLs, fetching HTML-first pages, rendering JavaScript-heavy pages in a browser, extracting clean Markdown, and capturing page screenshots.
Read More
The platform is designed to deliver readable web content to AI agents, rather than raw HTML. Users can choose between Fetch and Render modes based on whether the content is available in the initial HTML or requires JavaScript execution. Both modes return structured Markdown output, ensuring consistency for subsequent AI processing steps. Additionally, AnyCrawler includes a web search API to discover candidate pages, news, images, videos, or scholarly sources, allowing users to filter and select the most relevant results for further extraction or screenshot workflows.
AnyCrawler operates on a flexible credit-based billing system, where different web access tasks incur explicit credit costs. This model allows teams to combine capabilities efficiently without being constrained by a flat pricing structure. For instance, search, fetch, render, and screenshot operations each have distinct credit values, ensuring users only pay for the work performed. The service also offers a free tier with 5,000 one-time credits, enabling users to start crawling immediately and validate their workflows.
Built for developers and teams, AnyCrawler provides stable API endpoints, clear response shapes, API keys, and usage logs, facilitating a smooth transition from prototype to production. It aims to simplify the integration of live web access into AI agents, offering a managed layer for search, crawl, render, screenshots, and structured outputs, thereby reducing the need for custom browser infrastructure development.
- CategoryWeb Scraping & Data Extraction
- Pricing ModelFreemium
- DeploymentCloud
- PlatformsWeb
AnyCrawler's Core Features
Web Scraping API for AI Agents
Search for Source URLs
Fetch HTML-First Pages
Render JavaScript Pages
Extract Clean Markdown Output
Capture Page Screenshots
Flexible Credit-Based Billing
API Keys and Request Logs
Usage Controls
Structured Outputs for AI Workflows
Supports RAG Systems
Developer-Friendly API Documentation
Free Tier with 5,000 Credits
Multiple Pricing Plans Available
Browser Concurrency Slots
How to use AnyCrawler?
Sign Up: Create an account to get 5,000 free credits and access the API.
Choose Operation: Select between Search, Fetch, Render, or Screenshot based on your web data needs.
Integrate API: Use the provided API keys and documentation to integrate AnyCrawler into your application or AI agent.
Send Requests: Make API calls to search for URLs, extract content, or capture screenshots.
Process Output: Receive clean Markdown or PNG images ready for your AI workflows or data products.
Monitor Usage: Track credit consumption and manage API keys through your account dashboard.
Scale Workflows: Upgrade to a paid plan for higher monthly credits and increased throughput as your needs grow.
AnyCrawler's Use Cases
- AI Agent Web Access
- RAG System Data Sourcing
- Research Tool Development
- Monitoring Products
- Automation Workflows
- Content Extraction
- Visual Evidence Capture
- Web Discovery