Description
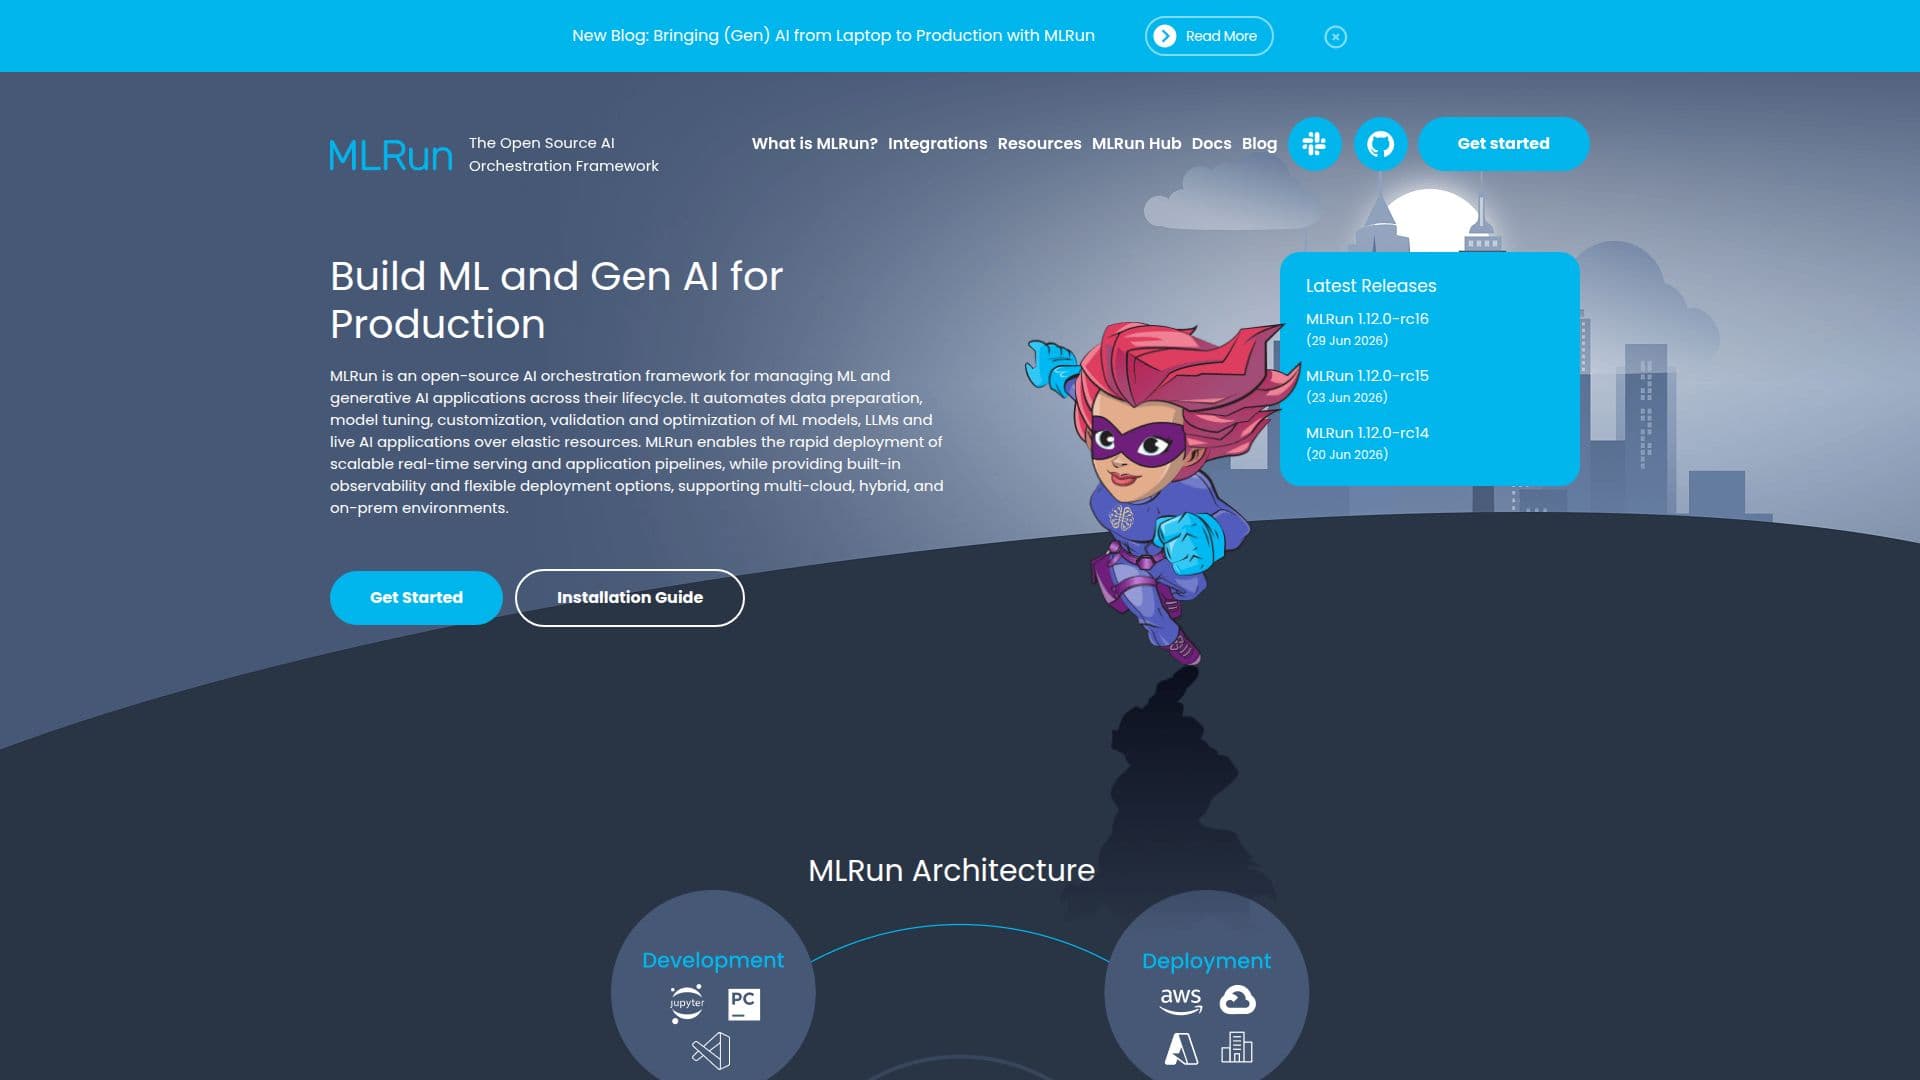
MLRun is an open-source AI orchestration framework designed to manage machine learning (ML) and generative AI applications throughout their lifecycle. It provides an integrative approach to streamline ML pipelines from early development stages to production management. MLRun automates various processes, including data preparation, model tuning, customization, validation, and optimization of ML models and live AI applications over elastic resources.
The platform enables rapid deployment of scalable real-time serving and application pipelines, offering built-in observability and flexible deployment options. It supports multi-cloud, hybrid, and on-prem environments, allowing users to deploy workloads anywhere. MLRun's architecture is open, supporting all mainstream frameworks, managed ML services, and LLMs, and integrates with any third-party service.
MLRun reduces engineering efforts by automating AI pipelines end-to-end, from training and testing to deployment and management in production. It allows for the rapid deployment of real-time serving and application pipelines, automating model training and testing pipelines with CI/CD. The platform also auto-generates batch and real-time data pipelines, reducing computation costs through optimized resource use and seamless workload scaling.
Collaboration is a key feature of MLRun, as it provides a unified technology stack for data engineers, data scientists, and machine learning engineers. This helps break down silos, drive reuse and sharing between roles, and reduce maintenance times. MLRun also emphasizes responsible AI with minimal engineering by auto-tracking data, lineage, experiments, and models, and monitoring models, resources, and data in real-time.
The platform offers end-to-end observability, enabling high-quality governance and reproducibility. It features a serverless application runtime for deploying LLMs with a production-first mindset and includes a built-in LLM gateway for operationalizing and monitoring LLMs, allowing for cost optimization, versioning, and use-case-level observability.
MLRun's Core Features
Open-source AI orchestration framework
Automates data preparation and model tuning
Supports multi-cloud, hybrid, and on-prem environments
Rapid deployment of scalable real-time serving
Built-in observability and flexible deployment options
End-to-end AI pipeline automation
Optimizes resource use to reduce compute costs
Unified technology stack for collaboration
How to use MLRun?
Configure: Set up your client environment
Use: Develop and deploy AI applications
Optimize: Monitor and adjust resource usage
Deploy: Use serverless functions for real-time serving
MLRun's Use Cases
- Real-time serving
- Model tuning
- Data preparation
- Collaboration
- Cost optimization